This is the full developer documentation for XTDB
# Welcome to XTDB
XTDB is an immutable SQL database that reduces the time and cost of building and maintaining safe systems of record. You can read more about our mission [here](/about/mission).
In XTDB there’s no need for handcrafted “audit tables”, or bespoke versioning and filtering logic - just write regular looking SQL and a granular history of all changes will be preserved (and be accessible for whenever you need it!):
2024-01-01
2024-01-05
2024-01-10
Run
Open in xt-play
Unlike regular SQL databases, XTDB retains all history by default and helps businesses to easily and accurately report: ***“Here is the complete history of my data, as I understood it previously, and as I understand it currently.”***
XTDB builds upon the ‘bitemporal’ capabilities defined within [SQL:2011](https://en.wikipedia.org/wiki/SQL:2011) but makes those capabilities both ubiquitous and automatic, without imposing any unnecessary complications on the application schema.
## Learn XTDB in 10 minutes
[Section titled “Learn XTDB in 10 minutes”](#learn-xtdb-in-10-minutes)
To discover the novel features of XTDB, take a look at the interactive [SQL Quickstart](/quickstart/sql-overview).
Or alternatively, you may want to get XTDB [running locally via Docker](/intro/installation-via-docker) first, and then read through the [SQL Quickstart](/quickstart/sql-overview).
## Licensing & Support
[Section titled “Licensing & Support”](#licensing--support)
XTDB is free-to-use and [open source](https://github.com/xtdb/xtdb) under the [MPL license](https://opensource.org/license/mpl-2-0/). For help and support, please join [the community](/intro/community).
Also note that we are actively looking for [Design Partners](https://forms.gle/K2bMsPxkbreKSKqs9), and emails are always welcome: 👋
# Databases in XTDB
Changelog (last updated v2.2)
* v2.2: DETACH DATABASE is asynchronous
`DETACH` returns once the database is hidden from queries; resource teardown continues in the background — see [‘Attaching/Detaching secondary databases’](#attachingdetaching-secondary-databases-v21) below.
Previously `DETACH` blocked until all resources were released, which could deadlock when detaching a Kafka-backed secondary.
No upgrade steps needed; if you script rapid `DETACH X; ATTACH X` flows, handle the new `xtdb/db-being-detached` error by retrying.
* v2.2: single-writer indexing
Indexing within a database is now single-writer — see [‘Database architecture’](#database-architecture) above for how it works today.
Previously, every indexer node independently consumed the log and wrote its own block files to the object store. The design required all indexers to produce byte-identical output, so every feature had to be expressible as a pure, deterministic function of the log — which ruled out anything that wanted to draw per-transaction metadata (e.g. tx-id, system-time) from outside the log.
Single-writer lifts that restriction, unlocking new database topologies like change-data-capture-fed secondaries.
No upgrade steps needed — the user-facing API is unchanged, and existing Kafka topics continue to work.
* v2.1: multi-database support
XTDB now supports multiple databases within a single XTDB cluster.
Previously, an XTDB cluster only had a single database; XTDB clusters were entirely isolated from each other.
v2.1 added `ATTACH DATABASE` and `DETACH DATABASE` statements.
The term ‘database’ is very much overloaded in the database world.
In PostgreSQL, a database is a collection of schemas, which are collections of tables. In MySQL, a database is synonymous with a schema. In SQLite, a database is a single file containing multiple tables. In MongoDB, a database is a collection of collections. The SQL specification calls these a ‘catalog’.
Given this variance, let’s define what this means in XTDB:
* An XTDB database is a collection of tables. Tables may be grouped into ‘schemas’ - XT has relatively little knowledge of schemas beyond tables optionally having two-part names (`schema.table`).
If the schema is not specified, the default schema is named `public`.
* A single database in XTDB shares a [transaction log](/ops/config/log) and [object storage](/ops/config/storage) with other consumers of that database.
* Multiple XTDB nodes that share a ‘primary’ database (named `xtdb`) are considered an XTDB ‘cluster’ - they share a transaction log and object storage for that database.
This is a logical distinction, because XTDB nodes don’t know about each other - there is no communication between them except via the transaction log and object storage.
* XTDB clusters may have any number of attached ‘secondary’ databases, defined by the log and storage configuration.
Each database may be safely shared by multiple XTDB clusters, simply by pointing their log and storage configuration to the same underlying resources - **databases (storage) and clusters (compute) are completely decoupled.**
* When you connect to an XTDB node, as part of the connection string, you will specify a database. (e.g. in JDBC: `jdbc:xtdb://localhost:5432/my-db`).
XTDB supports cross-database queries - queries may refer to tables in other databases by using fully-qualified names (e.g. `FROM database.schema.table`). Unqualified tables are assumed to be from the database you connected to.
* Transactions are submitted to one database and may only refer to tables within that database.
XTDB [guarantees serializability](/about/txs-in-xtdb) within a single database, but not between databases.
## What does this mean for me?
[Section titled “What does this mean for me?”](#what-does-this-mean-for-me)
This decoupling of databases (storage) and clusters (compute) enables a **data mesh architecture** - organize your databases around business domains (orders, customers, products), while each application team runs their own compute cluster. Teams can attach secondary databases to access shared domain data, aligning your data model with your organization’s structure while keeping compute independent.

## Database architecture
[Section titled “Database architecture”](#database-architecture)
Every XTDB database is backed by three pluggable external stores — a **source log** and a **replica log** (typically Kafka topics) and an **object store** (typically S3-compatible). A cluster of XTDB nodes is defined by — and communicates entirely through — these shared resources.

### External stores
[Section titled “External stores”](#external-stores)
XTDB relies on three pluggable external stores — the source log, replica log, and object store. See the [log](/ops/config/log) and [storage](/ops/config/storage) configuration docs for the available implementations.
* Source log
the totally-ordered queue of client writes for this database. Clients append to it via `submitTx` (or SQL DML); the current leader consumes from it.
e.g. a Kafka topic.
* Replica log
the leader’s published output for this database, containing already-resolved transactions in indexed order. Only the current leader writes to it; followers tail it.
e.g. a second Kafka topic, separate from the source log.
* Object store
shared storage for block files.
e.g. AWS S3, Azure Blob Storage, GCP Cloud Storage.
### Node processing
[Section titled “Node processing”](#node-processing)
An XTDB cluster consists of multiple XTDB nodes — each node is a single XTDB process. For each database it serves, a node runs the following sub-components:
* Leader (v2.2+)
for each database, exactly one node in the cluster holds leadership at any given time, elected automatically across the nodes serving that database. If the current leader goes away, another node takes over without operator action — see [‘Ingestion stopped’](/ops/troubleshooting#ingestion-stopped) for how failures are handled.
A leader:
* consumes the source log, resolves each transaction, and publishes the result to the replica log.
* at the end of each block (\~100k rows/15 minutes), writes the block to the object store.
* Follower (v2.2+)
for each database where this node isn’t the leader:
* tails the replica log and applies the already-resolved transactions to its own in-memory index.
* serves queries directly from that index and the blocks in the object store.
* may be promoted to leader when the current leader goes away.
Because followers already hold a current-state index, a follower taking over as leader is effectively a hot-standby promotion — no catch-up replay required.
* Compactor
re-sorts/re-partitions block files in the object store to make them faster to query. Every node participates in compaction — work is picked up at random, with compaction output being byte-identical regardless of which node produced it.
* Query engine
serves queries by reading the object store (via local caches) and recently indexed transactions from the live in-memory index.
For more details on XTDB’s storage and its optimisations, check out the [‘Building a Bitemporal Index’](https://xtdb.com/blog/building-a-bitemp-index-3-storage) series.
## Attaching/Detaching secondary databases (v2.1+)
[Section titled “Attaching/Detaching secondary databases (v2.1+)”](#attachingdetaching-secondary-databases-v21)
Secondary databases are attached to and detached from a cluster by sending transactions to its **primary (`xtdb`) database**.
To attach a database, provide its log and storage configuration in a query to the cluster’s primary database, using the [same YAML configuration format](/ops/config) as in your node configuration:
```sql
-- ensured you're connected to the `xtdb` database
-- here we're using dollar-delimited strings for the config
-- so that we don't have to escape all the single-quotes.
ATTACH DATABASE my_secondary WITH $$
log: !Local
path: 'my-secondary-db/log'
storage: !Local
path: 'my-secondary-db/storage'
mode: 'read-write' -- or 'read-only', v2.2+
$$
```
If you’re using Kafka/S3, for example, you can create a secondary database with another topic on the same Kafka cluster, and either another S3 bucket or another directory within the same bucket:
```sql
-- assuming you've defined the 'my-kafka' cluster in your node configuration
ATTACH DATABASE my_secondary WITH $$
log: !Kafka
cluster: 'my-kafka'
topic: 'xtdb.my-secondary'
storage: !S3
bucket: 'my-bucket'
path: 'my-secondary'
$$
```
* To detach a database, send `DETACH DATABASE my_secondary`.
(v2.2+) `DETACH` returns once the database is no longer queryable; resource cleanup (closing the log subscription, flushing buffers) continues in the background. Re-attaching the same name before cleanup completes returns a transient `xtdb/db-being-detached` conflict — clients should retry.
* **Read-only mode (v2.2+)**: specify `mode: 'read-only'` in the configuration to attach a database read-only. A read-only cluster still indexes transactions locally so it can serve queries, but it won’t write blocks to the object store or compact — it pauses at block boundaries and picks up blocks written by another (read-write) cluster on the same database instead.
## Querying multiple databases
[Section titled “Querying multiple databases”](#querying-multiple-databases)
Once you’ve attached secondary databases to your cluster, you can query them either by re-connecting to that database, or by using fully-qualified names in your queries.
This query pulls in data from both the primary database and our previously created secondary database, **within the same query**:
```sql
-- connected to the primary database
SELECT *
-- refer to public.orders table in my_secondary database
FROM my_secondary.orders o
-- `users` from the primary database
JOIN users u ON (o.user_id = u._id)
```
Table names may take any of the following forms:
* `table` - refers to `public.table` in the current database
* `schema.table` - refers to `schema.table` in the current database
* `database.schema.table` - refers to `schema.table` in the specified database
* `database.table` - refers to `public.table` in the specified database
`schema.table` and `database.table` may be ambiguous, of course - if they both exist, an error will be raised.
# Mission
At [JUXT](https://juxt.pro/), the company behind XTDB, our mission is **to simplify how the world makes software**.
We want XTDB to reduce the time and money it takes for organizations with business-critical, time-oriented requirements to [**safely**](https://www.juxt.pro/blog/kent-beck-podcast/) build and maintain systems of record.
Put another way: XTDB helps when time is complex and correctness matters.
## Time Matters
[Section titled “Time Matters”](#time-matters)
Time, and the passage thereof, is a factor in so many requirements and use-cases.
It’s hard to get right/fast, hard to retro-fit, and full of boilerplate. Data doesn’t always arrive in the right order, or indeed promptly, and often requires later corrections.
We believe existing database technologies (PostgreSQL, SQL Server, MongoDB etc.) leave these problems for their users to work around and solve ad-hoc in their application code.
> Any sufficiently complicated data system contains an ad-hoc, informally-specified, bug-ridden, slow implementation of half of a bitemporal database.
>
> — *“Henderson’s Tenth Law” (with apologies to [Greenspun](https://en.wikipedia.org/wiki/Greenspun%27s_tenth_rule))*
We believe that DIY versioning within databases should be a thing of the past - preserving historical data should not have to be an explicit process which requires conscious design effort and careful development work.
## The Problems
[Section titled “The Problems”](#the-problems)
In this era of rapidly evolving regulatory requirements, we see an increasing number of organizations across all industries feeling frustrated by the friction with [update-in-place](https://www.youtube.com/watch?v=JxMz-tyicgo) databases that don’t support basic auditing requirements.
From GDPR to HIPAA to MiFID II, all kinds of regulatory requirements justify a fundamental level of accuracy and accountability in how your software stack stores and represents key information. The implications extend across the entire transactional to analytical data lifecycle.
This lack of accurate time-based versioning has four main consequences that plague applications working with regulated data:
1. **Inconsistent reporting over historical data** - accurate reporting requires some notion of “time travel” queries, but without a stable *bitemporal* basis enforced by the database ad hoc solutions will inevitably resort to copying snapshots of entire data sets in a search for consistency.
2. **Inadequate auditing & compliance** - audit tables and triggers and change data capture are all workarounds for the absence of basic audit facilities within a database.
3. **Challenging data integration & evolution** - strict schema definitions, update-in-place mutations, and poor support for semi-structured data are all impediments to using relational databases as integration points.
4. **Difficulty of managing SQL with an ad-hoc bitemporal schema** - composing SQL is unnecessarily hard and is a common source of developer friction. Bitemporal versioning makes it harder still.
## The Solution
[Section titled “The Solution”](#the-solution)
XTDB, therefore, is an immutable, time-travel database designed for building complex applications, supporting developers with features that are essential for meeting common regulatory compliance requirements.
Crucially, this is not a trade of convenience for safety. We want both:
* the ease and performance of a traditional update-in-place database, for everyday transactions and queries, *and*
* the safety net of bitemporality, for when you need it.
So `INSERT` is `INSERT`, `UPDATE` is `UPDATE`, `DELETE` is `DELETE` - no temporal filters to remember, and no separate OLAP system and ETL pipeline to keep in step. Queries read “as of now” by default; history is there when you ask for it, rather than something you model explicitly everywhere and pay for in every query and join.
It is built to help solve the hard problems of:
* accurate record keeping (with full ACID transaction support),
* time-travel queries (indeed, XT stands for “across time”), and
* data evolution.
XTDB achieves this by its ubiquitous [‘bitemporal’](https://en.wikipedia.org/wiki/Bitemporal_modeling) time-based versioning of records. It records the history of all changes (particularly UPDATEs and DELETEs, which are normally destructive operations), and by restricting the scope of concurrent database usage, to retain an auditable, linear sequence of all changes.
Beyond the obvious auditing and debugging benefits of retaining change data and prior database states, XTDB’s history-preserving capability presents a robust & stable source of truth - a *‘basis’* - within a wider IT architecture that is unlike anything that most databases can offer.
This matters increasingly where decisions are made autonomously. Every query runs at a basis, and earlier bases stay queryable, so “what exactly did this system see when it made that decision?” has an exact answer that can be reproduced long after the fact.
## Adoption
[Section titled “Adoption”](#adoption)
Adopting XTDB does not require a migration.
Add one data source at a time - direct SQL DML, Postgres, Kafka - and size compute per application. Federation and external sources are what make this practical: they let XTDB sit as a component within a wider data architecture, rather than as a monolith that everything else has to move onto first.
# Time in XTDB
Time, and the passage thereof, is a factor in so many requirements and use-cases.
It’s hard to get right/fast, hard to retro-fit, and full of boilerplate. Data doesn’t always arrive in the right order, or indeed promptly, and often requires later corrections.
We believe existing database technologies (PostgreSQL, SQL Server, MongoDB etc.) leave these problems for their users to work around and solve ad-hoc in their application code.
> Any sufficiently complicated data system contains an ad-hoc, informally-specified, bug-ridden, slow implementation of half of a bitemporal database.
>
> — *“Henderson’s Tenth Law” (with apologies to [Greenspun](https://en.wikipedia.org/wiki/Greenspun%27s_tenth_rule))*
XTDB is built to eliminate the incidental complexities that are normally associated with handling time in a database.
XTDB makes time [simple](https://www.youtube.com/watch?v=SxdOUGdseq4).
## Bitemporality - ‘two times’
[Section titled “Bitemporality - ‘two times’”](#bitemporality---two-times)
Traditionally, databases behave like a spreadsheet (without ‘undo’). When you update a cell, or delete a row, the database updates that data ‘in place’ - the old value is lost. These are called **‘atemporal’** databases - databases which have no built-in concept of row versioning.
Developers with data history or audit requirements usually work around this with well-established but onerous patterns - usually involving either manually updating ‘version’ or validity columns or copying old rows to a separate history table (some may use automatic triggers to achieve this same aim). Some set a ‘deleted’ flag on the rows (a ‘soft delete’).
When they query the database, they have to bear these workarounds in mind - filtering out rows that are no longer valid. Often, they forget!
On the surface, XTDB [behaves like an atemporal database](#bitemporality-in-xtdb). No more “you can’t delete this row, you have to set a flag”, “if you change this row, make sure you make a copy of the original”, “you can’t ‘just’ query this table”, though - you’re allowed to use `SELECT` `UPDATE`, and `DELETE` again, as they were intended! Then, when you really *need* it, the full temporal history remains available and easily queryable.
### System time
[Section titled “System time”](#system-time)
Let’s introduce the first temporal dimension: ‘system time’.
Some databases are starting to support the concept of system-time (**‘unitemporal’** databases) - they track changes to a table, and allow you to view tables as of a time in the past. Users (rightly) have no control over system-time - the database maintains this timeline.
Rather than a single value, every entity in a unitemporal database has a timeline:
* Let’s say we insert a record at time T1 - version 1.
* Later, at time T3, we update that entity to version 2.
* We can then ask the database both “what’s the current state of my entity?”, and “what was the state of my entity at time T2?”
* If we later delete the entity at time T6, it will no longer be returned as the current state, but we can still time-travel to retrieve the previous versions.
The timeline of this entity is therefore:
* absent for time < T1
* version 1 for T1 ≤ time < T3
* version 2 for T3 ≤ time < T6
* absent for time ≥ T6
System time is often represented in a unitemporal database with ‘system from’ and ‘system to’ columns, which represent the time range during which a particular version of a row was current. If a row is considered current ‘until further notice’, the ‘system to’ column is set to null.
So, the timeline of our above entity would be represented in a unitemporal database table as follows:
* Insert at T1 - adds a new row for version 1 with `_system_from` of T1 and `_system_to` of null:
| \_id | \_system\_from | \_system\_to | version |
| ---- | -------------- | ------------ | ------- |
| 123 | T1 | null | 1 |
* Update at T3 - here, it updates the `_system_to` of the previous version to T3, and adds a new row for version 2:
| \_id | \_system\_from | \_system\_to | version |
| ---- | -------------- | ------------ | ------- |
| 123 | T1 | T3 | 1 |
| 123 | T3 | null | 2 |
* Delete at T6 - it updates the `_system_to` of the previous version to T6:
| \_id | \_system\_from | \_system\_to | version |
| ---- | -------------- | ------------ | ------- |
| 123 | T1 | T3 | 1 |
| 123 | T3 | T6 | 2 |
You might also hear system-time referred to ‘transaction time’ or ‘processing time’.
### Valid time
[Section titled “Valid time”](#valid-time)
System time alone doesn’t solve all temporal problems - it’s often necessary to additionally track the time period where these facts are considered valid in the real world.
* If you don’t become aware of an update until later, you’ll want to be able to backdate it to the time it was actually valid.
* You might become aware of an error in the data, and want to correct it retrospectively.
You may even be told about a change in the future:
* Mike e-mails you saying that he’s moving house next week.
* Marketing want to schedule a blog post to go out first thing on Monday.
* The price of one your products is going up next month.
In short, any time you hear the phrase ‘as of’ or ‘with effect from’ in a requirement, the answer is probably ‘valid time’.
Valid time is the second temporal dimension, making the database **‘bitemporal’**.
In practice, valid time is often represented with ‘valid from’ and ‘valid to’ columns (in addition to ‘system from’ and ‘system to’), which represent the time range during which a particular version of a row is considered valid in the real world.
With system-time, we talked about entities each having a read-only ‘timeline’ - with valid-time, each entity gains another, *user-editable* timeline.
#### A worked example
[Section titled “A worked example”](#a-worked-example)
Let’s take the case of Mike’s address:
* Initially, he lives at 123 London Road:
```sql
INSERT INTO addresses RECORDS {_id: 'mike', address: '123 London Road'};
-- using XT's `RECORDS` syntax here - you might otherwise see:
INSERT INTO addresses (_id, address) VALUES ('mike', '123 London Road');
```
* On 13th August, he tells us that ‘with effect from 1st September’ (that magic phrase!), his address will be 84 Bank Street:
```sql
UPDATE addresses FOR VALID_TIME FROM TIMESTAMP '2025-09-01Z'
SET address = '84 Bank Street'
WHERE _id = 'mike';
```
* Then, on 20th August, we send him a letter, so we need to know his address:
```sql
SELECT address FROM addresses WHERE _id = 'mike';
-- => '123 London Road'
-- Here, we implicitly queried 'for system-time as best known, for valid-time as of now'.
-- We could have additionally requested `_valid_from` and `_valid_to`:
SELECT address, _valid_from, _valid_to FROM addresses WHERE _id = 'mike';
-- => '123 London Road', from '2019-11-18', to '2025-09-01'
```
Obviously, we’ve still got to hope the letter gets there on time!
* We could also have queried:
```sql
-- 1. into the future:
SELECT address, _valid_from, _valid_to
FROM addresses FOR VALID_TIME AS OF TIMESTAMP '2025-12-01Z'
WHERE _id = 'mike';
-- => '84 Bank Street', from '2025-09-01', until corrected (represented as _valid_to = 'null')
-- 2. for all valid-time:
SELECT address, _valid_from, _valid_to
FROM addresses FOR ALL VALID_TIME
WHERE _id = 'mike';
-- => '123 London Road', from '2019-11-18', to '2025-09-01'
-- => '84 Bank Street', from '2025-09-01', until corrected
```
#### Behind the scenes
[Section titled “Behind the scenes”](#behind-the-scenes)
Behind the scenes, XTDB is maintaining both the system-time and valid-time timelines for Mike’s address.
If you were to ask for *everything*, you’d see something like this:
```sql
SELECT *, _system_from, _system_to, _valid_from, _valid_to
FROM addresses FOR ALL SYSTEM_TIME FOR ALL VALID_TIME
WHERE _id = 'mike';
```
```plaintext
|------|-----------------|--------------|------------|-------------|------------|
| _id | address | _system_from | _system_to | _valid_from | _valid_to |
|------|-----------------|--------------|------------|-------------|------------|
| mike | 123 London Road | 2019-11-18 | 2025-08-13 | 2019-11-18 | ∞ | (1)
| mike | 123 London Road | 2025-08-13 | ∞ | 2019-11-18 | 2025-09-01 | (2)
| mike | 84 Bank Street | 2025-08-13 | ∞ | 2025-09-01 | ∞ | (3)
|------|-----------------|--------------|------------|-------------|------------|
```
1. The first row shows that, until 13th August, we believed that Mike’s address was going to be 123 London Road until further notice.
2. From 13th August, we knew that Mike’s address was 123 London Road, but we also knew that this was only going to be the case until 1st September.
3. From 13th August, we also knew that Mike’s address would be 84 Bank Street, from 1st September until further notice.
#### In practice
[Section titled “In practice”](#in-practice)
In practice, the vast majority of queries will use the system-time default, ‘as best known’. Within those, again, the vast majority will likely use the valid-time default, ‘as of now’.
When you are looking to query back in time, consider: ‘do I want to see corrections?’.
* Most use cases will want to see those corrections (‘as best known’) - they don’t care that data arrived late and had to be backfilled, or whether there were errors in the initial inserts - they want corrected data. In these cases, use `FOR VALID_TIME ...` to see the curated valid-time timeline.
* Some use cases (e.g. auditing) will need to see the data ‘as we knew it at the time’, *without* subsequent corrections - this is the use case for `FOR SYSTEM_TIME AS OF ...`, to see the immutable system-time timeline.
You might also hear valid-time referred to as ‘business time’, ‘domain time’, ‘application time’, ‘event time’, or ‘effective time’. Hooray for consistency!
### Bitemporality in XTDB
[Section titled “Bitemporality in XTDB”](#bitemporality-in-xtdb)
Bitemporality is ubiquitous in XTDB - every table is bitemporal.
That said, it’s opt-in - by default, using normal SQL queries, XTDB looks like it’s an atemporal database.
For use cases that don’t yet require the full power of bitemporality - here’s how normal inserts, updates, queries and deletes work in XTDB:
```sql
INSERT INTO users (_id, user_name, ...) VALUES (?, ?, ...);
-- providing `_id` and `user_name` as separate parameters
-- to avoid SQL injection attacks.
UPDATE users SET user_name = ? WHERE _id = ?;
SELECT * FROM users WHERE user_name = ?;
DELETE FROM users WHERE _id = ?
```
So far, so good.
Nothing remotely bitemporal-looking here, just what you’d write in a traditional database - and 90% of the time, this is what XTDB applications look like.
But, when you need to ask time-oriented questions, here’s where XTDB’s safety-net kicks in.
These usually take one of the following forms:
1. What’s the current state of the world?
2. What’s the history of my database, as we now know it (i.e. taking subsequent corrections into account)?
3. What’s the history of my database, as we thought it was at the time?
(In our experience, these three categories of questions are in descending order of request frequency, and XTDB optimises accordingly - beneath the surface, we have specific indices to quickly serve current-time queries to get them as close as possible to atemporal performance, and separate indices for historical data.)
To answer these questions, SQL:2011 introduced [an array of new bitemporal primitives](https://dbs.uni-leipzig.de/file/Temporal%20features%20in%20SQL2011.pdf):
1. For category 1: we’ve chosen to make this the default behaviour in XTDB - query as you normally would.
2. For category 2: when selecting from a table, we can specify a valid time period:
```sql
SELECT * FROM users FOR VALID_TIME AS OF DATE '2023-08-01';
SELECT * FROM users FOR VALID_TIME BETWEEN DATE '2023-08-01' AND DATE '2023-09-01';
SELECT * FROM users FOR ALL VALID_TIME;
```
3. For category 3: same, but `SYSTEM_TIME`:
```sql
SELECT * FROM users FOR SYSTEM_TIME AS OF DATE '2023-08-01';
SELECT * FROM users FOR SYSTEM_TIME BETWEEN DATE '2023-08-01' AND DATE '2023-09-01';
SELECT * FROM users FOR ALL SYSTEM_TIME;
```
Inserts, updates and deletes are similar:
* Inserts behave more like an upsert in XTDB. If you `INSERT` a row that already exists, no problem - we’ll effectively update any existing rows (so that they remains accessible in historical queries), and your new row becomes the current row.
* For updates/deletes in the past/future, use the SQL:2011 `FOR PORTION OF VALID_TIME` syntax
```sql
UPDATE users
FOR PORTION OF VALID_TIME FROM DATE '2023-08-01' TO DATE '2023-09-01'
SET user_name = ?
WHERE _id = ?
```
So, for most of the time, for most of your requirements, you can use XTDB like a normal database - but while also being safe in the knowledge that, as your requirements grow, you can incrementally pull in the power of bitemporality when you really need it.
XTDB makes this simple everyday behaviour *easy* and *fast*, and a wide range of harder bitemporal queries *possible*.
For a detailed specification of the available bitemporal syntax in XTDB, see the SQL [transaction](/reference/main/sql/txs) and [query](/reference/main/sql/queries) reference documentation.
# Transactions/Consistency in XTDB
This article describes how transactions and consistency work in XTDB.
Being a ‘log-centric database’, it differs from traditional RDBMSs in a couple of key ways:
1. Transactions that perform writes (“[DML](https://en.wikipedia.org/wiki/Data_manipulation_language) transactions”) to the database are non-interactive.
When you submit a transaction containing [DML](https://en.wikipedia.org/wiki/Data_manipulation_language) statements to XTDB, internally, it wraps up the transaction operations and sends them as an atomic message on a shared log.
Within a transaction, your operations can still read the current state of the database (e.g. `UPDATE table SET version = version + 1 WHERE _id = ?`) - but you can’t mix query statements (e.g. `SELECT`) which return results and DML statements (e.g. `INSERT`/`UPDATE`/`DELETE`/`ERASE`) in the same transaction.
(Where you need to check invariants before committing a DML transaction, see [`ASSERT`](/reference/main/sql/txs#assert))
2. All transactions that perform writes are serialized via a totally-ordered durable log.
This means that XT, internally, has very little locking - this gives us excellent per-thread performance, as well as removing a whole category of bugs/errors.
Combined, these two properties provide straightforward [ACID](https://en.wikipedia.org/wiki/ACID) guarantees.
In more detail, XTDB is heavily inspired by the ‘Epochal Time Model’, as outlined in Clojure and Datomic author Rich Hickey’s talk ‘The Database as a Value’[1](#user-content-fn-1):

## Transaction consistency
[Section titled “Transaction consistency”](#transaction-consistency)
A transaction may be explicitly specified as either `READ ONLY` (a “read-only transaction”) or `READ WRITE` (a “DML transaction”). If not specified, this distinction is inferred from the first statement in the transaction after a `BEGIN`.
A DML transaction may contain only DML statements and ASSERT statements. Transactions are not interactive, and they describe changes atomically.
Within a DML transaction, statements are evaluated sequentially, so later statements see the effects of earlier ones. Any attempt to (e.g.) SELECT within such a transaction will result in an error.
DML transactions in XTDB are serialized via a totally-ordered log - these are then indexed in order, one at a time, on each of the nodes. As a result, they are trivially consistent to the highest isolation level - ‘serializable’.
On the read-side, within a connection, queries are guaranteed to at least see the results of every transaction submitted through that connection. Therefore, if you’re looking to reliably write-then-read, the easiest way to do this is to re-use the same connection for your write and subsequent read.
Between connections, by default, you may not see the results of transactions submitted on other connections immediately - you likely will, but it’s not guaranteed. To ensure that you do see the results of transactions on other connections, XTDB provides an `AWAIT_TOKEN` variable, which you can pass from one connection to another:
```sql
-- on connection A:
BEGIN; -- BEGIN/COMMIT optional
UPDATE ...;
COMMIT;
SHOW AWAIT_TOKEN;
-- "CgsKBHh0ZGISAwoBAQ=="
-- on connection B:
BEGIN READ ONLY WITH (AWAIT_TOKEN = 'CgsKBHh0ZGISAwoBAQ==');
SELECT ...; -- will see the results of the transaction on connection A
COMMIT;
-- or, through `SET`
SET AWAIT_TOKEN = 'CgsKBHh0ZGISAwoBAQ==';
```
This await-token represents a lower-bound of the transactions that must be available on the queried node before the queries are evaluated.
## Repeatable queries - ‘basis’
[Section titled “Repeatable queries - ‘basis’”](#repeatable-queries---basis)
Every query statement in XTDB is evaluated at a ‘basis’ - both a ‘snapshot’ of the database, which determines the transactions visible to the query, and a ‘clock time’.
A read-only transaction (which may only contain query statements), is cheap to create and can be used to easily execute multiple query statements against a consistent basis.
A read-only transaction is not executed as a stateful transaction in the traditional sense. Instead, it simply defines a long-lived, stable basis context that provides a consistent view of the database at a specific snapshot in time.
Crucially, use of read-only transactions does not require locking or risk degrading performance of concurrent reads and writes.
For more details, see the [‘basis’ reference documentation](/reference/main/sql/queries#basis).
### Snapshots
[Section titled “Snapshots”](#snapshots)
No matter what else is going on in the database at the time, your query will only see a consistent state of the database as of that precise snapshot. This snapshot is fixed at the start of your transaction - all queries within a given transaction use the same snapshot.
It defaults to including all of the processed transactions on the queried node at the start of the transaction - but (advanced) you can also explicitly specify a ‘snapshot token’, either as part of your `BEGIN` statement, or at the start of a specific query.
```sql
-- retrieve a snapshot token from an earlier transaction
BEGIN;
SELECT ...;
-- ...
SHOW SNAPSHOT_TOKEN;
-- "ChYKBHh0ZGISDgoMCKHqs8cGEPCP2poB"
COMMIT;
-- then, use that token in a later transaction to use the same snapshot:
BEGIN READ ONLY
WITH (SNAPSHOT_TOKEN = 'ChYKBHh0ZGISDgoMCKHqs8cGEPCP2poB');
-- run the same query again - it will return the same results as before:
SELECT ...;
-- alternatively, on a per-query basis:
SETTING SNAPSHOT_TOKEN = 'ChYKBHh0ZGISDgoMCKHqs8cGEPCP2poB'
SELECT ...;
```
Snapshots are an *upper-bound* on the transactions visible to your query.
You may also provide `SNAPSHOT_TIME`, a timestamp which further limits the transactions visible to your query. If both are provided, transactions will not be visible if they are after either the `SNAPSHOT_TOKEN` or the `SNAPSHOT_TIME`.
```sql
-- to bound all of the queries within a transaction:
BEGIN READ ONLY
WITH (SNAPSHOT_TIME = TIMESTAMP '2023-01-01Z');
SELECT ...;
ROLLBACK; -- or COMMIT, doesn't matter for read-only transactions in XTDB.
-- alternatively, on a per-query basis:
SETTING SNAPSHOT_TIME = TIMESTAMP '2023-01-01Z'
SELECT ...;
```
Caution
`SNAPSHOT_TIME` **does not** provide repeatable queries to the same level as `SNAPSHOT_TOKEN` - it is provided only as an approximation for convenience.
For example, if the queried node is behind the `SNAPSHOT_TIME` when you first run a query (i.e. its latest indexed transaction in any database is before that time) and then catches up later, subsequent queries - even with the same `SNAPSHOT_TIME` - may return different results. Especially in multiple-database systems, the system may never have been in the state suggested by the returned results.
If you need full query repeatability (for audit purposes, say) you should store and re-use the `SNAPSHOT_TOKEN` of your query, as described above - these are guaranteed to reflect the state of the system at the point in time when the token was retrieved.
### Clock time
[Section titled “Clock time”](#clock-time)
XTDB also supports setting the clock time, both at transaction and query level. Similarly to the snapshot token, this is fixed at the start of your transaction, but may be overridden on a per-query basis.
```sql
-- at the start of a transaction:
BEGIN READ ONLY
WITH (CLOCK_TIME = TIMESTAMP '2023-01-01Z');
-- on a per-query basis:
SETTING CLOCK_TIME = TIMESTAMP '2023-01-01Z'
SELECT ...;
```
`CLOCK_TIME` has a couple of effects:
* Any call to `CURRENT_TIMESTAMP` et al will return the set time.
* Any tables in `FROM` clauses that don’t otherwise have a valid-time specification will be resolved with respect to that time.
So, for full query repeatability, you should set both `SNAPSHOT_TOKEN` and `CLOCK_TIME`.
## Footnotes
[Section titled “Footnotes”](#footnote-label)
1. [↩](#user-content-fnref-1)
# Key concepts
## Relational Querying
[Section titled “Relational Querying”](#relational-querying)
SQL was first introduced in 1974 and unlike all other languages of its era it has remained completely dominant as the language for databases. SQL is also therefore by far the most well-known façade around the relational model. However unlike SQL---which rather understandably reflects its true age and evolutionary process through its many design flaws---the core of the relational model itself is a timeless manifestation of first-order predicate logic that predates SQL by 5 years (1969!). SQL’s undeniable success is because of the strength of the underlying model rather than (and perhaps in spite of) the façade.
SQL databases and other non-SQL (but ‘relational’) languages have routinely interpreted the relational model with unique twists and XTDB is no different in having a few opinions of its own (see below). XTDB 2.x is firmly grounded in the relational model and this is not only desirable but necessary for supporting SQL as a first-class language (complete with three-valued-logic and bag/multi-set semantics).
SQL is not the only game in town however. Datalog is the alternative query language that has long been supported by XTDB for constructing relational queries. Datalog is derived from the Prolog family of logic programming, and in contrast to SQL, emphasises composition using ‘rules’ and ‘unification’ (implicit JOINs). More crucially Datalog is amenable to being expressed as well-structured data and can therefore be trivially generated without resorting to any string interpolation headaches associated with building large SQL statements.
Instead of ‘Datalog’ XTDB v2 implements ‘XTQL’ - a novel relational querying language designed for composability whilst embracing the requirement for full interoperability with SQL. XTQL also incorporates key concepts from Datalog, and in particular retains the ability to ‘unify’ across relations using logic variables.
## Schema-less & Dynamic Tables
[Section titled “Schema-less & Dynamic Tables”](#schema-less--dynamic-tables)
Traditionally a SQL database requires an explicit schema to be designed and loaded ahead of time before any data can be inserted. Such a schema defines a static set of named tables, and for each table the columns must be ordered, named, and typed. The ordering of columns in a row-oriented database like Postgres carries significance, and schema migrations must account for this.
In contrast, XTDB is ‘schemaless’ and therefore does not require the developer to provide any upfront schema definitions before data can be inserted.
New tables can be asserted ‘on the fly’, and rows of data inserted into those tables are recorded alongside dynamic, self-describing type information based on a well-defined range of native types. XTDB does not possess any notion of column ordering for stored rows.
Included in the range of first-class types are composite types: sets, structs, maps, vectors. Composite types allow you to insert arbitrarily nested structures composed of types determined at runtime.
The striking implication of this design is that rich and deeply nested structures (e.g. JSON objects) can be effortlessly represented without normalization. This is reminiscent of the flexibility afforded by ‘document’ databases but doesn’t sacrifice SQL or relational algebra. It is also reminiscent of Postgres’ JSONB columns, however this approach maintains complete alignment with the relational query engine without introducing any additional internal or developer-facing complexity.
XTDB is not the first database to offer this level of support for dynamic data, but it is the first to do so with well-defined columnar data types via Apache Arrow. The flexibility of this approach is ideal for underpinning highly-normalized, graph-like data models.
Dynamic data is commonly found in the context of ‘data lakes’ where poorly-structured, messy data is expected. As a consequence, XTDB bears resemblance to systems like Databricks’ Delta Lake - also a columnar data architecture that “separates storage and compute” using commodity object storage. XTDB is a ‘Hybrid Transactional/Analytic Processing’ (HTAP) system which postulates that even organizations who don’t have Big Data problems (yet) can benefit from similar baseline capabilities, without having to introduce additional technologies alongside their transactional database system.
## Records & Rows
[Section titled “Records & Rows”](#records--rows)
XTDB is designed for making non-destructive updates to your data simple and achieves this by modeling row-level temporal versions of data. This works by representing each update as a new row that sits alongside the previous versions of that row in the same table.
However given that XTDB does not account for schema ahead of time, the only means of correlating updates to a row is to impose a single ubiquitous schema requirement: each row asserted must contain an explicit `_id` column.
The value provided for the `id` column can be any of the supported ID types, but must be determined by the user. XTDB does not offer a means of generating new IDs automatically although use of surrogate keys (e.g. UUIDs) is encouraged.
The ID allows a set of rows to be interpreted as the evolution of a single ‘record’, such that each row corresponds with a particular version of a record. The `id` column together with the built-in temporal columns forms the default primary key for each table in XTDB.
## Temporal Columns & Bitemporality
[Section titled “Temporal Columns & Bitemporality”](#temporal-columns--bitemporality)
In addition to any user-defined columns asserted for a given row, XTDB maintains 4 built-in timestamp columns for each table.
These columns are:
* `_system_from`
* `_system_to`
* `_valid_from`
* `_valid_to`
The columns are not visible unless explicitly queried. The values of these columns are maintained automatically and the respective pairs of columns always form ‘closed-open’ periods (i.e. inclusive of ‘from’, exclusive of ‘to’).
‘System time’ represents the audit history of all changes to records and captures the time that information entered the system. ‘Valid time’ is a user-managed dimension and can be used for a variety of purposes (out of order updates, backfilling data, domain modeling etc.).
`system_time_start` can be specified to allow for importing bitemporal records from legacy systems `valid_time_from` and `valid_time_to` can be specified to meet the requirements of the application design.
The combination of these columns is called ‘bitemporality’ and can be visualized in 2 dimensions. For example:
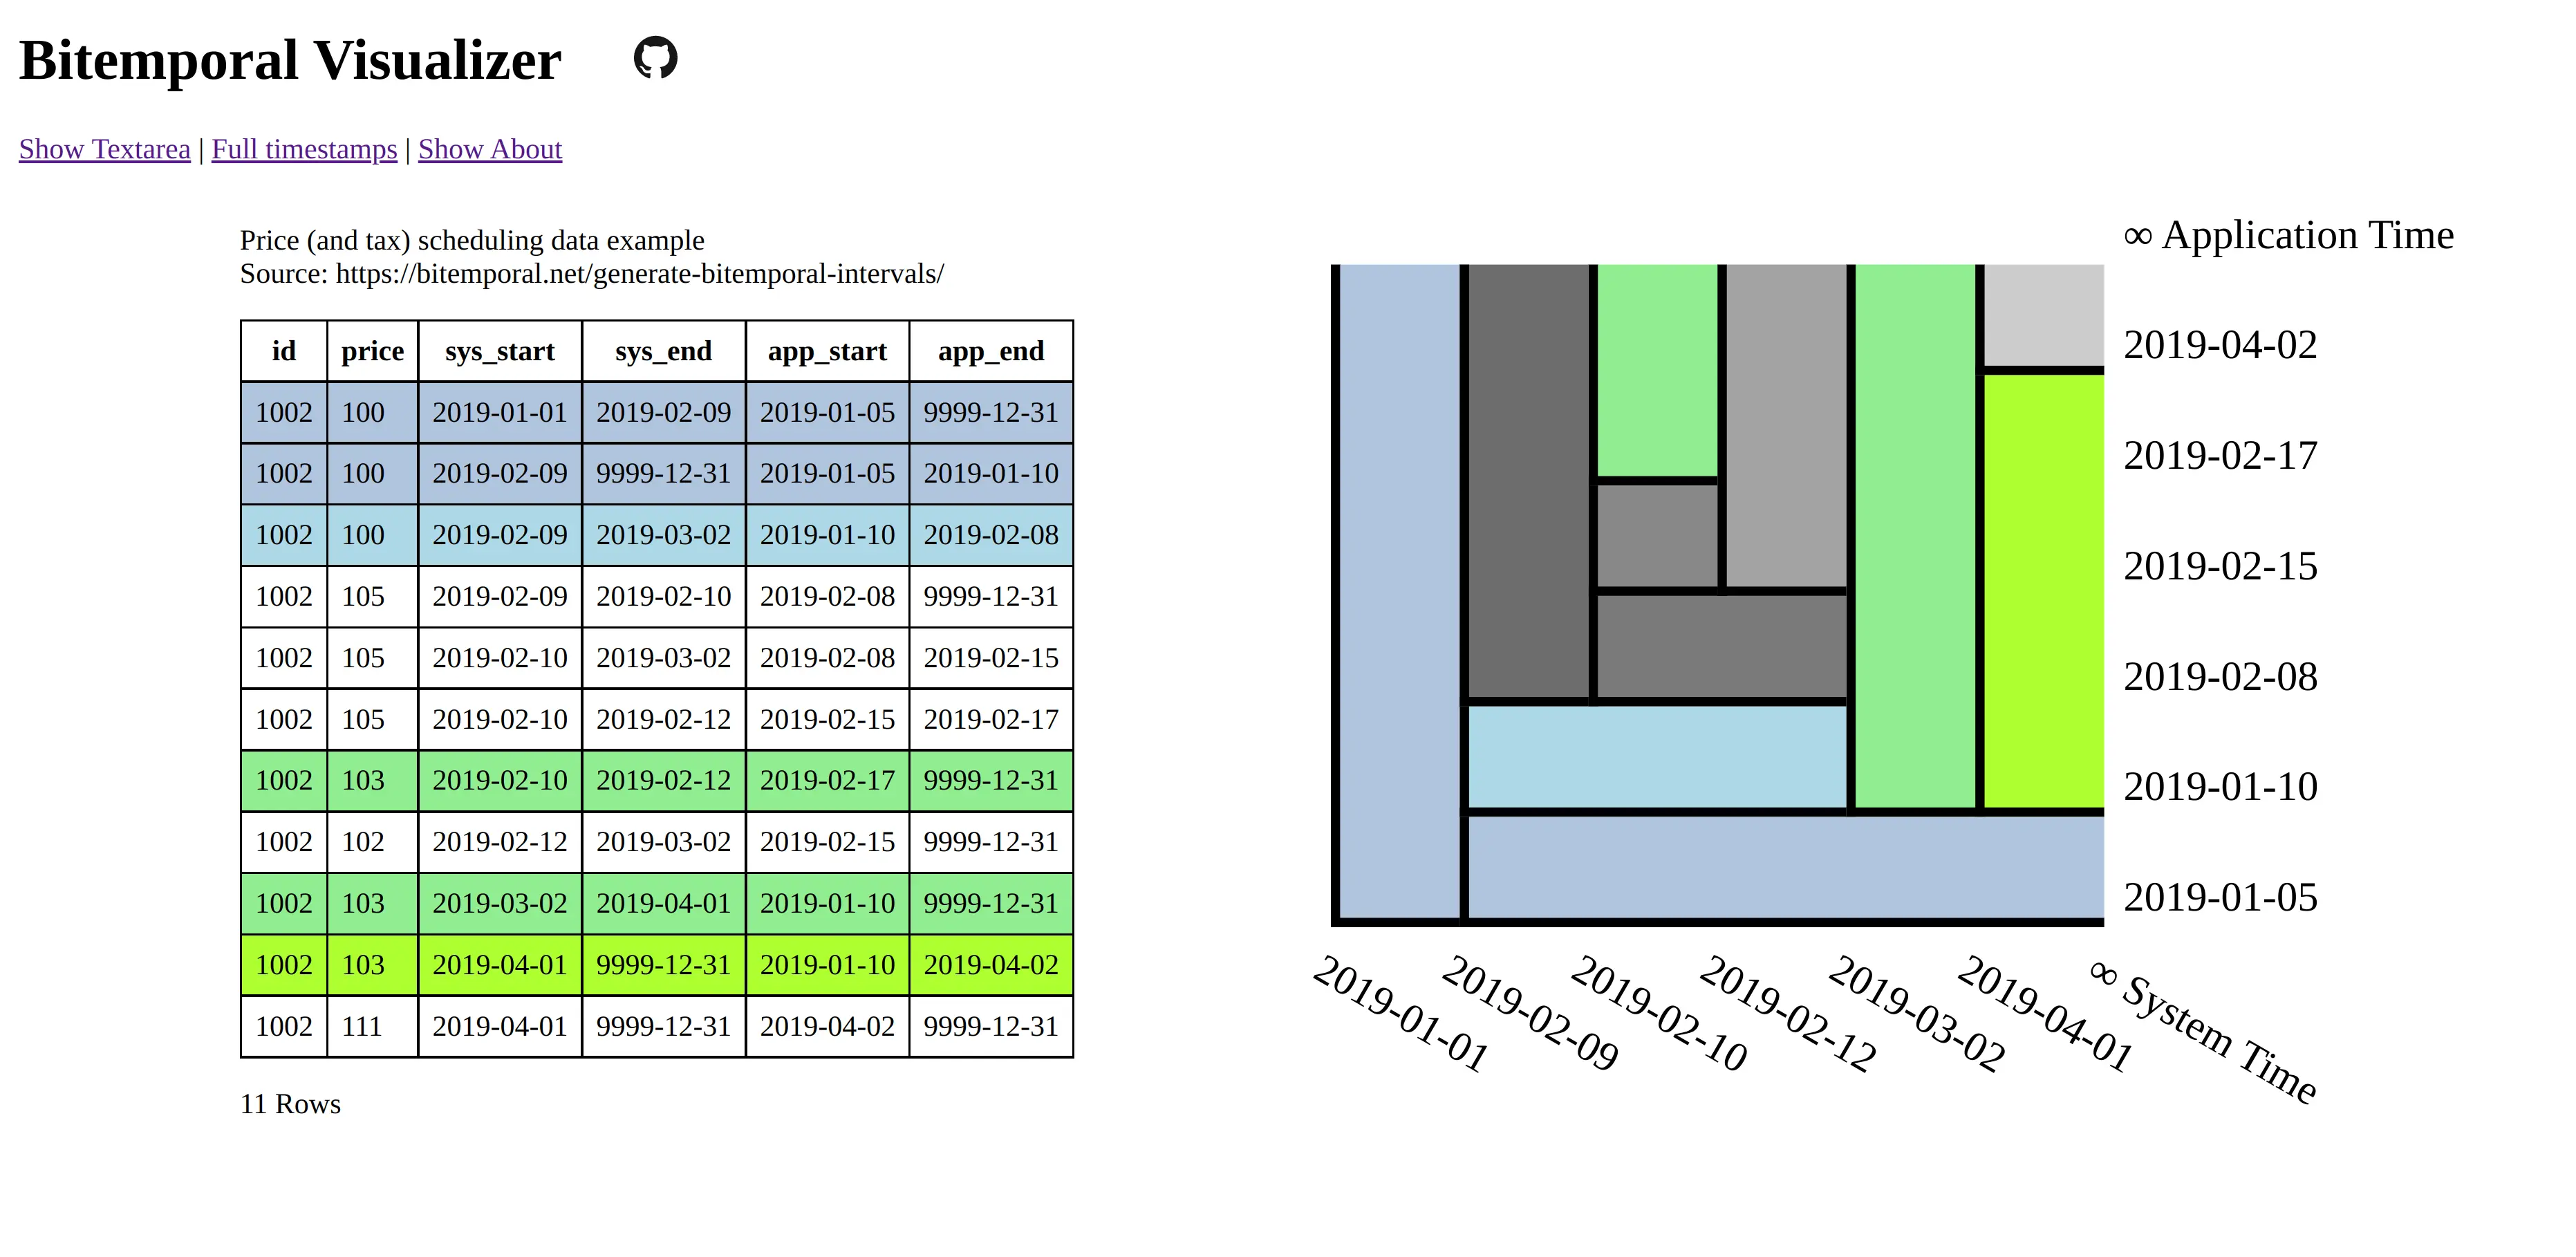
This definition of the bitemporal model was first defined by Richard Snodgrass and Christian Jensen as the “Bitemporal Conceptual Data Model” in 1994 and was (much) later adopted as the basis of the ISO SQL:2011 standard.
The bitemporal features defined in the SQL:2011 standard lack significant adoption and introduced many complexities for users. XTDB simplifies those features by making bitemporality ubiquitous and easy. For instance, XTDB maintains a built-in ‘WITHOUT OVERLAPS’ constraint which ensures that the ‘rectangles’ in this model never overlap, and also maintains a temporal index to accelerate various kinds of temporal queries (including the default ‘as of now’ query context).
Alongside a specialized temporal index, XTDB offers a set of temporal operators based on Allen interval algebra for understanding the intersections of bitemporal data (e.g. `OVERLAPS`, `CONTAINS`, `PRECEDES`).
The ability to model, reference and audit time-versioned records is useful across many domains. Application developers who are familiar with concepts like ‘soft deletes’, ‘event sourcing’, and ‘windowed joins’ will find a lot of relevant ideas and capabilities in the bitemporal design of XTDB.
Bitemporal modeling is commonly used across areas like data warehousing, stream analytics, finance and insurance. However most implementations are ad-hoc and challenging to scale.
## Transaction Processing
[Section titled “Transaction Processing”](#transaction-processing)
XTDB uses a single-writer architecture that ensures ACID consistency of updates regardless of the number of replica nodes used to scale read-only queries. The single-writer provides strong consistency guarantees needed for auditing and bitemporal timestamp generation. XTDB does not offer a sharded multi-writer architecture, meaning write latencies and availability are geographically sensitive.
Transaction logic is processed fully serially, deterministically, and atomically on the current leader node for a given database; other nodes in the cluster apply the already-resolved results. This means each transaction has exclusive access to the latest database state. Beyond basic record-oriented operations (i.e. via INSERT & DELETE `RECORDS`), many complex transactions can be expressed declaratively via SQL transactions. SQL transactions are non-interactive and mid-transaction writes are not queryable.
## Foreign keys? Uniqueness constraints? Views? Indexes? etc.
[Section titled “Foreign keys? Uniqueness constraints? Views? Indexes? etc.”](#foreign-keys-uniqueness-constraints-views-indexes-etc)
XTDB currently has no native concept of Foreign Keys and therefore referential integrity must be implemented manually if it is desired, i.e. making sure the thing being referenced already exists in the database before you insert a reference to it, and conversely deleting all references to a thing when that thing is deleted. Referential integrity can still be achieved atomically, with ACID guarantees, either using ‘transaction functions’ or SQL.
XTDB has no concept of uniqueness beyond the ID. If you want something to be unique then you can and probably should model it with an ID.
Similarly, any other features of a SQL database that intuitively require a full schema are not available within XTDB currently. XTDB is currently introducing “gradual schema” capabilities to enable new usage patterns that includes using XTDB like a traditional SQL database (e.g. “just treat XTDB as if it were Postgres, and model your data the same way”).
# What is XTDB?
XTDB is a **bitemporal** and **dynamic** **relational** database for regulated data.
At the core of XTDB is a novel relational database engine designed to help developers who are building dynamic and temporal applications with immutable data.
XTDB offers a universal ‘bitemporal’ abstraction for easily working with temporal, versioned records whilst maintaining strong audit capabilities. Bitemporal requirements are common in domains that handle regulated data. A unique combination of both temporal SQL and XTQL APIs enables you to ship simpler application code and provide a trusted, long-term foundation for your organization’s data. The underlying columnar storage and compute architecture is modern, reliable and readily benefits from cloud environments with on-demand elasticity. XTDB is easy to get started with via existing PostgreSQL client drivers.
## Mission
[Section titled “Mission”](#mission)
Databases are built for much more than just “storing data”, they are about simplifying your life as a developer. After all, the best code is the code you never have to write!
XTDB is built to eliminate the incidental complexities that are normally associated with handling time in a SQL database. XTDB makes time simple.
The existing ‘SQL:2011’ standard already defined various bitemporal language features motivated by industry demand, but mainstream database vendors have broadly failed to prioritise making these features widely usable for general application development. XTDB has been specifically built to implement these SQL:2011 capabilities in a first-class way that improves on the design such that the default developer experience is very easy to get started with. You only need to reach for temporal features when the situations arise - otherwise working with XTDB is in many ways just like working with a more traditional database …except you can be sure that no data is being destructively modified without the appropriate versions being created in the background.
## Philosophy
[Section titled “Philosophy”](#philosophy)
* Immutability - losing information is bad for business and destructive database operations are a bad default in 2023. By contrast, XTDB keeps accurate, auditable records at all times and implements strong consistency via ACID transactions by default
* Temporality - flexible record versioning and querying through history are common business expectations for IT applications, and across many industries auditable versioning is a regulatory required. XTDB makes temporal requirements easy
* Schemaless-ness - normalized schemas are wonderful but it is increasingly necessary to handle records with arbitrarily nested data and irregular shapes. XTDB allows these records to be dynamically interpreted, joined and analyzed. Schema can be gradually defined and integrated with your application as requirements evolve
* Openness - data is valuable and usually outlives code, therefore businesses should be mindful of being locked in to non-open data systems. XTDB builds upon open source technologies, and is itself open source software (MPL License), but more importantly the entire processing and storage architecture is built around Apache Arrow - a high-performance polyglot data format for cutting edge systems
## Design
[Section titled “Design”](#design)
XTDB builds upon column-oriented object storage and single-writer architectural principles to deliver a flexible store for immutable data. Tables are stored as ‘vertically partitioned’ column files of binary relations that form immutable ‘blocks’. The query engine is able to identify, retrieve and process only the blocks it strictly needs on-demand.
XTDB retains all the power of a traditional row-oriented SQL database like Postgres whilst offering superior flexibility, scale, and performance. Column-orientation allows for advanced on-disk compression (cost-effective storage at scale), vectorized processing (better use of CPU cache design), and most importantly enables the storage of sparse tables which significantly improves the flexibility of relational modeling with very wide tables.
XTDB’s approach to temporality is inspired by SQL:2011, but makes it ubiquitous, practical and transparent during day-to-day development. All tables include 4 temporal columns by default which are maintained automatically. However queries are assumed to query ‘now’ unless otherwise specified. Non-valid historical data is filtered out during low-level processing using a dedicated temporal index at the heart of the design.
## Feature Highlights
[Section titled “Feature Highlights”](#feature-highlights)
* Supports the full spectrum between normalized relational modeling and dynamic document-like storage without compromising data type fidelity (i.e. unlike JSONB).
* A native SQL dialect combined with ‘XTQL’ (XTDB’s composable query language designed for developers) offers a more productive application development experience alongside rich data analysis (without ETL to another system).
* Strong data consistency built around linearized, single-writer transaction processing.
* Accurate and immutable temporal record versioning to mitigate the complexities of application logic and handle out-of-order data ingestion.
* Apache Arrow unlocks data for external integration.
* Advanced temporal querying allows you to analyze the evolution of your data.
* Deploy across your choice of cloud database services or on-premise to meet reliability and redundancy requirements.
# What is XTDB?
XTDB is a ‘bitemporal’ and ‘dynamic’ relational database for handling regulated data. XTDB is a transactional system designed for powering applications while also being amenable to analytical querying thanks to its internal columnar architecture built on [Apache Arrow](https://arrow.apache.org/). XTDB is open source and runs on the JVM.
## Bitemporal versioning made easy
[Section titled “Bitemporal versioning made easy”](#bitemporal-versioning-made-easy)
XTDB tracks both the **system time** when data is inserted (or `UPDATE`-d) into the database, and also the **valid time** periods that define exactly when a given row/record/document is considered **valid**/**effective** in your application. This combination of **system** and **valid** time dimensions is called “bitemporality” and in XTDB all data is bitemporal without having to think about storing or updating additional columns. All data is time-versioned automatically.
This system-maintained time-versioning allows application queries to easily access the correct state of the entire application history “as-at” any given moment, *and* to trivially audit all changes to the database. In other words, this unlocks the complete history of data for rich analysis and allows applications to cope with [out of order](https://tidyfirst.substack.com/p/eventual-business-consistency) arrival of information, including **corrections** to past data while maintaining a general sense of **immutability**.
XTDB’s approach to temporality is inspired by [SQL:2011](https://en.wikipedia.org/wiki/SQL:2011), but makes it ubiquitous, practical and transparent during day-to-day development. All tables include 4 temporal columns by default which are maintained automatically. However queries are assumed to query ‘now’ unless otherwise specified. Non-valid historical data is filtered out during low-level processing at the heart of the internal design.
## Transactional columnar architecture
[Section titled “Transactional columnar architecture”](#transactional-columnar-architecture)
Unlike most transactional database systems, XTDB implements a columnar data architecture that “separates storage and compute” - this modern, Big-Data-inspired architecture is built around [Apache Arrow](https://arrow.apache.org/) and commodity object storage (e.g. S3). Most importantly, this design reduces operational costs when retaining large volumes of historical data.
Transaction processing is strictly serial and strongly consistent (ACID), based on deterministic ordering of non-interactive transactions. Within a cluster, transactions for each database are processed by a single leader node for that database, which produces an indexed output that the other nodes follow — so writes for a given database happen once, on a single thread, and reads scale out across the cluster. This design implies a hard upper limit on transaction throughput, but the key advantage is the concrete [information guarantees](https://www.youtube.com/watch?v=Cym4TZwTCNU) about *exactly when, how & why* data across the database has changed.
## Dynamic relational engine
[Section titled “Dynamic relational engine”](#dynamic-relational-engine)
The columnar engine within XTDB is able to handle “documents” as wide rows in sparse tables, where any given value in a column may contain arbitrarily nested data without any need for upfront schema design. The full range of built-in types is supported within these nested structures (i.e. unlike JSONB). This enables developers to easily use XTDB either as a store of loosely structured documents, or as a more traditional normalized database, or both at the same time.
Unlike typical SQL tables with row-oriented storage, XTDB’s columnar tables are always ‘sparse’ (storing NULLs is cheap) and ‘wide’ (storing lots of columns is efficient).
## Both SQL **and** ‘XTQL’
[Section titled “Both SQL and ‘XTQL’”](#both-sql-and-xtql)
XTDB offers two interoperable query languages - one for reach (SQL) and one for developer productivity ([XTQL](/xtql/tutorials/introducing-xtql)). SQL in XTDB is a first-class citizen, built to reflect the [SQL:2011](https://en.wikipedia.org/wiki/SQL:2011) standard (which first introduced bitemporal capabilities to the SQL standard) and conforms to a broad suite of [SQLite Logic Tests](https://www.sqlite.org/sqllogictest/doc/trunk/about.wiki).
[XTQL](/xtql/tutorials/introducing-xtql) is a novel relational database language that extends the power of SQL and its standard library to a more composable format that can be written or generated by client libraries using a JSON API.
The two languages are able to interoperate with 100% parity, meaning application developers can use the APIs as they see fit without sacrificing analytical requirements or compromising on functionality.
## Feature Highlights
[Section titled “Feature Highlights”](#feature-highlights)
* Supports the full spectrum between normalized relational modeling and dynamic document-like storage without compromising data type fidelity (i.e. unlike JSONB).
* The combination of a native SQL implementation alongside XTQL offers a more productive application development experience without sacrificing rich data analysis (and without ETL to another system).
* Strong data consistency built around linearized, single-writer transaction processing.
* Accurate and immutable temporal record versioning to mitigate the complexities of application logic and handle out-of-order data ingestion.
* Apache Arrow unlocks data for external integration.
* Advanced temporal querying allows you to analyze the evolution of your data.
* Deploy across your choice of cloud database services or on-premise to meet reliability and redundancy requirements.
Through each of these interconnected principles and features XTDB solves the [motivating problems](/about/mission) in a single, coherent system.
# XTDB reference guide
In the query-language reference guide, you can find:
* Specifications for SQL [transactions](/reference/main/sql/txs), [queries](/reference/main/sql/queries) and [schema](/reference/main/sql/schema).
* Details of the XTDB [standard library](/reference/main/stdlib) of functions.
# ADBC: Arrow-native client access
> Connect to XTDB via Arrow Database Connectivity, in-process or over FlightSQL.
XTDB exposes [ADBC](https://arrow.apache.org/adbc/), the Arrow Database Connectivity standard. If your pipeline is Arrow-shaped throughout (pandas, polars, DuckDB, DataFusion, `arrow-rs`, pyarrow), ADBC fits straight in: query results land in your client as Arrow batches with no row-by-row decode, and bulk-ingesting an Arrow table happens in a single round trip.
XTDB’s storage layer, query engine, and wire format are all Arrow-native, and ADBC carries that through to the client.
## Where to next
[Section titled “Where to next”](#where-to-next)
* **[Tutorial](/adbc/tutorial)**: an end-to-end walkthrough covering install, connect, ingest, query, transactions, and prepared statements.
* **[Reference](/adbc/reference)**: the supported ADBC surface in detail. Which calls work, which don’t, and the per-client caveats (Python vs Rust vs Java).
* **[How-to guides](/adbc/guides)**: task-shaped recipes. “Bulk-load Parquet via ADBC”, “round-trip a pandas DataFrame”, “stream results into DuckDB”.
* **[Examples](https://github.com/xtdb/xtdb/tree/main/docs/src/content/docs/adbc/examples)**: minimal runnable hello-world programs in each supported language.
## ADBC vs pgwire
[Section titled “ADBC vs pgwire”](#adbc-vs-pgwire)
XTDB also exposes a [PostgreSQL wire-compatible server](/drivers). Use whichever fits your stack:
| | pgwire | ADBC (FlightSQL) |
| ------------- | -------------------------------------- | ------------------------------------------------- |
| Tooling | psql, JDBC, psycopg, every PG client | ADBC clients (Python, Rust, Go, C, R, Java) |
| Wire format | Postgres text/binary | Arrow |
| Bulk ingest | row-at-a-time `INSERT` / `executemany` | `cur.adbc_ingest(arrow_table)`, one round trip |
| Result format | rows decoded one at a time | Arrow batches streaming straight into your client |
| Type fidelity | Postgres-mapped | Arrow-native (preserves Arrow types) |
Both backends talk to the same XTDB node, so you can pick per workload and mix freely.
# ADBC how-to guides
> Task-shaped recipes for working with XTDB via ADBC.
Each guide solves one specific task. For a continuous walkthrough see the [tutorial](./tutorial); for the full supported surface see the [reference](./reference).
## Guides
[Section titled “Guides”](#guides)
### [Bulk-loading Parquet into XTDB via ADBC](./guides/bulk-ingest-from-parquet)
[Section titled “Bulk-loading Parquet into XTDB via ADBC”](#bulk-loading-parquet-into-xtdb-via-adbc)
`pyarrow.parquet.read_table` → `cur.adbc_ingest`. Schema requirements (the `_id` column), chunked ingest for tables larger than memory, error handling, and rejection modes.
### [Round-tripping pandas / polars DataFrames](./guides/pandas-polars-round-trip)
[Section titled “Round-tripping pandas / polars DataFrames”](#round-tripping-pandas--polars-dataframes)
Two directions:
* Read XTDB into a `pyarrow.Table` and hand off to pandas / polars via `to_pandas()` / `pl.from_arrow()`, zero-copy where possible.
* Build a DataFrame in pandas / polars, convert to Arrow, `adbc_ingest` it.
Covers type-fidelity preservation (categoricals, optional fields, timestamps with timezone).
### [Point-in-time feature extraction for ML training sets](./guides/point-in-time-feature-extraction)
[Section titled “Point-in-time feature extraction for ML training sets”](#point-in-time-feature-extraction-for-ml-training-sets)
Extract training-set features as known at label time: a single SQL query against `FOR VALID_TIME AS OF` produces a `pyarrow.Table` joined as-of label time, ready for a feature pipeline. It avoids training on information that wasn’t yet available at the label time, the mistake feature stores are built to prevent.
### [Streaming results into DuckDB](./guides/streaming-into-duckdb)
[Section titled “Streaming results into DuckDB”](#streaming-results-into-duckdb)
`cur.fetch_arrow_table()` → DuckDB `register_arrow` → join with DuckDB-resident data. When some of your data already lives in DuckDB, Arrow lets you join it against XTDB’s bitemporal data with no serialise/deserialise step between them.
### [Rust ADBC + arrow-rs pipeline](./guides/rust-arrow-pipeline)
[Section titled “Rust ADBC + arrow-rs pipeline”](#rust-adbc--arrow-rs-pipeline)
End-to-end in Rust with `adbc_core` + `arrow-rs`: connect, ingest a `RecordBatch`, query, hand off to DataFusion for analytical compute, write the result out to Parquet. The Arrow types are checked at compile time through the whole pipeline.
### [Prepared statements and transactions](./guides/prepared-statements-and-transactions)
[Section titled “Prepared statements and transactions”](#prepared-statements-and-transactions)
The full prepared-statement lifecycle over the wire: `prepare()` once, `bind()` + `executeQuery()` many times, parameter binding via Arrow batches. Multi-statement transactions, autocommit on/off, rollback semantics, and how XTDB’s same-connection write-then-read works in practice.
# Bulk-load Parquet into XTDB via ADBC
> pyarrow.parquet.read_table → cur.adbc_ingest → done. Covers schema requirements, streaming large files, and error handling.
Loading a Parquet file into XTDB is one `adbc_ingest` call. This guide shows that minimal path and the variations that come up in practice: adding an `_id` when your Parquet doesn’t have one, streaming large files in chunks, and handling the modes that XTDB rejects.
## Prerequisites
[Section titled “Prerequisites”](#prerequisites)
XTDB running with the FlightSQL listener on port `9832`, which the Docker standalone image does by default:
```bash
docker run --rm -p 5432:5432 -p 9832:9832 ghcr.io/xtdb/xtdb:nightly
```
Install the Python dependencies:
```bash
pip install adbc-driver-flightsql pyarrow
```
## The minimal path
[Section titled “The minimal path”](#the-minimal-path)
```python
import pyarrow.parquet as pq
import adbc_driver_flightsql.dbapi as flight_sql
table = pq.read_table("orders.parquet")
with flight_sql.connect("grpc://localhost:9832") as conn:
with conn.cursor() as cur:
cur.adbc_ingest("orders", table, mode="create_append")
```
`adbc_ingest` streams Arrow batches from the client into XTDB in a single round trip: no row shredding, no `executemany("INSERT INTO ...")`.
The one requirement: every row needs an `_id` column, XTDB’s primary key.
## Adding `_id` when your Parquet doesn’t have one
[Section titled “Adding \_id when your Parquet doesn’t have one”](#adding-_id-when-your-parquet-doesnt-have-one)
If your Parquet schema doesn’t include an `_id` column, materialise one client-side before calling `adbc_ingest`.
**Option 1: promote an existing natural key.** If a column already uniquely identifies each row (e.g. `order_id`), rename it:
```python
import pyarrow as pa
import pyarrow.parquet as pq
table = pq.read_table("orders.parquet")
# Rename order_id to _id, keep the original column too if you want.
table = table.rename_columns(
["_id" if c == "order_id" else c for c in table.schema.names]
)
```
**Option 2: build a composite key.** If uniqueness comes from a combination of columns, hash them together:
```python
import pyarrow as pa
import pyarrow.compute as pc
# Concatenate two string columns to form a stable key.
composite = pc.binary_join_element_wise(
table.column("customer_id").cast(pa.string()),
table.column("order_date").cast(pa.string()),
"-",
)
table = table.append_column("_id", composite)
```
**Option 3: generate a random UUID per row.** When the rows have no natural key, a random UUID is the best default: it’s unique by construction and works for both one-time loads and ongoing production ingest (unlike a positional index, which shifts if you re-ingest and silently overwrites).
```python
import uuid
import pyarrow as pa
ids = pa.array([str(uuid.uuid4()) for _ in range(len(table))], type=pa.string())
table = table.append_column("_id", ids)
```
XTDB upserts on `_id`: two rows with the same `_id` in the same ingest call will produce one document in XTDB, with the later row’s values winning. If that’s not what you want, make sure your `_id` values are unique before ingesting.
## Streaming large files in chunks
[Section titled “Streaming large files in chunks”](#streaming-large-files-in-chunks)
`pq.read_table` loads the whole Parquet file into memory at once. For files larger than available RAM, use `pq.ParquetFile` to iterate over row groups:
```python
import pyarrow.parquet as pq
import adbc_driver_flightsql.dbapi as flight_sql
with flight_sql.connect("grpc://localhost:9832") as conn:
with conn.cursor() as cur:
pf = pq.ParquetFile("large-orders.parquet")
for batch in pf.iter_batches(batch_size=100_000):
# Each batch is a pyarrow.RecordBatch.
# adbc_ingest accepts RecordBatch as well as Table.
cur.adbc_ingest("orders", batch, mode="create_append")
```
`adbc_ingest` accepts any Arrow-shaped data: `pyarrow.Table`, `pyarrow.RecordBatch`, or any object that exposes the [Arrow C Data Interface](https://arrow.apache.org/docs/format/CDataInterface.html). Batches stream through without materialising the whole dataset in either the client or the server.
## Ingest modes
[Section titled “Ingest modes”](#ingest-modes)
`create`, `append`, and `create_append` are all accepted and behave the same here, since XTDB auto-creates tables and upserts on `_id`. `replace` and the fail-if-exists / fail-if-not-exist variants are rejected with a gRPC `INVALID_ARGUMENT`. See [Bulk ingest](/adbc/reference#bulk-ingest) in the reference for the full mode table and the reasoning.
## Error handling
[Section titled “Error handling”](#error-handling)
Catch `adbc_driver_flightsql.DatabaseError` (a `ProgrammingError` in the ADBC DBAPI sense) and read the gRPC status message from it directly. Rejected modes return a descriptive `INVALID_ARGUMENT`; some other failures (a missing `_id`) are not yet mapped and surface as `INTERNAL`, with the cause still in the message.
```python
import pyarrow as pa
import adbc_driver_flightsql.dbapi as flight_sql
from adbc_driver_manager import DatabaseError
with flight_sql.connect("grpc://localhost:9832") as conn:
with conn.cursor() as cur:
table = pa.table({
"_id": ["alice"],
"name": ["Alice"],
})
try:
# "replace" is rejected: XTDB has no ERASE-then-reinsert step.
cur.adbc_ingest("users", table, mode="replace")
except DatabaseError as e:
print(f"Ingest failed: {e}")
# "Ingest failed: INVALID_ARGUMENT: ingest mode 'replace' is not supported …"
try:
# Missing _id column. Currently surfaces as INTERNAL, not
# INVALID_ARGUMENT (see the reference's error-mapping note).
no_id = pa.table({"name": ["Bob"]})
cur.adbc_ingest("users", no_id, mode="create_append")
except DatabaseError as e:
print(f"Ingest failed: {e}")
```
XTDB puts the full gRPC status message in `DatabaseError.args[0]`, so you can read it straight off the exception.
## Verifying the load
[Section titled “Verifying the load”](#verifying-the-load)
After ingesting, confirm the row count and schema look right:
```python
with conn.cursor() as cur:
cur.execute("SELECT count(*) AS n FROM orders")
print("Row count:", cur.fetchone()[0])
schema = conn.adbc_get_table_schema(
"orders", db_schema_filter="public",
)
print("Schema:", schema)
```
`adbc_get_table_schema` reflects live data: freshly ingested rows show up immediately, before any background flush.
## Runnable example
[Section titled “Runnable example”](#runnable-example)
A self-contained script that writes a Parquet fixture and bulk-loads it is in the repository at [`docs/adbc/examples/bulk-ingest-from-parquet/main.py`](https://github.com/xtdb/xtdb/tree/main/docs/src/content/docs/adbc/examples/bulk-ingest-from-parquet/main.py).
```bash
docker run --rm -p 5432:5432 -p 9832:9832 ghcr.io/xtdb/xtdb:nightly
pip install adbc-driver-flightsql pyarrow
python docs/src/content/docs/adbc/examples/bulk-ingest-from-parquet/main.py
```
# Round-tripping pandas / polars DataFrames via ADBC
> Zero-copy dataframe ↔ XTDB through Arrow, with full type fidelity for timestamps, nulls, and categoricals.
ADBC keeps your data in Arrow from XTDB through to a DataFrame, with no row-by-row decode and no type widening through the Postgres text wire. This guide shows both directions: reading query results straight into pandas / polars, and writing DataFrames back to XTDB.
Type fidelity is the main reason to use this path. `TIMESTAMP WITH TIME ZONE`, nullable columns, and dictionary-encoded categoricals all survive intact. The same round-trip through psycopg or JDBC widens timestamps, turns nullable Arrow arrays into `NaN`-polluted float columns, and discards the category encoding.
## Prerequisites
[Section titled “Prerequisites”](#prerequisites)
```bash
pip install adbc-driver-flightsql pyarrow pandas polars
docker run --rm -d --name xtdb -p 5432:5432 -p 9832:9832 ghcr.io/xtdb/xtdb:nightly
```
All examples below connect to `grpc://localhost:9832`. The [runnable companion script](https://github.com/xtdb/xtdb/tree/main/docs/src/content/docs/adbc/examples/pandas-polars-round-trip/main.py) exercises every code block in order.
## The dataset
[Section titled “The dataset”](#the-dataset)
A small events table that stress-tests type fidelity:
* `_id`: required; XTDB’s document key.
* `ts`: `TIMESTAMP WITH TIME ZONE`. psycopg hands this back as a tz-aware `datetime`; ADBC hands it back as `timestamp[us, tz=UTC]`, Arrow-native, no intermediate decode.
* `severity`: string, stored as a small-cardinality column. Ingested via pandas as `dictionary`; polars ingests as `dictionary`. psycopg would widen to plain strings; ADBC returns it as `utf8`, which clients can re-encode as dictionary if needed (see the [dictionary callout](#dictionary-round-trip-caveat)).
* `value`: `float64`, always present.
* `label`: `utf8`, nullable. Some rows have `null` here. Through psycopg the column often surfaces as `object` dtype with `None` sprinkled in; Arrow models it as a validity bitmap alongside the data buffer.
## XTDB → Arrow (reading)
[Section titled “XTDB → Arrow (reading)”](#xtdb--arrow-reading)
Connect and fetch a query result as an Arrow table:
```python
import pyarrow as pa
import adbc_driver_flightsql.dbapi as flight_sql
with flight_sql.connect("grpc://localhost:9832") as conn:
with conn.cursor() as cur:
cur.execute("SELECT _id, ts, severity, value, label FROM events ORDER BY ts")
arrow_table = cur.fetch_arrow_table()
# arrow_table is a pyarrow.Table; Arrow buffers, no copies yet.
print(arrow_table.schema)
# _id: string
# ts: timestamp[us, tz=UTC]
# severity: string
# value: double
# label: string (nullable=True)
```
Query results stream from XTDB as Arrow batches over gRPC. `fetch_arrow_table()` collects them into a single `pyarrow.Table`, memory-bound by the client; use the raw batch-by-batch path for very large result sets.
### Timezone normalisation
[Section titled “Timezone normalisation”](#timezone-normalisation)
XTDB FlightSQL currently returns timestamps with timezone key `"Z"` (Zulu = UTC). The `"Z"` key is valid Arrow but not a recognised IANA timezone string, so pandas will raise a `ZoneInfoNotFoundError` when printing or converting these columns. Cast to `"UTC"` before handing the table to pandas or polars:
```python
def normalise_tz(table: pa.Table) -> pa.Table:
"""Cast timestamp[us, tz=Z] → timestamp[us, tz=UTC] for client compatibility."""
for i, field in enumerate(table.schema):
t = field.type
if pa.types.is_timestamp(t) and t.tz == "Z":
table = table.set_column(
i, field.name,
table.column(field.name).cast(pa.timestamp(t.unit, tz="UTC")),
)
return table
arrow_table = normalise_tz(arrow_table)
```
## Arrow → pandas
[Section titled “Arrow → pandas”](#arrow--pandas)
### With `types_mapper=pd.ArrowDtype` (recommended)
[Section titled “With types\_mapper=pd.ArrowDtype (recommended)”](#with-types_mapperpdarrowdtype-recommended)
```python
import pandas as pd
df = arrow_table.to_pandas(types_mapper=pd.ArrowDtype)
print(df.dtypes)
# _id string[pyarrow]
# ts timestamp[us, tz=UTC][pyarrow]
# severity string[pyarrow]
# value double[pyarrow]
# label string[pyarrow]
```
`types_mapper=pd.ArrowDtype` keeps all columns Arrow-backed:
* **Zero-copy** for all column types including strings: the pandas `ArrowDtype` column wraps the Arrow buffer directly, no allocation.
* Nulls surface as `pd.NA` (not `float('nan')`): `df["label"].isna().sum()` counts them correctly.
* Timestamps carry the UTC timezone as an `ArrowDtype`: no lossy intermediate.
### Without `types_mapper` (classic path)
[Section titled “Without types\_mapper (classic path)”](#without-types_mapper-classic-path)
```python
df_classic = arrow_table.to_pandas()
print(df_classic.dtypes)
# _id object ← strings decoded into Python objects
# ts datetime64[us, UTC] ← zero-copy from the Arrow buffer
# severity object ← strings decoded, dictionary encoding gone
# value float64 ← zero-copy from the Arrow buffer
# label object ← nulls decoded as Python None
```
Numeric and timestamp columns are zero-copy in the classic path too. Strings allocate: pandas’s `object` dtype is Python objects, not Arrow buffers.
## Arrow → polars
[Section titled “Arrow → polars”](#arrow--polars)
polars is Arrow-native, so `pl.from_arrow()` wraps the Arrow buffers without copying them:
```python
import polars as pl
df = pl.from_arrow(arrow_table)
print(df.schema)
# Schema({'_id': String, 'ts': Datetime(time_unit='us', time_zone='UTC'),
# 'severity': String, 'value': Float64, 'label': String})
```
The polars path is genuinely zero-copy for all column types including strings. polars stores strings as Arrow `LargeUtf8` internally; it wraps the server-side `Utf8` buffer directly.
Nulls are modelled as Arrow nulls, not `NaN`:
```python
df["label"].null_count() # 2; not NaN, not None-in-object
```
## DataFrame → XTDB (ingesting)
[Section titled “DataFrame → XTDB (ingesting)”](#dataframe--xtdb-ingesting)
The clean bulk-ingest path (one gRPC round trip, no row shredding) uses `adbc_ingest`:
```python
import pyarrow as pa
# pandas → Arrow
arrow_from_pd = pa.Table.from_pandas(df, preserve_index=False)
# polars → Arrow (near-zero-copy)
arrow_from_pl = df_pl.to_arrow()
with flight_sql.connect("grpc://localhost:9832") as conn:
with conn.cursor() as cur:
cur.adbc_ingest("events", arrow_from_pd, mode="create_append")
cur.adbc_ingest("events", arrow_from_pl, mode="create_append")
```
`adbc_ingest` maps to the FlightSQL `CommandStatementIngest` command: the whole table travels as one Arrow stream, no per-row round trips. It’s available on the `nightly` image and on stable images from 2.2.0 onwards.
## Building an ingest-ready Arrow table from pandas
[Section titled “Building an ingest-ready Arrow table from pandas”](#building-an-ingest-ready-arrow-table-from-pandas)
Regardless of the ingest path, here is how to build a clean Arrow table from a pandas DataFrame:
```python
import pandas as pd
import pyarrow as pa
df = pd.DataFrame({
"_id": ["evt-001", "evt-002", "evt-003", "evt-004"],
"ts": pd.to_datetime(
["2024-01-15T08:30:00Z", "2024-01-15T09:45:00Z",
"2024-01-15T11:00:00Z", "2024-01-15T14:20:00Z"],
utc=True,
),
# Categorical → Arrow dictionary.
"severity": pd.Categorical(
["INFO", "WARN", "ERROR", "INFO"],
categories=["INFO", "WARN", "ERROR"],
),
"value": [1.23, 4.56, 7.89, 2.34],
# StringDtype with None → Arrow utf8 with validity bitmap (not NaN).
"label": pd.array(["startup", None, "threshold", None],
dtype=pd.StringDtype()),
})
arrow_table = pa.Table.from_pandas(df, preserve_index=False)
# Schema:
# _id: large_string
# ts: timestamp[us, tz=UTC]
# severity: dictionary
# value: double
# label: large_string
```
Key points:
* Use `pd.StringDtype()` for nullable string columns so `None` maps to an Arrow null, not a `NaN`. Plain Python `str` in an `object` column would produce `None` or `float('nan')`, which `from_pandas` handles heuristically.
* Use `pd.Categorical` for low-cardinality string columns: `from_pandas` converts it to Arrow `dictionary` preserving the encoding.
* `preserve_index=False` drops the pandas index from the schema; the resulting table is clean Arrow with no pandas metadata bleeding in.
## Building an ingest-ready Arrow table from polars
[Section titled “Building an ingest-ready Arrow table from polars”](#building-an-ingest-ready-arrow-table-from-polars)
polars `.to_arrow()` is near-zero-copy:
```python
import polars as pl
from datetime import datetime, timezone
df = pl.DataFrame({
"_id": ["evt-005", "evt-006"],
"ts": pl.Series(
[datetime(2024, 1, 16, 8, 0, tzinfo=timezone.utc),
datetime(2024, 1, 16, 10, 30, tzinfo=timezone.utc)],
dtype=pl.Datetime("us", "UTC"),
),
"severity": pl.Series(["WARN", "ERROR"], dtype=pl.Categorical),
"value": [9.99, 0.01],
"label": pl.Series([None, "manual"], dtype=pl.Utf8),
})
arrow_table = df.to_arrow()
# Schema:
# _id: large_string
# ts: timestamp[us, tz=UTC]
# severity: dictionary
# value: double
# label: large_string
```
polars `pl.Categorical` maps to `dictionary`, a wider index than pandas’s `int8`, but both are valid Arrow dictionary types.
## Type fidelity: what survives, what doesn’t
[Section titled “Type fidelity: what survives, what doesn’t”](#type-fidelity-what-survives-what-doesnt)
| Type | Via pgwire (psycopg) | Via ADBC |
| -------------------------- | ---------------------------- | --------------------------------------------------------------------------------------- |
| `TIMESTAMP WITH TIME ZONE` | Python `datetime` (tz-aware) | `timestamp[us, tz=UTC]`, Arrow native, zero-copy into polars / pandas with `ArrowDtype` |
| Nullable column | `object` dtype with `None` | Arrow validity bitmap, proper `null_count`, no NaN |
| `DOUBLE` / `FLOAT` | Python `float` | `float64` Arrow buffer, zero-copy into numpy / polars |
| `INTEGER` | Python `int` | `int32` / `int64` Arrow buffer, zero-copy |
| `VARCHAR` / `TEXT` | Python `str` | `utf8` / `large_utf8`, zero-copy into polars, copy into classic pandas |
### Dictionary round-trip caveat
[Section titled “Dictionary round-trip caveat”](#dictionary-round-trip-caveat)
XTDB’s query engine returns `utf8` for string columns regardless of how they were ingested. If you ingest a `dictionary` column and query it back, you’ll get `utf8`: the data is intact but the encoding is gone. Re-encode client-side if the downstream computation depends on it:
```python
col = arrow_table.column("severity")
if not pa.types.is_dictionary(col.type):
arrow_table = arrow_table.set_column(
arrow_table.schema.get_field_index("severity"),
"severity",
col.dictionary_encode(),
)
```
### Null handling on the pandas ingest path
[Section titled “Null handling on the pandas ingest path”](#null-handling-on-the-pandas-ingest-path)
pandas uses `NaN` for missing float values and `None` for object dtype columns. `pa.Table.from_pandas()` maps both to Arrow nulls, but only if the column uses a pandas nullable extension type. Use `pd.StringDtype()`, `pd.Int64Dtype()`, etc. so `from_pandas` can distinguish a real `None` from a missing sentinel:
```python
# Correct: nullable Int64Dtype maps None → Arrow null.
df["count"] = pd.array([1, None, 3], dtype=pd.Int64Dtype())
# Risky: plain int list with None becomes float64 with NaN.
df["count"] = [1, None, 3]
```
## The pgwire comparison
[Section titled “The pgwire comparison”](#the-pgwire-comparison)
Same round-trip via psycopg for contrast:
```python
import psycopg
with psycopg.connect("postgresql://xtdb@localhost:5432/xtdb") as pg:
# Row-at-a-time INSERT; one round trip per row.
pg.autocommit = True
with pg.cursor() as cur:
for _, row in df.iterrows():
cur.execute(
"INSERT INTO events (_id, ts, severity, value) VALUES (%s, %s, %s, %s)",
(row["_id"], row["ts"], str(row["severity"]), row["value"]),
)
# SELECT returns rows decoded one at a time.
cur.execute("SELECT _id, ts, severity, value, label FROM events ORDER BY ts")
rows = cur.fetchall()
# rows is a list of tuples; ts is a datetime, severity is a str,
# nulls are None, no Arrow anywhere, no zero-copy.
```
The ADBC path:
* Ingests the whole table in a single gRPC call via `adbc_ingest` vs one `INSERT` per row.
* Returns Arrow batches vs decoded Python tuples.
* Preserves `timestamp[us, tz=UTC]` vs widening to `datetime`.
* Keeps nulls as Arrow null rather than Python `None` in an `object` column.
For analytical and bulk workloads, the Arrow path avoids a decode-and-re-encode step on every row. For interactive queries and existing Postgres tooling, pgwire is still the right answer.
## Summary
[Section titled “Summary”](#summary)
* Use `cur.fetch_arrow_table()` to collect query results as a `pyarrow.Table`. Call `normalise_tz()` to convert `tz=Z` → `tz=UTC` before pandas/polars conversion.
* Use `.to_pandas(types_mapper=pd.ArrowDtype)` for zero-copy across all column types including strings.
* Use `pl.from_arrow(arrow_table)` for polars: genuinely zero-copy, nulls modelled correctly.
* Use `pa.Table.from_pandas(df, preserve_index=False)` to build an Arrow table for ingest. Use nullable extension types (`pd.StringDtype()`, `pd.Int64Dtype()`) to preserve nulls.
* Use `df.to_arrow()` for polars: near-zero-copy.
* Use `cur.adbc_ingest(table, arrow_table, mode="create_append")` for bulk Arrow ingest over FlightSQL: one round trip, no row shredding. Available on `nightly` and stable images from 2.2.0 onwards.
# Point-in-time feature extraction for ML training sets
> Build leakage-free training matrices with one bitemporal SQL query.
Training models on data that changes over time runs into the as-of-join problem. You label an event at time `T`, then join feature rows on the entity key. A naive join pulls each entity’s *current* feature values, including everything that happened after `T`. The model trains on information from after the label time, scores well offline, and then degrades in production.
Much of what feature stores (Feast, Tecton, Hopsworks) do is to perform this join correctly. In XTDB the join is one SQL query, because every row already carries its valid-time interval. `adbc_driver_flightsql` returns the result as Arrow, and `pyarrow.Table.to_pandas()` gives you a model-ready dataframe.
The runnable example for this guide is in [`docs/.../examples/point-in-time-feature-extraction/main.py`](https://github.com/xtdb/xtdb/tree/main/docs/src/content/docs/adbc/examples/point-in-time-feature-extraction/main.py).
## The scenario
[Section titled “The scenario”](#the-scenario)
Loan-default prediction.
**Labels.** One row per event we want to train on: `(customer_id, observed_at, did_default)`. A label is an *event*, observed at a single instant, not a state that holds over a span. So we model its valid-time as the instantaneous chronon `[observed_at, observed_at + 1µs)`: `observed_at` becomes the label’s own `_valid_from`, and the as-of join below is a clean period-vs-period one.
**Features.** Per-customer attributes that drift: `account_balance`, `credit_score`, `employment_status`. The truth about a customer on 2024-08-15 is different from the truth about that customer on 2024-11-01, and the model only ever gets to see the former.
We seed three customers with deliberately-shifting histories. `c1` starts the year solvent, drifts down through summer, and bottoms out post-default in October. `c3` defaults, then recovers in November. A naive join would feed *both* of those post-default snapshots into training rows for a default that happened in August.
## Setup
[Section titled “Setup”](#setup)
Start a node with the FlightSQL listener:
```bash
docker run --rm -d --name xtdb -p 5432:5432 -p 9832:9832 ghcr.io/xtdb/xtdb:nightly
pip install adbc-driver-flightsql pyarrow pandas
```
Connect:
```python
import adbc_driver_flightsql.dbapi as flight_sql
# autocommit=True so each seed INSERT commits and the joins below read their
# own writes. The dbapi defaults to manual-commit (PEP 249) now that the
# server advertises transaction support, so without this the uncommitted
# seed rows would be invisible to subsequent queries on the same connection.
conn = flight_sql.connect("grpc://localhost:9832", autocommit=True)
```
## Seeding features as a temporal timeline
[Section titled “Seeding features as a temporal timeline”](#seeding-features-as-a-temporal-timeline)
Every XTDB row carries a valid-time interval, exposed as `_valid_from` / `_valid_to`. Setting `_valid_from` on `INSERT` records *when each version became true*, not when the database happened to learn it.
```python
cur.execute("""
INSERT INTO customer_features
(_id, _valid_from, account_balance, credit_score, employment_status)
VALUES (?, ?, ?, ?, ?)
""", parameters=["c1", date(2024, 1, 1), 1500.00, 680, "employed"])
```
Re-inserting `_id = "c1"` with a later `_valid_from` doesn’t overwrite the prior version: it closes off the previous interval and starts a new one. After ingesting the seed, `c1`’s history is a step function over valid time:
```plaintext
c1: [2024-01-01 .. 2024-04-01) balance=1500 score=680 employed
[2024-04-01 .. 2024-07-01) balance=2100 score=700 employed
[2024-07-01 .. 2024-10-01) balance=400 score=640 employed
[2024-10-01 .. ∞ ) balance=50 score=580 unemployed
```
No audit table, no `effective_from` column, no triggers, no manual interval bookkeeping.
## The naive join: wrong
[Section titled “The naive join: wrong”](#the-naive-join-wrong)
This is what most pipelines start with:
```sql
SELECT l._id AS label_id,
l.customer_id,
l._valid_from AS observed_at,
l.did_default,
f.account_balance,
f.credit_score,
f.employment_status
FROM loan_labels AS l
JOIN customer_features AS f
ON f._id = l.customer_id
```
Without a temporal qualifier, XTDB returns each customer’s *current* row, so this query gives every label the customer’s feature values *as they are today*, regardless of when the label was observed.
For our seed:
```plaintext
label_id customer_id observed_at did_default account_balance credit_score employment_status
L1 c1 2024-08-15 True 50.0 580 unemployed
L2 c2 2024-08-15 False 10200.0 770 employed
L3 c3 2024-08-15 True 5500.0 700 employed
```
Look at `L1`. The label says c1 defaulted on 2024-08-15. The feature row says c1 has $50 in the bank and is unemployed. Those numbers describe c1 *after* the default has already destroyed their finances. The model “learns” that low balance + unemployed predicts default: true but tautological. Look at `L3`. The features for c3 show $5,500 and a 700 credit score: c3’s *recovery* a quarter after the default we’re trying to predict. Train on this and the model learns the aftermath of a default, not the signals that precede one, so it has nothing useful to go on in production.
## The bitemporal AS-OF join: right
[Section titled “The bitemporal AS-OF join: right”](#the-bitemporal-as-of-join-right)
The fix is one SQL clause: `FOR ALL VALID_TIME` on the features table, joined against the label’s valid-time period:
```sql
SELECT l._id AS label_id,
l.customer_id,
l._valid_from AS observed_at,
l.did_default,
f.account_balance,
f.credit_score,
f.employment_status
FROM loan_labels FOR ALL VALID_TIME AS l
LEFT JOIN customer_features FOR ALL VALID_TIME AS f
ON f._id = l.customer_id
AND f._valid_time CONTAINS l._valid_time
```
`FOR ALL VALID_TIME` opens up every historical version of `customer_features`. Both sides are valid-time periods, so the join is period-against-period: `f._valid_time CONTAINS l._valid_time` picks the one feature version per customer whose period contains the label’s event chronon, without spelling out the interval bounds by hand. (`observed_at` is the label’s `_valid_from`, so we project it from there.)
Same data, run again:
```plaintext
label_id customer_id observed_at did_default account_balance credit_score employment_status
L1 c1 2024-08-15 True 400.0 640 employed
L2 c2 2024-08-15 False 9500.0 760 employed
L3 c3 2024-08-15 True 10.0 540 unemployed
```
c1’s August features are now $400 / 640 / employed: the state the customer was actually in before the default. c3’s features are $10 / 540 / unemployed: the dire state preceding the default, not the post-recovery snapshot.
This is one query covering every label, with no Python loop or per-row round trip. XTDB applies the `FOR VALID_TIME AS OF` bound during the table scan, so each row is read at its as-of-label-time version directly.
### Why this is hard without bitemporal storage
[Section titled “Why this is hard without bitemporal storage”](#why-this-is-hard-without-bitemporal-storage)
The standard alternative is event sourcing: store every change to a customer as an immutable event with a timestamp, then for each label scan the event log up to `observed_at` and fold the latest state per attribute. You’ll either write that fold in application code (slow, hard to vectorise), bake it into a Spark/Flink job (complex, brittle, your own join-engine to debug), or rent a feature store (Feast/Tecton/Hopsworks) whose primary value-add is doing exactly this.
Each of those routes rebuilds part of what a bitemporal database already does. XTDB is one, with the temporal logic built in and queried through standard SQL:2011 syntax.
## Handing the result to sklearn
[Section titled “Handing the result to sklearn”](#handing-the-result-to-sklearn)
`fetch_arrow_table()` gives a `pyarrow.Table`; `to_pandas()` gives the dataframe sklearn wants:
```python
cur.execute(ASOF_SQL)
features_df = cur.fetch_arrow_table().to_pandas()
X = features_df[["account_balance", "credit_score", "employment_status"]]
y = features_df["did_default"].astype(int)
```
The Arrow path is zero-copy for numeric columns and one allocation for strings. For a one-million-label training set the conversion stays in seconds, not minutes.
If you’d rather skip pandas:
```python
import polars as pl
features_df = pl.from_arrow(cur.fetch_arrow_table())
```
polars consumes the Arrow batches directly with no intermediate copy.
## Variations
[Section titled “Variations”](#variations)
**Per-label valid-time.** Labels themselves don’t have to live in XTDB. Land them as an in-memory `pyarrow.Table` and ingest, or `INSERT` them directly; the AS-OF join works the same.
**Multi-table join.** Multiple feature tables, each with their own timeline:
```sql
SELECT l._id, l.customer_id, l._valid_from AS observed_at, l.did_default,
cf.credit_score,
acc.account_balance,
emp.status AS employment_status
FROM loan_labels FOR ALL VALID_TIME AS l
LEFT JOIN credit_scores FOR ALL VALID_TIME AS cf ON cf._id = l.customer_id AND cf._valid_time CONTAINS l._valid_time
LEFT JOIN accounts FOR ALL VALID_TIME AS acc ON acc._id = l.customer_id AND acc._valid_time CONTAINS l._valid_time
LEFT JOIN employment_history FOR ALL VALID_TIME AS emp ON emp._id = l.customer_id AND emp._valid_time CONTAINS l._valid_time
```
Each feature table is joined at its own correct point in time. You can collapse the repetition with a SQL view; the optimiser still pushes each temporal predicate into its respective scan.
**Reproducible re-runs.** Pin the whole query to a system-time basis:
```sql
SETTING DEFAULT SYSTEM_TIME AS OF TIMESTAMP '2024-12-01T00:00:00Z'
SELECT ...
```
Re-run the training-set extraction six months later, get bit-identical output even if features were corrected in the meantime. The `FOR VALID_TIME` clause picks the right version *in the timeline*; `SETTING DEFAULT SYSTEM_TIME` picks the right *timeline*. This is the bitemporal pair; see [Time in XTDB](/about/time-in-xtdb) for the underlying model.
## Caveats
[Section titled “Caveats”](#caveats)
The example script seeds each table in a single `adbc_ingest` call, including a `_valid_from` column so every row sets its own valid-time and the customers build a real timeline. `_valid_from` must be a `timestamp` column in the Arrow table, not a `date`. For bulk loads of labels or feature timelines from Parquet or pandas, see [Bulk-load Parquet into XTDB via ADBC](/adbc/guides/bulk-ingest-from-parquet).
Training-set extraction is a single read query, so transactions don’t enter into it. But if you combine ingestion and querying on the same connection, see [Transactions](/adbc/reference#transactions) in the reference.
# Prepared statements and transactions via ADBC
> The full ADBC statement lifecycle over the wire: prepare once, bind many, and multi-statement transactions.
ADBC separates *what* you want to run from *when* you run it and *with what parameters*. Understanding that separation is the key to writing efficient, correct client code.
This guide covers the basics: the prepare→bind→execute lifecycle, Arrow batch parameter binding, multi-statement transactions, and same-connection write-then-read consistency.
The runnable companion script exercises every section in order: [`docs/adbc/examples/prepared-statements-and-transactions/main.py`](https://github.com/xtdb/xtdb/tree/main/docs/src/content/docs/adbc/examples/prepared-statements-and-transactions/main.py)
## Prerequisites
[Section titled “Prerequisites”](#prerequisites)
```bash
docker run --rm -d --name xtdb -p 5432:5432 -p 9832:9832 ghcr.io/xtdb/xtdb:nightly
pip install adbc-driver-flightsql pyarrow
```
All examples connect to `grpc://localhost:9832`. Adjust the port if you mapped it differently.
Note
Use the `nightly` image for ADBC/FlightSQL work: it enables the FlightSQL listener on port 9832 by default. (Stable images from 2.2.0 onwards enable it too.)
## The statement lifecycle
[Section titled “The statement lifecycle”](#the-statement-lifecycle)
Every ADBC statement follows the same pattern:
```plaintext
setSqlQuery(sql)
│
▼
prepare() ← optional but required when binding Arrow params
│
▼
bind(arrow_batch) ← one batch of positional parameters
│
▼
execute_query() / execute_update()
│
▼
stream results (ArrowReader)
```
`prepare()` parses the SQL and builds a query plan once. `bind()` attaches a parameter batch; the batch stays on the client, with no round trip, until you execute. `execute_query()` sends the bound batch and streams results back as Arrow.
When you write `cur.execute("SELECT ... WHERE _id = ?", parameters=["alice"])` in the Python dbapi, all three steps happen implicitly in one call. The explicit lifecycle matters in two situations: hot loops where amortising the parse cost pays off, and Arrow batch binding.
## Scalar parameters
[Section titled “Scalar parameters”](#scalar-parameters)
The dbapi `execute()` call handles scalar parameters inline:
```python
import adbc_driver_flightsql.dbapi as flight_sql
with flight_sql.connect("grpc://localhost:9832") as conn:
with conn.cursor() as cur:
cur.execute(
"SELECT _id, name, price FROM products WHERE _id = ?",
parameters=["p1"],
)
print(cur.fetchone())
# ('p1', 'Widget', 9.99)
```
`parameters` is a positional list matching the `?` placeholders in the SQL. Positional binding only: named parameters are not currently supported over the FlightSQL wire.
## Prepare-once / execute-many
[Section titled “Prepare-once / execute-many”](#prepare-once--execute-many)
When you call `execute()` in a tight loop with different parameters, the driver re-parses the SQL on every iteration. The explicit prepare path amortises the cost:
```python
import adbc_driver_flightsql
import adbc_driver_manager
import pyarrow as pa
db = adbc_driver_flightsql.connect("grpc://localhost:9832")
conn = adbc_driver_manager.AdbcConnection(db)
stmt = adbc_driver_manager.AdbcStatement(conn)
stmt.set_sql_query("SELECT _id, name, price FROM products WHERE _id = ?")
stmt.prepare() # parse + plan once
for product_id in ["p1", "p2", "p3"]:
batch = pa.record_batch(
{"v0": pa.array([product_id], type=pa.string())}
)
stmt.bind(batch) # client-side, no round trip
handle, _ = stmt.execute_query()
reader = pa.RecordBatchReader._import_from_c(handle.address)
for row in reader.read_all().to_pylist():
print(f" {row['_id']}: {row['name']}, £{row['price']:.2f}")
stmt.close()
conn.close()
db.close()
```
`bind()` takes any Arrow data with `__arrow_c_array__` or `__arrow_c_stream__`. Column names in the batch don’t matter: parameters are matched positionally to the `?` placeholders.
`prepare()` is required before `bind()`. Calling `bind()` without a prior `prepare()` raises `INVALID_STATE`.
## Arrow batch parameter binding
[Section titled “Arrow batch parameter binding”](#arrow-batch-parameter-binding)
Pass a multi-row `RecordBatch` as the bound parameters so that one round trip inserts (or queries for) many rows.
```python
import pyarrow as pa
import adbc_driver_flightsql.dbapi as flight_sql
# Build a batch where each row is one INSERT execution.
# Columns map positionally to the ? placeholders in the SQL.
# The whole batch travels as a single Arrow buffer over gRPC,
# with no row-shredding and no individual round trips per row.
param_batch = pa.record_batch({
"v0": pa.array(["p4", "p5", "p6"], type=pa.string()),
"v1": pa.array(["Thingamajig", "Whatsit", "Gizmo"], type=pa.string()),
"v2": pa.array([14.99, 7.49, 19.99], type=pa.float64()),
"v3": pa.array([75, 120, 30], type=pa.int64()),
})
with flight_sql.connect("grpc://localhost:9832") as conn:
with conn.cursor() as cur:
cur.executemany(
"INSERT INTO products (_id, name, price, stock)"
" VALUES (?, ?, ?, ?)",
param_batch,
)
cur.execute("SELECT count(*) FROM products")
print(cur.fetchone()[0]) # 6 (or however many rows you had before)
```
**Use `pa.string()` (utf8), not `pa.large_utf8()`, for string columns in bound batches.** `large_utf8` is not currently supported in parameter batches over the FlightSQL wire. Non-string types (`float64`, `int64`, `int32`) work with their natural Arrow types.
Results from queries also come back as Arrow:
```python
cur.execute("SELECT _id, name FROM products ORDER BY _id")
arrow_table = cur.fetch_arrow_table() # pyarrow.Table
print(arrow_table.schema)
# _id: string
# name: string
```
`fetch_arrow_table()` collects all batches; for large result sets, use `fetchmany()` or stream via the underlying `ArrowReader`.
## Transactions
[Section titled “Transactions”](#transactions)
XTDB supports multi-statement transactions over ADBC. Use the connection-level transaction API:
```python
import adbc_driver_flightsql.dbapi as flight_sql
with flight_sql.connect("grpc://localhost:9832") as conn:
# Switch off autocommit; opens a FlightSQL BeginTransaction action.
conn.adbc_connection.set_autocommit(False)
with conn.cursor() as cur:
cur.executemany(
"INSERT INTO orders (_id, item, qty) VALUES (?, ?, ?)",
[["o1", "Widget", 10], ["o2", "Gadget", 5]],
)
# Writes are visible to reads on the same connection
# before the transaction commits.
cur.execute(
"SELECT count(*) FROM orders WHERE _id IN (?, ?)",
parameters=["o1", "o2"],
)
print(cur.fetchone()[0]) # 2
conn.adbc_connection.rollback() # EndTransaction ROLLBACK
# ↑ the two rows are gone
conn.adbc_connection.set_autocommit(False)
with conn.cursor() as cur:
cur.executemany(
"INSERT INTO orders (_id, item, qty) VALUES (?, ?, ?)",
[["o3", "Doohickey", 20]],
)
conn.adbc_connection.commit() # EndTransaction COMMIT
```
`set_autocommit(False)` calls the FlightSQL `BeginTransaction` action under the hood. `commit()` / `rollback()` call `EndTransaction` with the appropriate action. Each `set_autocommit(False)` starts a new transaction; commit or rollback ends it.
Caution
Transaction support requires the server to advertise `FLIGHT_SQL_SERVER_TRANSACTION` in its `GetSqlInfo` response (SqlInfo code 8, value `SQL_SUPPORTED_TRANSACTION_TRANSACTION`). Builds before 2026-05 do not include this advertisement; `set_autocommit(False)` raises `NOT_IMPLEMENTED`. Use the nightly image or build from main.
### ROLLBACK empties pending writes
[Section titled “ROLLBACK empties pending writes”](#rollback-empties-pending-writes)
```python
with flight_sql.connect("grpc://localhost:9832") as conn:
conn.adbc_connection.set_autocommit(False)
with conn.cursor() as cur:
cur.executemany(
"INSERT INTO orders (_id, item, qty) VALUES (?, ?, ?)",
[["o4", "Prototype", 1]],
)
# Visible on this connection before commit:
cur.execute("SELECT count(*) FROM orders WHERE _id = ?",
parameters=["o4"])
print(cur.fetchone()[0]) # 1
conn.adbc_connection.rollback()
with conn.cursor() as cur:
cur.execute("SELECT count(*) FROM orders WHERE _id = ?",
parameters=["o4"])
print(cur.fetchone()[0]) # 0; ROLLBACK erased it
```
The write was visible before rollback because the read happened on the same connection. After rollback it’s gone: neither this connection nor any other will see it.
### setAutoCommit via the dbapi Connection
[Section titled “setAutoCommit via the dbapi Connection”](#setautocommit-via-the-dbapi-connection)
The DB-API 2.0 `Connection.autocommit` attribute mirrors the underlying ADBC call:
```python
# These are equivalent:
conn.adbc_connection.set_autocommit(False)
# and (if your dbapi wrapper exposes it):
# conn.autocommit = False
```
The `adbc_connection` attribute on the dbapi `Connection` object is the raw `AdbcConnection`; use it to access ADBC-specific transaction methods that the dbapi wrapper doesn’t expose.
## Same-connection write-then-read visibility
[Section titled “Same-connection write-then-read visibility”](#same-connection-write-then-read-visibility)
Writes on a connection are visible to subsequent reads on that **same** connection without any manual `await` or sleep. The connection tracks its own write tokens and threads them through the planner:
```python
with flight_sql.connect("grpc://localhost:9832") as conn:
with conn.cursor() as cur:
cur.executemany(
"INSERT INTO products (_id, name, price, stock)"
" VALUES (?, ?, ?, ?)",
[["p9", "Overnight", 3.99, 500]],
)
# Immediately visible; no await needed.
cur.execute(
"SELECT name, price FROM products WHERE _id = ?",
parameters=["p9"],
)
print(cur.fetchone())
# ('Overnight', 3.99)
```
Cross-connection reads follow normal transactional semantics: another connection sees the write once it commits and its read snapshot advances.
## DML via `executemany`, not `execute`
[Section titled “DML via executemany, not execute”](#dml-via-executemany-not-execute)
A subtle point: the Python dbapi’s `cursor.execute()` routes all SQL, including INSERT, UPDATE, DELETE, through the FlightSQL query path (`GetFlightInfo` → `DoGet`). XTDB’s query path does not persist DML.
Use `cursor.executemany()` for DML. `executemany()` routes through `DoPut` (the update path), which calls `executeUpdate()` on the server and actually commits the write.
```python
# ✗ Does not persist on nightly / stable images:
cur.execute("INSERT INTO t (_id, v) VALUES (?, ?)", parameters=["x", 1])
# ✓ Correct, persists:
cur.executemany("INSERT INTO t (_id, v) VALUES (?, ?)", [["x", 1]])
```
This is a known mismatch between the Python dbapi specification (where `execute` handles DML) and the ADBC FlightSQL wire protocol (where DML goes through `DoPut`, not `GetFlightInfo`).
## What’s not covered here
[Section titled “What’s not covered here”](#whats-not-covered-here)
* **Bulk-loading Parquet and other file formats.** See [Bulk-load Parquet via ADBC](./bulk-ingest-from-parquet).
* **`adbc_ingest` for whole Arrow tables over the FlightSQL wire.** The one-round-trip bulk-ingest path; see [pandas / polars round-trip](./pandas-polars-round-trip). For parameterised DML, `executemany` with a `RecordBatch` (above) stays the right tool.
* **`executeSchema` / result shape introspection.** Covered in the [reference](../reference#executeschema-result-shape-without-executing).
* **Cross-connection visibility and read snapshots.** See the [reference](../reference#transactions) for the snapshot-isolation model.
# A Rust ADBC + arrow-rs pipeline against XTDB
> A Rust ADBC pipeline where Arrow types are checked at compile time end to end.
Where Python ADBC preserves your DataFrame, Rust ADBC preserves your Rust types. Query results land as `arrow::record_batch::RecordBatch` values: the same types DataFusion uses internally and the same ones `parquet::arrow::ArrowWriter` consumes. There is no row-level decode and no schema duck-typing between XTDB and the rest of your pipeline.
This guide walks the full path:
1. Connect to XTDB’s FlightSQL listener from Rust with `adbc_core` + `adbc_driver_manager`.
2. Stream a query result back as `RecordBatch`es.
3. Register those batches with DataFusion and run analytical SQL.
4. Write the aggregate out to Parquet via `parquet::arrow::ArrowWriter`.
The runnable crate is in [`examples/rust-arrow-pipeline/`](https://github.com/xtdb/xtdb/tree/main/docs/src/content/docs/adbc/examples/rust-arrow-pipeline). It’s a single file: point it at your node and change the SQL.
## Cargo.toml: a version matrix that resolves
[Section titled “Cargo.toml: a version matrix that resolves”](#cargotoml-a-version-matrix-that-resolves)
The Rust ADBC ecosystem is younger than Python’s, and the arrow / datafusion / parquet trio shares a single major version that all three crates must agree on. Mix two arrow majors in one binary and `RecordBatch` types stop unifying, producing compile errors that point at trait-impl noise rather than the underlying version skew.
A pinned set that resolves:
```toml
[dependencies]
adbc_core = "=0.23.0"
adbc_driver_manager = "=0.23.0"
adbc-driver-flightsql = "=0.1.2"
arrow = "=58.3.0"
arrow-array = "=58.3.0"
arrow-schema = "=58.3.0"
parquet = "=58.3.0"
datafusion = "=53.1.0"
tokio = { version = "=1.52.3", features = ["rt-multi-thread", "macros"] }
```
* `adbc_core` / `adbc_driver_manager` 0.23 declare `arrow-array >=53.1, <59`, so they happily resolve against the arrow 58 that datafusion 53 pulls in. You don’t need to override the resolver; do not pin arrow to 53 just because adbc\_core’s minimum is 53, since datafusion would still pull 58 alongside and you’d be back to two arrow majors in one binary.
* `adbc-driver-flightsql` is a *shim*: its `build.rs` downloads the official Apache `libadbc_driver_flightsql.{so,dylib,dll}` from the matching PyPI wheel and exposes its on-disk path as `DRIVER_PATH`. The crate defaults to native-driver version `1.9.0`, which is too old: the `adbc.ingest.target_table` / `adbc.ingest.mode` option keys landed in `1.10.0`, and several other rough edges (option dispatch, error formatting) were smoothed in `1.11.0`. Set `ADBC_FLIGHTSQL_VERSION=1.11.0` in the environment for the first `cargo build` and the wheel is cached for subsequent runs.
These versions are coupled, so the pins are exact (`=`): change them together as a set, not one at a time.
## Connecting
[Section titled “Connecting”](#connecting)
```rust
use adbc_core::{
options::{AdbcVersion, OptionDatabase},
Connection, Database, Driver, Statement,
};
use adbc_driver_flightsql::DRIVER_PATH;
use adbc_driver_manager::ManagedDriver;
let mut driver = ManagedDriver::load_dynamic_from_filename(
DRIVER_PATH,
None,
AdbcVersion::default(),
)?;
let database = driver
.new_database_with_opts([(OptionDatabase::Uri, "grpc://localhost:9832".into())])?;
let mut conn = database.new_connection()?;
```
`load_dynamic_from_filename` does the `dlopen` and resolves the entry point. `ManagedDriver` implements `adbc_core::Driver` directly: every method below is the same trait you’d call against any other ADBC backend.
`AdbcVersion::default()` is `V110`, the version XTDB and the current native FlightSQL driver use. If you ever see “Unknown statement option” errors that look intercepted client-side, the version is the first thing to check.
## Query → RecordBatch stream
[Section titled “Query → RecordBatch stream”](#query--recordbatch-stream)
`Statement::execute` returns `Box`, a streaming Arrow reader. Iterate it batch-at-a-time for large results, or `collect` for small ones:
```rust
let mut q = conn.new_statement()?;
q.set_sql_query("SELECT _id, region, amount FROM orders")?;
let reader = q.execute()?;
let result_schema = reader.schema();
let batches: Vec = reader.collect::>()?;
```
The Flight gRPC framing copies the Arrow IPC bytes once at the gRPC boundary on each side. After that the buffers are native Arrow, and DataFusion and parquet-rs operate on them directly without decoding or widening. So this isn’t zero-copy across the network boundary, but the data stays Arrow-shaped at every step within the process.
## Handing off to DataFusion
[Section titled “Handing off to DataFusion”](#handing-off-to-datafusion)
`SessionContext::register_batch` takes a `(name, RecordBatch)` pair and registers it as an in-memory table. For multi-batch results, concatenate first with `arrow::compute::concat_batches` (one Vec scan, no copies of the column buffers, since it stitches the existing arrays into the new batch):
```rust
use datafusion::prelude::SessionContext;
let ctx = SessionContext::new();
ctx.register_batch(
"orders",
arrow::compute::concat_batches(&result_schema, &batches)?,
)?;
let df = ctx
.sql("SELECT region, COUNT(*) AS n_orders, SUM(amount) AS total_amount
FROM orders GROUP BY region ORDER BY total_amount DESC")
.await?;
let agg_batches: Vec = df.collect().await?;
```
`df.collect().await?` runs the DataFusion plan and returns another `Vec`: same Arrow types, same buffer layout. The Tokio runtime is here because DataFusion’s surface is async; everything else in this pipeline is sync.
For multi-table queries (join an XTDB table against a Parquet file on disk, say) register each side independently and write the join in DataFusion SQL. That’s the main reason to put DataFusion in the middle rather than wiring the FlightSQL stream straight to a Parquet writer: it gives you a query layer over heterogeneous Arrow sources without leaving the Arrow type system.
## Writing Parquet
[Section titled “Writing Parquet”](#writing-parquet)
`parquet::arrow::ArrowWriter` takes the Arrow schema and accepts each `RecordBatch`:
```rust
use parquet::arrow::ArrowWriter;
use parquet::file::properties::WriterProperties;
let agg_schema = agg_batches.first().map(|b| b.schema())
.ok_or("DataFusion returned no batches")?;
let file = std::fs::File::create("orders-by-region.parquet")?;
let mut writer = ArrowWriter::try_new(file, agg_schema, Some(WriterProperties::builder().build()))?;
for batch in &agg_batches {
writer.write(batch)?;
}
writer.close()?;
```
`writer.close()` flushes the row-group footers: call it explicitly rather than relying on `Drop`. Drop will swallow any error; `close()` returns one.
Properties default to snappy compression and reasonable row-group sizing; reach for `WriterProperties::builder()` knobs (codec, page size, dictionary encoding) when you have measurements that say you should.
## Lifecycle notes
[Section titled “Lifecycle notes”](#lifecycle-notes)
A few Rust-specific corners worth knowing about:
* `ManagedDriver`, `ManagedDatabase`, `ManagedConnection`, `ManagedStatement` are all `Arc`-wrapped internally: cheap to clone, safe across threads. Don’t reach for `Arc>` around them yourself.
* The `RecordBatchReader` returned by `execute()` borrows nothing from the statement; the statement can be dropped once the reader is constructed. Lifetime is `'static`, which is what makes `collect` and async handoff to DataFusion straightforward.
* `execute_update()` returns `Result>`, where `None` means “row count unknown” rather than “zero rows”. XTDB returns `None` for most DML; treat absence as success, not failure.
* The native FlightSQL driver library is loaded on first use and stays loaded for the process lifetime. Open one `ManagedDriver` at startup and reuse it; repeated `load_dynamic_from_filename` calls work but waste work.
## Running it
[Section titled “Running it”](#running-it)
This needs the FlightSQL listener, which the `nightly` image enables by default on port 9832 (stable images from 2.2.0 onwards do too):
```sh
docker run --rm -d --name xtdb-g6 \
-p 5432:5432 -p 9832:9832 \
ghcr.io/xtdb/xtdb:nightly
cd docs/src/content/docs/adbc/examples/rust-arrow-pipeline
ADBC_FLIGHTSQL_VERSION=1.11.0 cargo run --release
```
Output:
```plaintext
seeded orders
got 1 batch(es), 6 row(s) total from XTDB
-- DataFusion result --
+--------+----------+--------------+
| region | n_orders | total_amount |
+--------+----------+--------------+
| us | 3 | 540 |
| eu | 2 | 350 |
| apac | 1 | 175 |
+--------+----------+--------------+
wrote orders-by-region.parquet
```
The example seeds via plain SQL `INSERT` to stay self-contained. To bulk-ingest an Arrow batch instead, set `adbc.ingest.target_table` and call `execute_update`. This issues the same FlightSQL `CommandStatementIngest` the [bulk-ingest-from-parquet guide](./bulk-ingest-from-parquet) uses from Python, and works identically from any ADBC client.
## One type system end to end
[Section titled “One type system end to end”](#one-type-system-end-to-end)
Everything from `q.execute()?` through `writer.close()?` is the same Arrow type system. `RecordBatch`, `Schema`, `Field`, `ArrayRef`: one set of types, one set of compile-time guarantees. Add a `Vec` column to your query and DataFusion’s SQL planner sees an `Int64` field, the parquet writer encodes an INT64 page, your downstream consumers see whatever they consume from arrow-rs. No string-typed schema metadata, no per-column conversion adapters, no type-widening surprises.
Where the Python path preserves your DataFrame across the round trip, the Rust path preserves what `cargo check` verifies: the Arrow types line up at compile time.
# Streaming XTDB results into DuckDB via Arrow
> Combine XTDB's bitemporal data with DuckDB-resident data over Arrow, with no serialise/deserialise step.
When you already have data in DuckDB, ADBC lets you bring XTDB’s bitemporal data alongside it without a copy: both are Arrow-native, so a query result streams from XTDB straight into DuckDB to be joined with what’s already there. The worked scenario: take a bitemporal trade snapshot from XTDB as of Q4 2024 and join it to a counterparty-tier lookup table held in DuckDB.
## Prerequisites
[Section titled “Prerequisites”](#prerequisites)
A running XTDB node with the FlightSQL listener on port 9832 and the pgwire server on port 5432. The nightly Docker image enables both by default:
```sh
docker run --rm -d --name xtdb-duckdb-demo \
-p 5432:5432 -p 9832:9832 ghcr.io/xtdb/xtdb:nightly
```
Install the Python dependencies:
```sh
pip install adbc-driver-flightsql pyarrow duckdb psycopg
```
`psycopg` seeds the trades over pgwire, so no external `psql` binary is required.
## The scenario
[Section titled “The scenario”](#the-scenario)
Seven trades are stored in XTDB with explicit valid-time ranges. One of them, CommerzBank’s T005, expired on `2024-06-30` and should be absent from the end-of-Q4 snapshot even though it was physically ingested. The question: as of 2024-12-31, what’s the total trade value per counterparty tier?
The counterparty-to-tier mapping lives in DuckDB as a local dimension table (Parquet, CSV, or in-memory; it does not need to be in XTDB).
## Step 1: Seed XTDB with bitemporal trades
[Section titled “Step 1: Seed XTDB with bitemporal trades”](#step-1-seed-xtdb-with-bitemporal-trades)
Trades arrive via the normal write path. Use `_valid_from` and `_valid_to` to record when each trade *was true*: the valid-time axis.
```python
import psycopg
from textwrap import dedent
SEED_SQL = dedent("""\
INSERT INTO trades (_id, counterparty, notional, currency, _valid_from, _valid_to)
VALUES
('T001','Barclays', 1500000.0,'GBP',TIMESTAMP '2024-01-15 00:00:00',TIMESTAMP '9999-12-31 00:00:00'),
('T002','Barclays', 2000000.0,'GBP',TIMESTAMP '2024-03-01 00:00:00',TIMESTAMP '9999-12-31 00:00:00'),
('T003','JPMorgan', 3200000.0,'USD',TIMESTAMP '2024-02-10 00:00:00',TIMESTAMP '9999-12-31 00:00:00'),
('T004','DeutscheBank', 800000.0,'EUR',TIMESTAMP '2024-04-01 00:00:00',TIMESTAMP '9999-12-31 00:00:00'),
('T005','CommerzBank', 1100000.0,'EUR',TIMESTAMP '2024-01-01 00:00:00',TIMESTAMP '2024-06-30 00:00:00'),
('T006','SocGen', 950000.0,'EUR',TIMESTAMP '2024-06-01 00:00:00',TIMESTAMP '9999-12-31 00:00:00'),
('T007','SocGen', 1750000.0,'EUR',TIMESTAMP '2024-09-15 00:00:00',TIMESTAMP '9999-12-31 00:00:00')
""")
PG_URI = "postgresql://localhost:5432/xtdb"
with psycopg.connect(PG_URI, user="xtdb", autocommit=True) as pg:
with pg.cursor() as cur:
cur.execute(SEED_SQL)
```
`_valid_from`/`_valid_to` in the INSERT body override the default (`now` → `end-of-time`) so XTDB records each trade’s actual validity window.
## Step 2: Pull the Q4 snapshot via ADBC
[Section titled “Step 2: Pull the Q4 snapshot via ADBC”](#step-2-pull-the-q4-snapshot-via-adbc)
`FOR VALID_TIME AS OF` pins the query to a single instant. XTDB returns only the rows whose valid-time period *contains* that instant. T005 (CommerzBank, valid to `2024-06-30`) is excluded.
```python
import pyarrow as pa
import adbc_driver_flightsql.dbapi as flight_sql
SNAPSHOT_SQL = """\
SELECT _id, counterparty, notional, currency
FROM trades
FOR VALID_TIME AS OF TIMESTAMP '2024-12-31 23:59:59'
ORDER BY _id
"""
FSQL_URI = "grpc://localhost:9832"
with flight_sql.connect(FSQL_URI) as conn:
with conn.cursor() as cur:
cur.execute(SNAPSHOT_SQL)
snapshot: pa.Table = cur.fetch_arrow_table()
```
`fetch_arrow_table()` returns a `pyarrow.Table`. The data travels from XTDB’s in-memory Arrow buffers across the FlightSQL gRPC stream and lands in the client as Arrow, so it isn’t decoded row by row or widened through a text wire format.
`snapshot` now holds 6 rows: T001–T004, T006, T007.
## Step 3: Register the snapshot into DuckDB
[Section titled “Step 3: Register the snapshot into DuckDB”](#step-3-register-the-snapshot-into-duckdb)
```python
import duckdb
duck = duckdb.connect() # in-memory DuckDB instance
duck.register("xtdb_trades", snapshot)
```
`duckdb.register()` accepts any object that exposes the Arrow C Data Interface: a `pyarrow.Table`, `RecordBatch`, polars `DataFrame`, etc. DuckDB operates directly on the Arrow buffers XTDB produced. No copy, no decode.
## Step 4: Create the counterparty-tier dimension in DuckDB
[Section titled “Step 4: Create the counterparty-tier dimension in DuckDB”](#step-4-create-the-counterparty-tier-dimension-in-duckdb)
Enrichment data that doesn’t belong in XTDB lives here. In production this is typically a Parquet file on the local filesystem:
```python
duck.execute("""\
CREATE TABLE counterparty_tiers AS
SELECT * FROM (VALUES
('Barclays', 'Gold'),
('JPMorgan', 'Gold'),
('DeutscheBank', 'Silver'),
('SocGen', 'Silver'),
('CommerzBank', 'Bronze')
) AS t(counterparty, tier)
""")
```
Or from a Parquet file:
```python
duck.execute("CREATE TABLE counterparty_tiers AS SELECT * FROM 'tiers.parquet'")
```
## Step 5: Join and aggregate in DuckDB
[Section titled “Step 5: Join and aggregate in DuckDB”](#step-5-join-and-aggregate-in-duckdb)
The join runs inside DuckDB, over the Arrow buffers XTDB produced, combining the bitemporal snapshot with DuckDB’s local lookup table. No round-trip to XTDB, no re-serialisation.
```python
result: pa.Table = duck.execute("""\
SELECT
ct.tier,
count(*) AS trade_count,
sum(t.notional) AS total_notional,
round(avg(t.notional), 0) AS avg_notional
FROM xtdb_trades AS t
JOIN counterparty_tiers AS ct ON t.counterparty = ct.counterparty
GROUP BY ct.tier
ORDER BY total_notional DESC
""").arrow().read_all()
```
Output:
```plaintext
Exposure by counterparty tier, as-of Q4 2024 end:
Tier Trades Total Notional Avg Notional
---------- ------ ---------------- --------------
Gold 3 6,700,000 2,233,333
Silver 3 3,500,000 1,166,667
```
CommerzBank (Bronze, T005) is absent because it did not exist at Q4 end. The valid-time filter happened at the XTDB layer before any data crossed the wire.
## Streaming batches instead of materialising the whole snapshot
[Section titled “Streaming batches instead of materialising the whole snapshot”](#streaming-batches-instead-of-materialising-the-whole-snapshot)
For result sets too large to fit in client memory, stream Arrow batches one at a time rather than calling `fetch_arrow_table()`:
```python
import adbc_driver_flightsql as flight_sql_raw
db = flight_sql_raw.connect(FSQL_URI)
conn = db.new_connection()
stmt = conn.new_statement()
stmt.set_sql_query(SNAPSHOT_SQL)
result, schema = stmt.execute_query()
# result is an ArrowReader; each iteration yields one RecordBatch.
for batch in result:
duck.register("xtdb_batch", batch)
duck.execute("INSERT INTO aggregated SELECT ..., FROM xtdb_batch")
result.close()
conn.close()
db.close()
```
The tradeoff:
* `fetch_arrow_table()` materialises the full snapshot in one shot: simple, and the right default for snapshots that fit in RAM.
* The `ArrowReader` path streams batch-by-batch: the right choice when the XTDB result set is large and you can incrementally fold each batch into an ongoing DuckDB aggregate without materialising the whole thing.
## Writing results back
[Section titled “Writing results back”](#writing-results-back)
DuckDB query results can go back to XTDB via bulk ingest, or out to Parquet:
**Back to XTDB:**
```python
# result is a pyarrow.Table; annotate with _id before ingest.
import pyarrow.compute as pc
result_with_id = result.append_column(
"_id", pa.array([f"tier-summary-{r['tier']}" for r in result.to_pylist()])
)
with flight_sql.connect(FSQL_URI) as conn:
with conn.cursor() as cur:
cur.adbc_ingest("tier_summaries", result_with_id, mode="create_append")
```
**To Parquet:**
```python
import pyarrow.parquet as pq
pq.write_table(result, "tier_exposure_q4_2024.parquet")
```
## Runnable example
[Section titled “Runnable example”](#runnable-example)
A self-contained script that runs the full scenario is in [`examples/streaming-into-duckdb/main.py`](https://github.com/xtdb/xtdb/tree/main/docs/src/content/docs/adbc/examples/streaming-into-duckdb/main.py).
```sh
docker run --rm -d --name xtdb-g5 -p 5432:5432 -p 9832:9832 ghcr.io/xtdb/xtdb:nightly
pip install adbc-driver-flightsql pyarrow duckdb psycopg
python docs/src/content/docs/adbc/examples/streaming-into-duckdb/main.py
docker rm -f xtdb-g5
```
## Why this works without a copy
[Section titled “Why this works without a copy”](#why-this-works-without-a-copy)
XTDB’s query engine produces Arrow `RecordBatch` objects internally. The FlightSQL shim packages those batches into gRPC `DoGet` streams as-is. The ADBC FlightSQL driver on the Python side decodes the gRPC framing and reconstructs the Arrow buffers in the client process. `duckdb.register()` takes the Arrow C Data Interface pointer to those buffers: DuckDB’s planner sees the Arrow schema and DuckDB’s executor reads the data in-place.
The data moves as: XTDB in-memory Arrow → gRPC wire encoding → pyarrow Arrow buffer → DuckDB execution. There is no intermediate JSON, CSV, Postgres text wire, or pickle. The gRPC serialisation is the only encode/decode step, and it is Arrow’s own IPC format.
# ADBC reference
> The ADBC surface XTDB supports, in-process and over FlightSQL, with its XTDB-specific behaviour.
XTDB exposes [ADBC](https://arrow.apache.org/adbc/), the Arrow Database Connectivity standard, through two surfaces:
* **In-process**, via `node.connect()` on the JVM, which returns an `org.apache.arrow.adbc.core.AdbcConnection`. Zero copies, direct access to the in-memory Arrow buffers.
* **Over the wire**, via the [Apache Arrow Flight SQL](https://arrow.apache.org/docs/format/FlightSql.html) server bundled into XTDB. Any ADBC FlightSQL driver (Python, Rust, Go, C, R, Java) connects to it.
The FlightSQL producer is a thin shim over the same in-process `AdbcConnection` / `AdbcStatement` implementation, so a behaviour documented here holds on either surface, barring the per-client caveats noted below. Signatures and examples are given in the in-process Kotlin API; over the wire the same operations are whatever your driver’s ADBC binding calls them.
## Connecting
[Section titled “Connecting”](#connecting)
### In-process (Kotlin / JVM)
[Section titled “In-process (Kotlin / JVM)”](#in-process-kotlin--jvm)
An `org.apache.arrow.adbc.core.AdbcConnection` is obtained from a running node via `node.connect()`:
```kotlin
import xtdb.api.Xtdb
Xtdb.openNode().use { node ->
node.connect().use { conn ->
conn.createStatement().use { stmt ->
stmt.setSqlQuery("SELECT 1")
stmt.executeQuery().use { result ->
// result.reader: org.apache.arrow.vector.ipc.ArrowReader
}
}
}
}
```
### Over the wire (FlightSQL)
[Section titled “Over the wire (FlightSQL)”](#over-the-wire-flightsql)
Enable the FlightSQL listener in your node config; the [Docker standalone image](/intro/installation-via-docker) does this by default on port `9832`:
```yaml
flightSql:
host: '*'
port: 9832
```
Then connect with any ADBC FlightSQL driver pointed at `grpc://localhost:9832`. Connection setup is driver-specific: see the connection snippet on the [Python](/drivers/python#arrow-native-access-via-adbc), [Java](/drivers/java#arrow-native-access-via-adbc), [Kotlin](/drivers/kotlin#arrow-native-access-via-adbc), or [Go](/drivers/go#arrow-native-access-via-adbc) driver page, or the [Apache ADBC driver matrix](https://arrow.apache.org/adbc/current/driver/flight_sql.html) for other languages.
TLS and authentication are not applied to the FlightSQL listener (XTDB’s [authentication](/ops/config/authentication) covers the pgwire listener only); front it with a TLS-terminating proxy in production.
## Statements
[Section titled “Statements”](#statements)
* `createStatement()`
opens an `AdbcStatement`, the entry point for every query and DML.
* `setSqlQuery(sql)` / `prepare()` / `bind(batch)` / `executeQuery()`
the standard ADBC statement lifecycle. `prepare()` is optional but required before `bind()`; `bind()` takes one Arrow record batch of parameters. `executeQuery()` returns an `ArrowReader` that yields one Arrow batch at a time, so large result sets need not fit in memory.
```kotlin
val stmt = conn.createStatement()
stmt.setSqlQuery("SELECT ?, ?")
stmt.prepare()
stmt.bind(argBatch)
val result = stmt.executeQuery()
```
* `executeUpdate()`
runs DML. Returns `-1` (XTDB does not pre-count affected rows). Effects are visible to the next query on the same connection (see [Transactions](#transactions) for multi-statement semantics).
* `executeSchema()`
returns the Arrow schema of a query’s result set without running it, for tooling that needs the result columns up front. Works on prepared statements (read from `getResultSetSchema`) and ad-hoc queries (the wire path opens a transient `PreparedQuery`). Because it runs before any bind, a result schema that depends on parameter types is resolved against null-typed placeholders. For `SELECT cols FROM t WHERE _id = ?` (where the projection doesn’t depend on the parameter) the schema is accurate; a query that projects a parameter directly (`SELECT ?`, `SELECT ? + 1`) comes back `null`-typed for those fields. Project through a column expression that fixes the type if you need it resolved.
## Bulk ingest
[Section titled “Bulk ingest”](#bulk-ingest)
* `bulkIngest(table, mode)`
lands an Arrow table (or any Arrow-shaped data: record batches, streams, anything exposing the Arrow C Data Interface) in `table` in a single round trip. Over the wire it maps to the FlightSQL `CommandStatementIngest` command; batches stream in one at a time, so the whole table needn’t fit in memory at either end. Each call commits atomically on its own, regardless of the connection’s commit mode.
```kotlin
conn.bulkIngest("people", BulkIngestMode.CREATE_APPEND).use { stmt ->
stmt.bind(peopleBatch) // _id, name, age …
stmt.executeUpdate()
}
```
Because XTDB creates tables on demand, the ingest modes either coincide or don’t apply:
| Mode | Behaviour |
| -------------------------------- | ----------------------------------------------------------------------------------------------- |
| `create` | Accepted. Table is auto-created if missing. |
| `append` | Accepted. Upserts on `_id`. |
| `create_append` | Accepted (the common case). |
| `replace` | **Rejected** (`INVALID_ARGUMENT`). Would require an explicit `ERASE` step. |
| `create` with fail-if-exists | **Rejected.** XTDB auto-creates; “fail if exists” can’t be honoured without an existence check. |
| `append` with fail-if-not-exists | **Rejected.** XTDB auto-creates on insert; silently accepting would violate the ADBC contract. |
Further constraints:
* Every row must have an `_id` column. Rows without one are rejected; materialise an `_id` client-side before ingesting if your source Arrow lacks one.
* A temporal `_valid_from` / `_valid_to` column must be a `timestamp`, not a `date`.
* A per-call catalog override is rejected (the connection-scoped catalog is the only source of truth); a per-call schema override is honoured, defaulting to `public`.
Mode rejections return a descriptive gRPC `INVALID_ARGUMENT`. Other ingest-time failures are not yet uniformly mapped: a missing `_id` surfaces as gRPC `INTERNAL`, so match on the message, not the status code, until that mapping is tightened.
## Transactions
[Section titled “Transactions”](#transactions)
* `autoCommit = false` / `commit()` / `rollback()`
multi-statement transactions, on both surfaces. Switch off autocommit, run statements, then commit or roll back on the connection.
```kotlin
conn.autoCommit = false
conn.createStatement().use { stmt ->
stmt.setSqlQuery("INSERT INTO users (_id, name) VALUES ('alice', 'Alice')")
stmt.executeUpdate()
}
conn.commit()
```
Because XTDB advertises FlightSQL transaction support (`FLIGHT_SQL_SERVER_TRANSACTION`, SqlInfo id 8), a PEP 249 wire client (e.g. the Python dbapi) defaults to manual-commit: DML stays in an uncommitted transaction until you commit. `bulkIngest` is the exception (each call commits on its own).
**Visibility inside an open transaction.** XTDB buffers a transaction’s DML and applies it atomically on `COMMIT`, so reads on the same connection do **not** see that transaction’s own pending writes before it commits. A `SELECT` issued between an uncommitted `INSERT` and the `COMMIT` returns the pre-transaction state.
**Committed-write visibility.** Once a write is committed (in autocommit mode, or after `commit()`), subsequent reads on the same connection see it with no manual `await`: the connection tracks its own write tokens and threads them through the planner. Cross-connection visibility follows the usual transactional semantics; another connection sees the write once it commits and its read snapshot advances.
See [Prepared statements and transactions](/adbc/guides/prepared-statements-and-transactions) for the full lifecycle, including the `execute` vs `executemany` DML routing on the Python dbapi.
## Metadata
[Section titled “Metadata”](#metadata)
* `getObjects(depth, …)`
returns the catalog → schema → table → column tree, to the requested `depth`. At `depth = ALL` each table’s Arrow schema is carried as bytes in the standard `table_schema` `VarBinaryVector`, which the client deserialises into a `Schema`.
* `getTableSchema(catalog, schema, table)`
returns the Arrow schema of a single table.
```kotlin
val objs = conn.getObjects(GetObjectsDepth.ALL, null, "public", "users", null, null)
val schema = conn.getTableSchema(null, "public", "users")
```
Both reflect **live data**, not just flushed-to-block state: freshly-inserted rows show up immediately, the same way they do via SQL `SELECT`.
* `getTableTypes()`
returns `TABLE` (XTDB has one table type).
* `getInfo(…)`
returns `VENDOR_NAME = "XTDB"`, `DRIVER_NAME = "XTDB ADBC Driver"`, and version fields (currently placeholder strings).
## Session options
[Section titled “Session options”](#session-options)
* `getCurrentCatalog()` / `getCurrentDbSchema()`
return the session catalog (default `xtdb`) and schema (`public`). Read via `getSessionOptions`, a pure getter that does not create a session, so probing doesn’t leak one.
* `setSessionOptions("catalog", db)`
selects the database for the session. The value is validated against the node’s known databases: an unknown name returns `INVALID_VALUE`, an empty string clears it. Setting it creates a FlightSQL session; the server issues a cookie the client must keep across calls for the option to persist.
* `closeSession()`
ends the session, closes its connections, and invalidates the cookie.
The schema is not settable: `public` is the only accepted value (a confirming no-op), anything else is rejected.
## Not supported
[Section titled “Not supported”](#not-supported)
* Setting the `schema` session option to anything but `public`.
* Bulk-ingest `replace` and existence-check modes (rejected with an explanatory `INVALID_ARGUMENT`).
* Per-call catalog override on bulk ingest.
* The Substrait variant of `executeSchema` (`getSchemaSubstraitPlan`): no current driver consumer.
* `getCurrentCatalog` / `getCurrentDbSchema` on the Java FlightSQL client: an upstream Apache ADBC gap (its Java client doesn’t query `getSessionOptions`), not an XTDB limitation. The in-process JVM connection is unaffected.
* Parameter type inference for `executeSchema` (placeholder types only).
* TLS / auth on the FlightSQL listener.
# ADBC tutorial: XTDB end-to-end in Python
> An Arrow-native walkthrough: install the driver, connect, ingest, query, transact, and time-travel.
The tutorial is Python-first: `adbc_driver_flightsql` + `pyarrow` keep results in Arrow from XTDB to your process, with no intermediate decode. A complete, runnable version of every snippet here lives in [`examples/tutorial/main.py`](https://github.com/xtdb/xtdb/tree/main/docs/src/content/docs/adbc/examples/tutorial/main.py).
## What you’ll build
[Section titled “What you’ll build”](#what-youll-build)
A small worked example: load a `pyarrow.Table` of historical FX trades into XTDB, run analytical queries against it, add new trades, and travel back in time to the state before they arrived. It covers bulk ingest, parameterised queries, introspection, and `executeSchema`.
## 1. Prerequisites
[Section titled “1. Prerequisites”](#1-prerequisites)
You need a Python 3.10+ environment and Docker.
```bash
pip install adbc-driver-flightsql pyarrow pandas
docker run --rm -d --name xtdb -p 5432:5432 -p 9832:9832 ghcr.io/xtdb/xtdb:nightly
```
The standalone Docker image starts both the PostgreSQL wire server (port 5432) and the FlightSQL gRPC server (port 9832). The `nightly` image enables FlightSQL by default, as do stable images from 2.2.0 onwards.
## 2. Connecting
[Section titled “2. Connecting”](#2-connecting)
```python
import adbc_driver_flightsql.dbapi as flight_sql
conn = flight_sql.connect("grpc://localhost:9832")
```
The connection string is a standard gRPC URI. `flight_sql.connect` returns a DB-API 2.0 `Connection` object and can also be used as a context manager.
For JVM readers: the in-process `node.connect()` path requires no network hop and no gRPC; see the [reference](/adbc/reference#in-process-kotlin--jvm) for the Kotlin API.
## 3. Your first query
[Section titled “3. Your first query”](#3-your-first-query)
```python
with conn.cursor() as cur:
cur.execute("SELECT 1")
result = cur.fetch_arrow_table()
print(result.schema)
print(result.to_pylist())
```
Expected output:
```plaintext
_column_1: int64 not null
[{'_column_1': 1}]
```
`fetch_arrow_table()` returns a `pyarrow.Table`, not Python rows or tuples. Results arrive as Arrow batches and stay in Arrow form from XTDB’s storage layer into your process, with no row-by-row decode.
## 4. Bulk ingest
[Section titled “4. Bulk ingest”](#4-bulk-ingest)
Build the dataset of ten FX trades covering three currency pairs:
```python
import pyarrow as pa
from datetime import datetime, timezone
trades = pa.table({
"_id": pa.array([
"t001", "t002", "t003", "t004", "t005",
"t006", "t007", "t008", "t009", "t010",
]),
"symbol": pa.array([
"EURUSD", "GBPUSD", "EURUSD", "USDJPY", "GBPUSD",
"EURUSD", "USDJPY", "GBPUSD", "EURUSD", "USDJPY",
]),
"qty": pa.array(
[100_000, 250_000, 75_000, 500_000, 180_000,
320_000, 90_000, 420_000, 110_000, 660_000],
type=pa.int64(),
),
"price": pa.array(
[1.0921, 1.2734, 1.0918, 148.25, 1.2741,
1.0935, 148.10, 1.2728, 1.0942, 148.30],
type=pa.float64(),
),
"traded_at": pa.array(
[
datetime(2024, 1, 15, 9, 0, tzinfo=timezone.utc),
datetime(2024, 1, 15, 9, 5, tzinfo=timezone.utc),
datetime(2024, 1, 15, 9, 10, tzinfo=timezone.utc),
datetime(2024, 1, 15, 9, 15, tzinfo=timezone.utc),
datetime(2024, 1, 15, 9, 20, tzinfo=timezone.utc),
datetime(2024, 1, 15, 10, 0, tzinfo=timezone.utc),
datetime(2024, 1, 15, 10, 5, tzinfo=timezone.utc),
datetime(2024, 1, 15, 10, 10, tzinfo=timezone.utc),
datetime(2024, 1, 15, 10, 15, tzinfo=timezone.utc),
datetime(2024, 1, 15, 10, 20, tzinfo=timezone.utc),
],
type=pa.timestamp("us", tz="UTC"),
),
})
```
Ingest in one round trip:
```python
with conn.cursor() as cur:
cur.adbc_ingest("trades", trades, mode="create_append")
```
XTDB auto-creates the `trades` table. The table name you pass becomes the target, and XTDB infers the schema from the data, so no `CREATE TABLE` is required first (you can still declare one explicitly if you want). Every row must have an `_id` column: XTDB’s document model requires it.
Verify the round-trip:
```python
with conn.cursor() as cur:
cur.execute("SELECT * FROM trades ORDER BY _id")
back = cur.fetch_arrow_table()
print(back.num_rows, "rows")
print(back.schema)
```
Expected output:
```plaintext
10 rows
_id: string
price: double
qty: int64
symbol: string
traded_at: timestamp[us, tz=UTC]
```
The types come back exactly as you put them in: no widening through a Postgres text protocol, no timestamp-to-string conversion.
## 5. Querying with parameters
[Section titled “5. Querying with parameters”](#5-querying-with-parameters)
Use `?` for positional parameters:
```python
with conn.cursor() as cur:
cur.execute(
"SELECT _id, symbol, qty, price FROM trades WHERE symbol = ? ORDER BY _id",
parameters=["EURUSD"],
)
result = cur.fetch_arrow_table()
print(f"EURUSD trades: {result.num_rows} rows")
for row in result.to_pylist():
print(f" {row['_id']} qty={row['qty']:>7,} price={row['price']:.4f}")
```
Expected output:
```plaintext
EURUSD trades: 4 rows
t001 qty=100,000 price=1.0921
t003 qty= 75,000 price=1.0918
t006 qty=320,000 price=1.0935
t009 qty=110,000 price=1.0942
```
The `parameters` list maps positionally to the `?` placeholders. The result is still a `pyarrow.Table`: the type system is unaffected by the parameter binding.
## 6. Write visibility
[Section titled “6. Write visibility”](#6-write-visibility)
The dbapi defaults to manual-commit, so for ingest-and-query scripts connect with `autocommit=True` and each statement commits as it runs:
```python
conn = flight_sql.connect("grpc://localhost:9832", autocommit=True)
```
`adbc_ingest` commits atomically on its own regardless of commit mode, which is why the ingests in this tutorial are visible without any extra step. For the full commit-mode, visibility, and multi-statement transaction rules see [Transactions](/adbc/reference#transactions) in the reference.
A committed write is visible to subsequent reads on the same connection, with no explicit synchronisation step:
```python
extra = pa.table({
"_id": pa.array(["t011", "t012"]),
"symbol": pa.array(["EURGBP", "EURGBP"]),
"qty": pa.array([60_000, 40_000], type=pa.int64()),
"price": pa.array([0.8571, 0.8569], type=pa.float64()),
})
with conn.cursor() as cur:
cur.adbc_ingest("trades", extra, mode="create_append")
# Same-connection read; sees the rows immediately.
with conn.cursor() as cur:
cur.execute("SELECT count(*) FROM trades WHERE symbol = 'EURGBP'")
n = cur.fetch_arrow_table().to_pylist()[0]["_column_1"]
print(f"EURGBP rows: {n}") # 2
with conn.cursor() as cur:
cur.execute("SELECT count(*) FROM trades")
total = cur.fetch_arrow_table().to_pylist()[0]["_column_1"]
print(f"Total trades: {total}") # 12
```
Expected output:
```plaintext
EURGBP rows: 2
Total trades: 12
```
The `count(*)` immediately after the ingest sees the just-written rows.
## 7. Introspection: `getObjects` / `getTableSchema`
[Section titled “7. Introspection: getObjects / getTableSchema”](#7-introspection-getobjects--gettableschema)
Discover what’s in the database without running a query.
**`adbc_get_objects`** returns the full catalog → schema → table → column tree as an Arrow reader:
```python
reader = conn.adbc_get_objects(depth="all", db_schema_filter="public")
tbl = reader.read_all()
print(f"Catalog rows returned: {tbl.num_rows}")
```
Expected output:
```plaintext
Catalog rows returned: 1
```
The Arrow result encodes the entire schema tree in ADBC’s standard nested-struct format. Tooling that needs to walk the catalog (IDE autocomplete, dataframe pipeline builders) can consume this directly without issuing any SQL.
**`adbc_get_table_schema`** returns a `pyarrow.Schema` for a single table:
```python
schema = conn.adbc_get_table_schema("trades", db_schema_filter="public")
for field in schema:
print(f" {field.name}: {field.type}")
```
Expected output:
```plaintext
_id: string
price: double
qty: int64
symbol: string
traded_at: timestamp[us, tz=UTC]
```
Column types reflect **live data**: freshly-ingested rows show up here immediately, the same way they show up via SQL `SELECT`.
## 8. `executeSchema`: result shape without running
[Section titled “8. executeSchema: result shape without running”](#8-executeschema-result-shape-without-running)
`executeSchema` returns the Arrow schema of a query’s result set without executing the query. This lets pipeline builders and schema-on-read consumers learn the result columns before paying for a full execution.
```python
with conn.cursor() as cur:
schema = cur.adbc_execute_schema(
"SELECT _id, symbol, qty, price FROM trades WHERE symbol = ?"
)
print("Result schema:")
for field in schema:
print(f" {field.name}: {field.type}")
```
Expected output:
```plaintext
Result schema:
_id: string
symbol: string
qty: int64
price: double
```
Note on parameter types: the schema is computed before any bind, so XTDB synthesises null-typed placeholder fields for `?` positions. For queries where the projection does not depend on the parameter value, which covers the common `SELECT cols FROM t WHERE id = ?` shape, the returned schema is accurate. For queries that project the parameter directly (`SELECT ?`, `SELECT ? + 1`), the result field types will be placeholder-typed rather than the type you would eventually bind. Workaround: project through a column expression that fixes the type.
## 9. Bitemporality: `FOR SYSTEM_TIME AS OF`
[Section titled “9. Bitemporality: FOR SYSTEM\_TIME AS OF”](#9-bitemporality-for-system_time-as-of)
XTDB records the wall-clock time at which every row was committed. You can query the database as it stood at any point in the past using `FOR SYSTEM_TIME AS OF`.
Capture a checkpoint before inserting a new trade:
```python
import time
from datetime import datetime, timezone
checkpoint = datetime.now(timezone.utc)
time.sleep(0.1) # ensure the next write has a strictly later system time
new_trade = pa.table({
"_id": pa.array(["t013"]),
"symbol": pa.array(["USDCHF"]),
"qty": pa.array([200_000], type=pa.int64()),
"price": pa.array([0.9012], type=pa.float64()),
})
with conn.cursor() as cur:
cur.adbc_ingest("trades", new_trade, mode="create_append")
```
Current view, with t013 present:
```python
with conn.cursor() as cur:
cur.execute("SELECT count(*) FROM trades")
count_now = cur.fetch_arrow_table().to_pylist()[0]["_column_1"]
print(f"Total trades now: {count_now}") # 13
```
Historical view: travel back to the checkpoint, before t013 existed:
```python
ts = checkpoint.strftime("%Y-%m-%d %H:%M:%S.%f")[:-3]
with conn.cursor() as cur:
cur.execute(f"SELECT count(*) FROM trades FOR SYSTEM_TIME AS OF TIMESTAMP '{ts}+00:00'")
count_before = cur.fetch_arrow_table().to_pylist()[0]["_column_1"]
print(f"Trades AS OF checkpoint: {count_before}") # 12
```
Expected output:
```plaintext
Total trades now: 13
Trades AS OF checkpoint: 12
```
The Arrow types of temporal columns, including the `_system_from` / `_system_to` hidden columns XTDB maintains, survive the FlightSQL round-trip without widening. There is no Postgres-style text-format timestamp decode on the way back.
`FOR SYSTEM_TIME AS OF` is ordinary XTDB SQL and works equally well over the pgwire driver. The ADBC path returns the result in Arrow form rather than decoded rows.
## 10. Where next
[Section titled “10. Where next”](#10-where-next)
* **[Reference](/adbc/reference)**: the full supported ADBC surface in detail: which calls work, which don’t, per-client caveats.
* **[How-to guides](/adbc/guides)**: task-shaped recipes:
* [Bulk-load Parquet](/adbc/guides/bulk-ingest-from-parquet): load a Parquet file in one `adbc_ingest` call.
* [pandas / polars round-trip](/adbc/guides/pandas-polars-round-trip): read query results directly into a DataFrame without an intermediate copy.
* [Stream results into DuckDB](/adbc/guides/streaming-into-duckdb): feed XTDB query output into DuckDB via the Arrow C Data Interface.
* [Point-in-time feature extraction](/adbc/guides/point-in-time-feature-extraction): use `FOR SYSTEM_TIME AS OF` inside a pipeline to recreate historical feature sets.
* **[Examples](https://github.com/xtdb/xtdb/tree/main/docs/src/content/docs/adbc/examples)**: minimal hello-world programs in Python, Rust, and other languages.
# Xtplay Demo
Allows you to embed a miniature instance of [xt-fiddle](https://fiddle.xtdb.com) in the docs, with a couple added features as a bonus!
## Basic Usage
[Section titled “Basic Usage”](#basic-usage)
You can add an `Xtplay` to the page with pre-set transactions & query like so:
Run
Open in xt-play
If you want to preserve whitespace you can do this:
Run
Open in xt-play
## Hide editors
[Section titled “Hide editors”](#hide-editors)
Sometimes you just want to show of the query, you can hide the transactions like so:
Run
Open in xt-play
You can do the same with the query of course:
Run
Open in xt-play
## AutoLoad
[Section titled “AutoLoad”](#autoload)
You can tell Xtplay to load it’s results on page load by using the `autoLoad` property:
Run
Open in xt-play
This is particularly useful for [Templated Queries](#templated-queries) as we’ll see below.
## Errors
[Section titled “Errors”](#errors)
If you have an error in the transactions/query it looks like this:
Run
Open in xt-play
## System Time
[Section titled “System Time”](#system-time)
You can set system time on a transaction like so:
2020-01-01
Run
Open in xt-play
## Multiple Transactions
[Section titled “Multiple Transactions”](#multiple-transactions)
It can be useful to include multiple “batches” of transactions. Particularly for showing of valid time & system time:
2020-01-01
2020-01-02
Run
Open in xt-play
## Lone Transaction
[Section titled “Lone Transaction”](#lone-transaction)
If you have a transaction on it’s own then it won’t be rendered with an editor:
(It will still contribute to magicContext if you set one).
It will also render without an editor if you use a [Templated Query](#templated-queries).
## Magic Context
[Section titled “Magic Context”](#magic-context)
While of course you can use hidden `Txs` to include transactions previously executed on the page but that can get tedious.
Instead you can tell the component to look at transactions from *previous* fiddles on the page. Note that it will only look for transactions from fiddles with the *same context id string* set.
For example:
2020-01-01
Run
Open in xt-play
Note that it we only have docs from this fiddle.
2020-01-02
Run
Open in xt-play
Note that now we have the transactions from the previous fiddle :)
This fiddle uses a different context id, so it will not use the context of previous fiddles:
2020-01-02
Run
Open in xt-play
## Templated Queries
[Section titled “Templated Queries”](#templated-queries)
Having a full editor and asking a user to change it can be a lot. Instead you can use a query template:
Open in xt-play
3
Query templates use [mustache](https://mustache.github.io/) templates.
Use [Inputs](#inputs) to set the state used to render the template.
It usually makes sense to set the `autoLoad` property when you have a query template.
## Inputs
[Section titled “Inputs”](#inputs)
Inputs set variables in the template using their `name` property.
Open in xt-play
Limit:
\[x] 3
See [Available Inputs](#available-inputs) for a showcase.
## Outputs
[Section titled “Outputs”](#outputs)
By default, if no outputs are added a [table output](#table-output) is automatically appended to the fiddle.
You can override this by adding your own:
Open in xt-play
0
You can also have multiple if you want:
Open in xt-play
0
See [Available Outputs](#available-outputs) for a showcase.
## Caveats
[Section titled “Caveats”](#caveats)
Please note that the fiddle expects **exactly one** query:
Run
Open in xt-play
Run
Open in xt-play
The query is always run last:
Run
Open in xt-play
## Styling Tips
[Section titled “Styling Tips”](#styling-tips)
As you’ll have seen in the examples above, you can use tailwind to style the inputs.
This is handy for:
Open in xt-play
Putting a label beside an input:
My checkbox:
\[x]
***
Styling the input itself:
3
***
Organising inputs:
Search:
\[x]
## Available Inputs
[Section titled “Available Inputs”](#available-inputs)
### Checkbox
[Section titled “Checkbox”](#checkbox)
A wrapper around the [checkbox input](https://developer.mozilla.org/en-US/docs/Web/HTML/Element/input/checkbox).
Open in xt-play
\[x]
### Range
[Section titled “Range”](#range)
You can provide a `min`, `max`, `step` and `value` to specify a range. Can be a float or integer.
Open in xt-play
0
### DateRange
[Section titled “DateRange”](#daterange)
A customised range input specifically for outputting dates with two varieties:
You can provide a `start`, `stop` and `step` amount to have a full range of dates:
Open in xt-play
3
Or you can provide an array of dates:
Open in xt-play
2
### Text
[Section titled “Text”](#text)
A textbox element that allows the user to type in whatever they like:
Open in xt-play
Toy
## Available Outputs
[Section titled “Available Outputs”](#available-outputs)
### Table
[Section titled “Table”](#table)
The same table used in the Xtplay. Added by default if no output is provided.
Open in xt-play
0
### Vega
[Section titled “Vega”](#vega)
Displays a vega chart. You can specify a chart spec using the `spec` arg.
Data is provided through a dataset named `table`.
Open in xt-play
0
# Clojure SQL Cookbook
SQL queries are submitted through `xtdb.api/q`:
* `(xt/q ?)` returns the query results as a vector of maps.
* `opts`: map of query options
* `:args`: vector of query arguments
* `:snapshot-token`, `:current-time`, `:tx-timeout` : see [XTQL](/reference/main/xtql/queries#basis)
* `(xt/q& ?)`: returns a `CompletableFuture` of the query results.
For example:
```clojure
(xt/q node "SELECT u.first_name, u.last_name FROM users u WHERE _id = ?"
{:args ["James"]})
```
## SQL Transactions
[Section titled “SQL Transactions”](#sql-transactions)
SQL transactions are submitted through `xtdb.api/execute-tx` and `xtdb.api/submit-tx`.
* `(xt/submit-tx ?)`: returns the transaction key of the submitted transaction.
* `tx-ops`: vector of [transaction operations](#tx-ops).
* `opts` (map):
* `:default-tz` (`java.time.ZoneRegion`): time zone to be used by default in functions where no explicit override is provided. Defaults to the current TZ of the server JVM.
* `(xt/execute-tx ?)` : additionally awaits for the transaction to be processed, and throws if the transaction fails (either through error, or assertion failure).
SQL transaction operations are of the form `[:sql ""]`.
e.g.
```clojure
(require '[xtdb.api :as xt])
(xt/execute-tx node [[:sql "INSERT INTO users (_id, name) VALUES ('jms', 'James')"]
;; with args - pass multiple vectors if required.
[:sql "INSERT INTO users (_id, name) VALUES (?, ?)"
["jms", "James"]
["jdt", "Jeremy"]]])
;; => {:tx-id 0, :system-time #xt/instant "...", :committed? true}
```
Note
There is a table and column name mapping between SQL and XTQL: documents inserted with XTQL have their hyphens translated to underscores, and their namespace segments converted to `$` symbols, as hyphens, periods and slashes are not valid symbols in SQL identifiers.
For example, `:foo.bar/baz-quux` in XTQL is referenced in SQL as `foo$bar$baz_quux`.
The built-in XTDB columns `:xt/id`, `:xt/valid-from`, `:xt/valid-to` etc are referenced in SQL as `_id`, `_valid_from` and `_valid_to` respectively.
This mapping is reversed when querying SQL documents from XTQL.
For more details on XTDB’s SQL support, see the [SQL reference documentation](/reference/main/sql/queries).
# XTDB community
XTDB is fundamentally free-to-use and open-source (under the [MPL license](https://opensource.org/license/mpl-2-0/)).
For your peace of mind, though, XTDB is the flagship product of [JUXT](https://juxt.pro) - a widely-respected software consultancy who have been building high-quality, scalable and resilient software for some of the world’s largest (and smallest!) companies for over ten years.
JUXT additionally provide [enterprise XTDB support](https://xtdb.com/support) for companies looking to adopt or extend their usage of XTDB - including training, consultancy and production support.
## Open-source community
[Section titled “Open-source community”](#open-source-community)
XTDB has an active open-source community on the [XTDB GitHub repo](https://github.com/xtdb/xtdb), for:
* issues and pull requests
* [discussions](https://github.com/orgs/xtdb/discussions),
* [public roadmap](https://github.com/orgs/xtdb/projects/13/views/16),
as well as the source-code itself.
You can get in touch with the XTDB team (privately) regarding any of the above at .
# Installation via Docker
## Try Online
[Section titled “Try Online”](#try-online)
If you want to avoid running your own XTDB server locally, you can instantly play with inserting data and querying right now using the [XTDB Play](https://play.xtdb.com/) web-based console. The interactive [SQL Quickstart](/quickstart/sql-overview.html) uses this console to showcase XTDB’s SQL dialect and bitemporal capabilities.
Otherwise, let’s get XTDB downloaded and running on your own machine…
## Docker Install
[Section titled “Docker Install”](#docker-install)
XTDB supports production usage via the Postgres wire protocol so that you can work with various Postgres-compatible tools, drivers etc.
You can start a ‘standalone’ (i.e. non-production, non-distributed) XTDB server using the following command:
```bash
## see https://github.com/xtdb/xtdb/pkgs/container/xtdb/versions for tags
## `latest`: latest tagged release
## `nightly`: built every night from `main` branch
## `edge`: latest nightly plus urgent fixes
docker run -it --pull=always \
-p 5432:5432 \
-p 8080:8080 \
ghcr.io/xtdb/xtdb
## 5432: Postgres wire-compatible server (primary API)
## 8080: Monitoring/healthz HTTP endpoints
```
This command starts a Postgres wire-compatible endpoint on port 5432.
By default your data will only be stored temporarily using a local directory within the Docker container.
### (Optional) Mount a host directory
[Section titled “(Optional) Mount a host directory”](#optional-mount-a-host-directory)
You can attach a host volume to preserve your data across container restarts, e.g. by adding `-v /tmp/xtdb-data-dir:/var/lib/xtdb`, however because the XTDB container runs as a non-root user by default (UID 20000), you must ensure the container can write to it:
* For Docker, before running the container:
```bash
sudo chown -R 20000:20000 /tmp/xtdb-data-dir
```
* For Podman, ensure the directory is owned by your user and use `--userns=keep-id`, e.g.:
```bash
podman run -it --pull=always \
--userns=keep-id \
-p 5432:5432 \
-p 8080:8080 \
-v /tmp/xtdb-data-dir:/var/lib/xtdb \
ghcr.io/xtdb/xtdb
```
## Wait for XTDB to start
[Section titled “Wait for XTDB to start”](#wait-for-xtdb-to-start)
After seeing a ‘Node started’ log message (e.g. `09:00:00 | INFO xtdb.cli | Node started`) you are able to confirm your XTDB server is running using cURL:
```bash
curl http://localhost:8080/healthz/alive
## Alive.
```
## Connect with `psql`
[Section titled “Connect with psql”](#connect-with-psql)
```bash
## if you have Postgres installed, psql is already available
psql -h localhost -U xtdb xtdb
```
## Run your first query
[Section titled “Run your first query”](#run-your-first-query)
```plaintext
psql (16.2, server 16)
Type "help" for help.
user=> SELECT 'foo' AS bar;
bar
-----
foo
(1 row)
```
Next up:
* if you haven’t already run through the Quickstart already, you probably want to start there with inserting data, running your first queries, and learning about XTDB’s novel capabilities: [let’s INSERT some data](/quickstart/sql-overview)!
* to connect to XTDB from your language/tool of choice, have a look at XTDB’s [driver support](/drivers).
# AWS
Changelog (last updated v2.2)
* v2.2: Kafka replica log topic
The `xtdb-aws` Docker image and Helm chart now expose the replica log topic alongside the source log topic, to support [single-writer indexing](/about/dbs-in-xtdb#database-architecture).
Previously, only `XTDB_LOG_TOPIC` / `xtdbConfig.kafkaLogTopic` existed; a database used a single Kafka topic.
Upgrading:
* **Docker image** — `XTDB_REPLICA_LOG_TOPIC` defaults to `xtdb-log-replica` via the Dockerfile. If you customise `XTDB_LOG_TOPIC`, override this env var too so the pair stays consistent.
* **Helm chart** — `xtdbConfig.kafkaReplicaLogTopic` defaults to `xtdb-log-replica` and auto-creates alongside the source topic. Existing deployments pick this up on next rollout without any values changes.
* **Deployment isolation** — `xtdbConfig.kafkaTransactionalIdPrefix` is gone, along with the Kafka transactions it configured. Deployments sharing a Kafka cluster are now separated by consumer group instead: set a distinct `groupId` on the `!Kafka` cluster entry in `xtdbConfig.nodeConfig`.
XTDB provides modular support for AWS environments, including a pre-built Docker image, integrations for **S3 storage** and **CloudWatch metrics**, and configuration options for deploying onto AWS infrastructure.
Note
For more information on setting up an XTDB cluster on AWS, see the [“Getting Started with AWS”](guides/starting-with-aws) guide.
## Required infrastructure
[Section titled “Required infrastructure”](#required-infrastructure)
In order to run an AWS based XTDB cluster, the following infrastructure is required:
* An **S3 bucket** for remote storage.
* A **Kafka cluster** for the message log.
* For more information on setting up Kafka for usage with XTDB, see the [Kafka configuration](config/log/kafka) docs.
* IAM policies which grant XTDB permission to the S3 bucket
* XTDB nodes configured to communicate with the Kafka cluster and S3 bucket.
## Terraform Templates
[Section titled “Terraform Templates”](#terraform-templates)
To set up a basic version of the required infrastructure, we provide a set of Terraform templates specifically designed for AWS.
These can be fetched from the XTDB repository using the following command:
```bash
terraform init -from-module github.com/xtdb/xtdb.git//aws/terraform
```
### Resources
[Section titled “Resources”](#resources)
By default, running the templates will deploy the following infrastructure:
* Amazon S3 Storage Bucket for remote storage.
* Configured with associated resources using the [**terraform-aws-modules/s3-bucket**](https://registry.terraform.io/modules/terraform-aws-modules/s3-bucket/aws/latest) Terraform module.
* Enables object ownership control and applies necessary permissions for XTDB.
* IAM Policy for granting access to the S3 storage bucket.
* Configured with associated resources using the [**terraform-aws-modules/iam-policy**](https://registry.terraform.io/modules/terraform-aws-modules/iam/aws/latest/submodules/iam-policy) Terraform module.
* Grants permissions for XTDB to read, write, and manage objects within the specified S3 bucket.
* Virtual Private Cloud (VPC) for the XTDB EKS cluster.
* Configured with associated resources using the [**terraform-aws-modules/vpc**](https://registry.terraform.io/modules/terraform-aws-modules/vpc/aws/latest) Terraform module.
* Enables DNS resolution, assigns public subnets, and configures networking for the cluster.
* Amazon Elastic Kubernetes Service (EKS) Cluster for running XTDB resources.
* Configured with associated resources using the [**terraform-aws-modules/eks**](https://registry.terraform.io/modules/terraform-aws-modules/eks/aws/latest) Terraform module.
* Provisions a managed node group dedicated to XTDB workloads.
### Configuration
[Section titled “Configuration”](#configuration)
In order to customize the deployment, we provide a number of pre-defined variables within the `terraform.tfvars` file. These variables can be modified to tailor the infrastructure to your specific needs.
The following variables are **required** to be set:
* `s3_bucket_name`: The (globally unique) name of the S3 bucket used by XTDB.
For more advanced usage, the Terraform templates themselves can be modified to suit your specific requirements.
### Outputs
[Section titled “Outputs”](#outputs)
The Terraform templates will return several outputs:
| Output | Description |
| ---------------------- | -------------------------------------------------------------------- |
| `aws_region` | The AWS region in which the resources were created. |
| `eks_cluster_name` | The name of the EKS cluster created for the XTDB deployment. |
| `s3_bucket_name` | The name of the S3 bucket created for the XTDB cluster. |
| `s3_access_policy_arn` | The ARN of the S3 bucket created for the XTDB cluster. |
| `oidc_provider` | OpenID Connect identity provider for the EKS cluster. |
| `oidc_provider_arn` | The ARN of the OpenID Connect identity provider for the EKS cluster. |
## `xtdb-aws` Helm Charts
[Section titled “xtdb-aws Helm Charts”](#xtdb-aws-helm-charts)
For setting up a production-ready XTDB cluster on AWS, we provide a **Helm** chart built specifically for AWS environments.
### Pre-requisites
[Section titled “Pre-requisites”](#pre-requisites)
To allow the XTDB nodes to access AWS resources, a Kubernetes Service Account (KSA) must be setup and linked with an IAM role that has any necessary permissions, using [**IAM Roles for Service Accounts (IRSA)**](https://docs.aws.amazon.com/eks/latest/userguide/iam-roles-for-service-accounts.html).
#### Setting Up the Kubernetes Service Account:
[Section titled “Setting Up the Kubernetes Service Account:”](#setting-up-the-kubernetes-service-account)
Create the Kubernetes Service Account in the target namespace:
```bash
kubectl create serviceaccount xtdb-service-account --namespace xtdb-deployment
```
#### Setting up the IAM Service Account
[Section titled “Setting up the IAM Service Account”](#setting-up-the-iam-service-account)
Fetch the ARN of a policy granting access to s3 (`s3_access_policy_arn`), the OpenID Connect identity provider of the EKS cluster (`oidc_provider`) and ARN for the OIDC provider (`oidc_provider_arn`).
Create a file `eks_policy_document.json` for the trust policy, replacing values as appropriate:
```json
{
"Version": "2012-10-17",
"Statement": [
{
"Effect": "Allow",
"Principal": {
"Federated": ""
},
"Action": "sts:AssumeRoleWithWebIdentity",
"Condition": {
"StringEquals": {
":aud": "sts.amazonaws.com",
":sub": "system:serviceaccount:xtdb-deployment:xtdb-service-account"
}
}
}
]
}
```
Create the IAM role and attach the trust policy created above:
```bash
aws iam create-role --role-name xtdb-eks-role --assume-role-policy-document file://eks_policy_document.json --description "XTDB EKS Role"
```
Attach the S3 bucket role:
```bash
aws iam attach-role-policy --role-name xtdb-eks-role --policy-arn=
```
#### Annotating the Kubernetes Service Account
[Section titled “Annotating the Kubernetes Service Account”](#annotating-the-kubernetes-service-account)
Fetch the ARN of the IAM role:
```bash
xtdb_eks_role_arn=$(aws iam get-role --role-name xtdb-eks-role --query Role.Arn --output text)
```
Annotate the Kubernetes Service Account with the IAM role to establish the link between the two:
```bash
kubectl annotate serviceaccount xtdb-service-account --namespace xtdb-deployment eks.amazonaws.com/role-arn=$xtdb_eks_role_arn
```
### Installation
[Section titled “Installation”](#installation)
The Helm chart can be installed directly from the [**Github Container Registry** releases](https://github.com/xtdb/xtdb/pkgs/container/helm-xtdb-aws).
This will use the default configuration for the deployment, setting any required values as needed:
```bash
helm install xtdb-aws oci://ghcr.io/xtdb/helm-xtdb-aws \
--version 2.0.0-snapshot \
--namespace xtdb-deployment \
--set xtdbConfig.serviceAccount="xtdb-service-account" \
--set xtdbConfig.s3Bucket=
```
We provide a number of parameters for configuring numerous parts of the deployment, see the [`values.yaml` file](https://github.com/xtdb/xtdb/tree/main/aws/helm) or call `helm show values`:
```bash
helm show values oci://ghcr.io/xtdb/helm-xtdb-aws \
--version 2.0.0-snapshot
```
#### Kafka topics
[Section titled “Kafka topics”](#kafka-topics)
The chart uses one Kafka topic for each of the source and replica logs (v2.2+):
* `xtdbConfig.kafkaLogTopic` — source log topic (defaults to `xtdb-log`).
* `xtdbConfig.kafkaReplicaLogTopic` — replica log topic (defaults to `xtdb-log-replica`).
Both topics auto-create on startup.
If multiple XTDB deployments share a Kafka cluster, give each a distinct consumer group: set `groupId` on the `!Kafka` cluster entry in `xtdbConfig.nodeConfig` (defaults to `xtdb`). The chart exposes no dedicated value for it — see [Sharing a Kafka cluster across deployments](config/log/kafka#sharing-a-kafka-cluster-across-deployments).
### Resources
[Section titled “Resources”](#resources-1)
By default, the following resources are deployed by the Helm chart:
* A `ConfigMap` containing the XTDB YAML configuration.
* A `StatefulSet` containing a configurable number of XTDB nodes, using the [**xtdb-aws** docker image](#docker-image)
* A `LoadBalancer` Kubernetes service to expose the XTDB cluster to the internet.
### Pulling the Chart Locally
[Section titled “Pulling the Chart Locally”](#pulling-the-chart-locally)
The chart can also be pulled from the **Github Container Registry**, allowing further configuration of the templates within:
```bash
helm pull oci://ghcr.io/xtdb/helm-xtdb-aws \
--version 2.0.0-snapshot \
--untar
```
## `xtdb-aws` Docker Image
[Section titled “xtdb-aws Docker Image”](#xtdb-aws-docker-image)
The [**xtdb-aws**](https://github.com/xtdb/xtdb/pkgs/container/xtdb-aws) image is optimized for running XTDB in AWS environments, and is deployed on every release to XTDB.
By default, it will use **S3** for storage and **Kafka** for the message log, including dependencies for both.
### Configuration
[Section titled “Configuration”](#configuration-1)
The following environment variables are used to configure the `xtdb-aws` image:
| Variable | Description |
| ------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `KAFKA_BOOTSTRAP_SERVERS` | Kafka bootstrap server containing the XTDB topics. |
| `XTDB_LOG_TOPIC` | Kafka topic used as the source log. |
| `XTDB_REPLICA_LOG_TOPIC` | (v2.2+) Kafka topic used as the replica log. Defaults to `xtdb-log-replica`. If you override `XTDB_LOG_TOPIC`, override this too to keep the pair consistent. |
| `XTDB_S3_BUCKET` | Name of the S3 bucket used for remote storage. |
| `XTDB_NODE_ID` | Persistent node id for labelling Prometheus metrics. |
You can also [set the XTDB log level](/ops/troubleshooting#loglevel) using environment variables.
### Using a Custom Node Configuration
[Section titled “Using a Custom Node Configuration”](#using-a-custom-node-configuration)
For advanced usage, XTDB allows the above YAML configuration to be overridden to customize the running node’s system/modules.
In order to override the default configuration:
1. Mount a custom YAML configuration file to the container.
2. Override the `COMMAND` of the docker container to use the custom configuration file, ie:
```bash
CMD ["-f", "/path/to/custom-config.yaml"]
```
## S3 Storage
[Section titled “S3 Storage”](#s3-storage)
[**Amazon S3**](https://aws.amazon.com/s3/) can be used as a shared object-store for XTDB’s [remote storage](config/storage#remote) module.
### Infrastructure Requirements
[Section titled “Infrastructure Requirements”](#infrastructure-requirements)
To use S3 as the object store, the following infrastructure is required:
1. An **S3 bucket**.
2. **IAM policies** which grant XTDB permission to the S3 bucket:
```yaml
Statement:
- Effect: Allow
Action:
- 's3:GetObject'
- 's3:PutObject'
- 's3:DeleteObject'
- 's3:ListBucket'
- 's3:AbortMultipartUpload'
- 's3:ListBucketMultipartUploads'
Resource:
- !Ref S3BucketArn
- !Join [ '', [ !Ref S3BucketArn, '/*'] ]
```
::: informalexample If you are using an S3 compatible object storage you might need to pass the environment variable `AWS_S3_FORCE_PATH_STYLE=true`, because alternative S3 solutions often still use the older S3 path style.
### Authentication
[Section titled “Authentication”](#authentication)
XTDB uses AWS SDK for Authentication, relying on the default AWS credential provider chain. See the [AWS documentation](https://docs.aws.amazon.com/sdk-for-java/latest/developer-guide/credentials-chain.html) for setup instructions.
Alternatively, you can authenticate with an explicit **access key** / **secret key** (v2.2+). Declare an `!S3` [remote](/ops/config#remotes) holding the credential, then reference it from the object store with `remote:`:
```yaml
remotes:
my-aws: !S3
accessKey: !Env AWS_ACCESS_KEY_ID
secretKey: !Env AWS_SECRET_ACCESS_KEY
storage: !Remote
objectStore: !S3
bucket: my-s3-bucket
remote: my-aws
```
The remote lives in node-local config and is referenced by alias, so the keys are never serialised onto the source log.
### Configuration
[Section titled “Configuration”](#configuration-2)
To use the S3 module, include the following in your node configuration:
```yaml
storage: !Remote
objectStore: !S3
## -- required
## The name of the S3 bucket to use for the object store
## (Can be set as an !Env value)
bucket: "my-s3-bucket"
## -- optional
## A file path to prefix all of your files with
## - for example, if "foo" is provided, all XTDB files will be located under a "foo" sub-directory
## (Can be set as an !Env value)
# prefix: my-xtdb-node
## Explicit credentials for AWS.
## If not provided, will default to AWS's standard credential resolution.
## see: https://docs.aws.amazon.com/sdk-for-java/latest/developer-guide/credentials-chain.html
## To supply keys explicitly, declare an !S3 remote and reference it with `remote:`
## (see Authentication above). The inline `credentials:` block below is deprecated
## because it serialises the keys onto the source log.
# remote: my-aws
# credentials: ## deprecated — use `remote:` instead
# accessKey: "..."
# secretKey: "..."
## Endpoint URI
## If not provided, will default to the standard S3 endpoint for the resolved region.
# endpoint: "https://..."
## -- required
## A local disk path where XTDB can cache files from the remote storage
diskCache:
path: /var/cache/xtdb/object-store
```
If configured as an in-process node, you can also specify an `S3Configurator` instance - this is used to modify the requests sent to S3.
## Protecting XTDB Data
[Section titled “Protecting XTDB Data”](#protecting-xtdb-data)
Amazon S3 provides [strong durability guarantees](https://docs.aws.amazon.com/AmazonS3/latest/userguide/DataDurability.html) (11 9s), but does not protect against operator error or access misconfiguration.
To minimize risk:
* Enable [S3 Versioning](https://docs.aws.amazon.com/AmazonS3/latest/userguide/Versioning.html) --- allows recovery of deleted or overwritten objects
* Will use delete markers or retention policies for soft delete
* Use [Cross-Region Replication](https://docs.aws.amazon.com/AmazonS3/latest/userguide/replication.html) for disaster recovery scenarios
* Apply S3 bucket lifecycle and retention policies with care
* Lock down IAM access to prevent destructive operations from untrusted sources
For shared guidance on storage backup strategies, see the [Backup Overview](/ops/backup-and-restore/overview).
## Backing Up XTDB Data
[Section titled “Backing Up XTDB Data”](#backing-up-xtdb-data)
XTDB storage files in S3 are immutable and ideally suited for snapshot-based backup strategies.
To perform a full backup:
* Back up the entire S3 prefix (or bucket) used by XTDB
* Ensure all files associated with the latest flushed block are present
* Avoid copying in-progress files --- only finalized storage files are valid for recovery
You can use [AWS Backup](https://docs.aws.amazon.com/aws-backup/latest/devguide/whatisbackup.html) for scheduled, versioning-aware backups of entire buckets.
## CloudWatch Monitoring
[Section titled “CloudWatch Monitoring”](#cloudwatch-monitoring)
XTDB supports reporting metrics to [**AWS Cloudwatch**](https://docs.aws.amazon.com/AmazonCloudWatch/latest/monitoring/WhatIsCloudWatch.html) for performance and health monitoring.
### Configuration
[Section titled “Configuration”](#configuration-3)
To report XTDB node metrics to CloudWatch, include the following in your node configuration:
```yaml
modules:
- !CloudWatch
```
Authentication is handled via the AWS SDK, using the default AWS credential provider chain. See the [AWS documentation](https://docs.aws.amazon.com/sdk-for-java/latest/developer-guide/credentials-chain.html) for setup instructions.
The associated credentials must have permissions to write metrics to a pre-configured `CloudWatch` namespace.
# Azure
Changelog (last updated v2.2)
* v2.2: Kafka replica log topic
The `xtdb-azure` Docker image and Helm chart now expose the replica log topic alongside the source log topic, to support [single-writer indexing](/about/dbs-in-xtdb#database-architecture).
Previously, only `XTDB_LOG_TOPIC` / `xtdbConfig.kafkaLogTopic` existed; a database used a single Kafka topic.
Upgrading:
* **Docker image** — `XTDB_REPLICA_LOG_TOPIC` defaults to `xtdb-log-replica` via the Dockerfile. If you customise `XTDB_LOG_TOPIC`, override this env var too so the pair stays consistent.
* **Helm chart** — `xtdbConfig.kafkaReplicaLogTopic` defaults to `xtdb-log-replica` and auto-creates alongside the source topic. Existing deployments pick this up on next rollout without any values changes.
* **Deployment isolation** — `xtdbConfig.kafkaTransactionalIdPrefix` is gone, along with the Kafka transactions it configured. Deployments sharing a Kafka cluster are now separated by consumer group instead: set a distinct `groupId` on the `!Kafka` cluster entry in `xtdbConfig.nodeConfig`.
XTDB provides modular support for Azure environments, including a prebuilt Docker image, integrations with **Azure Blob Storage**, **Application Insights monitoring** and configuration options for deploying onto Azure infrastructure.
Note
For more details on getting started with Azure, see the [“Getting Started with Azure”](guides/starting-with-azure) guide.
## Required infrastructure
[Section titled “Required infrastructure”](#required-infrastructure)
In order to run an Azure based XTDB cluster, the following infrastructure is required:
* An **Azure Storage Account**, containing a **Storage Account Container**.
* A **User Assigned Managed Identity** for authentication with Azure services.
* A **Kafka cluster** for the message log.
* For more information on setting up Kafka for usage with XTDB, see the [Kafka configuration](config/log/kafka) docs.
* XTDB nodes configured to communicate with the Kafka cluster and Azure Storage Account/Container.
* (On Kubernetes) A **Federated Identity Credential** setup for the desired Kubernetes Namespace/Service account to give access to the **User Assigned Managed Identity**.
## Terraform Templates
[Section titled “Terraform Templates”](#terraform-templates)
To set up a basic version of the required infrastructure, we provide a set of Terraform templates specifically designed for Azure.
These can be fetched from the XTDB repository using the following command:
```bash
terraform init -from-module github.com/xtdb/xtdb.git//azure/terraform
```
### Resources
[Section titled “Resources”](#resources)
By default, running the templates will deploy the following infrastructure:
* **XTDB Resource Group and User Assigned Managed Identity**
* **Azure Storage Account** (with a container for object storage)
* Configured with associated resources using the [**Azure/avm-res-storage-storageaccount**](https://registry.terraform.io/modules/Azure/avm-res-storage-storageaccount/azurerm/latest) Terraform module.
* Adds required permissions to the User Assigned Managed Identity.
* **AKS Cluster**
* Configured with associated resources using the [**Azure/aks**](https://registry.terraform.io/modules/Azure/aks/azurerm/latest) Terraform module.
### Configuration
[Section titled “Configuration”](#configuration)
In order to customize the deployment, we provide a number of pre-defined variables within the `terraform.tfvars` file. These variables can be modified to tailor the infrastructure to your specific needs.
The following variables are **required** to be set:
* `storage_account_name`: The (globally unique) name of the Azure storage account used by XTDB.
For more advanced usage, the Terraform templates themselves can be modified to suit your specific requirements.
## `xtdb-azure` Helm Charts
[Section titled “xtdb-azure Helm Charts”](#xtdb-azure-helm-charts)
For setting up a production-ready XTDB cluster on Azure, we provide a **Helm** chart built specifically for Azure environments.
### Pre-requisites
[Section titled “Pre-requisites”](#pre-requisites)
To enable XTDB nodes to access an Azure storage account securely, a Kubernetes Service Account (KSA) must be set up and linked to a User Assigned Managed Identity using [**Workload Identity Federation**](https://learn.microsoft.com/en-us/entra/workload-id/workload-identity-federation).
#### Setting Up the Kubernetes Service Account:
[Section titled “Setting Up the Kubernetes Service Account:”](#setting-up-the-kubernetes-service-account)
Create the Kubernetes Service Account in the target namespace:
```bash
kubectl create serviceaccount xtdb-service-account --namespace xtdb-deployment
```
#### Binding the IAM Service Account
[Section titled “Binding the IAM Service Account”](#binding-the-iam-service-account)
Fetch the name of the User Assigned Managed Identity (`user_assigned_managed_identity_name`) and the OIDC issuer URL of the AKS cluster (`oidc_issuer_url`). Create the federated identity using the `az` CLI:
```bash
az identity federated-credential create \
--name "xtdb-federated-identity" \
--resource-group "xtdb-resource-group" \
--subject "system:serviceaccount:xtdb-deployment:xtdb-service-account" \
--audience "api://AzureADTokenExchange" \
--identity-name "" \
--issuer ""
```
The subject name must include the namespace and Kubernetes ServiceAccount name.
#### Annotating the Kubernetes Service Account
[Section titled “Annotating the Kubernetes Service Account”](#annotating-the-kubernetes-service-account)
Fetch the client ID of the User Assigned Managed Identity (`user_assigned_managed_identity_client_id`). Annotate the Kubernetes Service Account to establish the link between the KSA and the User Assigned Managed Identity:
```bash
kubectl annotate serviceaccount xtdb-service-account \
--namespace xtdb-deployment \
azure.workload.identity/client-id=""
```
### Installation
[Section titled “Installation”](#installation)
The Helm chart can be installed directly from the [**Github Container Registry** releases](https://github.com/xtdb/xtdb/pkgs/container/helm-xtdb-azure).
This will use the default configuration for the deployment, setting any required values as needed:
```bash
helm install xtdb-azure oci://ghcr.io/xtdb/helm-xtdb-azure \
--version 2.0.0-snapshot \
--namespace xtdb-deployment \
--set xtdbConfig.serviceAccount="xtdb-service-account" \
--set xtdbConfig.storageContainerName= \
--set xtdbConfig.storageAccountName= \
--set xtdbConfig.userManagedIdentityClientId=
```
We provide a number of parameters for configuring numerous parts of the deployment, see the [`values.yaml` file](https://github.com/xtdb/xtdb/tree/main/azure/helm) or call `helm show values`:
```bash
helm show values oci://ghcr.io/xtdb/helm-xtdb-azure \
--version 2.0.0-snapshot
```
#### Kafka topics
[Section titled “Kafka topics”](#kafka-topics)
The chart uses one Kafka topic for each of the source and replica logs (v2.2+):
* `xtdbConfig.kafkaLogTopic` — source log topic (defaults to `xtdb-log`).
* `xtdbConfig.kafkaReplicaLogTopic` — replica log topic (defaults to `xtdb-log-replica`).
Both topics auto-create on startup.
If multiple XTDB deployments share a Kafka cluster, give each a distinct consumer group: set `groupId` on the `!Kafka` cluster entry in `xtdbConfig.nodeConfig` (defaults to `xtdb`). The chart exposes no dedicated value for it — see [Sharing a Kafka cluster across deployments](config/log/kafka#sharing-a-kafka-cluster-across-deployments).
### Resources
[Section titled “Resources”](#resources-1)
By default, the following resources are deployed by the Helm chart:
* A `ConfigMap` containing the XTDB YAML configuration.
* A `StatefulSet` containing a configurable number of XTDB nodes, using the [**xtdb-azure** docker image](#docker-image)
* A `LoadBalancer` Kubernetes service to expose the XTDB cluster to the internet.
### Pulling the Chart Locally
[Section titled “Pulling the Chart Locally”](#pulling-the-chart-locally)
The chart can also be pulled from the **Github Container Registry**, allowing further configuration of the templates within:
```bash
helm pull oci://ghcr.io/xtdb/helm-xtdb-azure \
--version 2.0.0-snapshot \
--untar
```
## `xtdb-azure` Docker Image
[Section titled “xtdb-azure Docker Image”](#xtdb-azure-docker-image)
The [**xtdb-azure**](https://github.com/xtdb/xtdb/pkgs/container/xtdb-azure) image is optimized for running XTDB in Azure environments, and is deployed on every release to XTDB.
By default, it will use Azure Blob Storage for object storage and Kafka for the message log, including dependencies for both.
### Configuration
[Section titled “Configuration”](#configuration-1)
The following environment variables configure the `xtdb-azure` image:
| Variable | Description |
| -------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `KAFKA_BOOTSTRAP_SERVERS` | Kafka bootstrap server containing the XTDB topics. |
| `XTDB_LOG_TOPIC` | Kafka topic used as the source log. |
| `XTDB_REPLICA_LOG_TOPIC` | (v2.2+) Kafka topic used as the replica log. Defaults to `xtdb-log-replica`. If you override `XTDB_LOG_TOPIC`, override this too to keep the pair consistent. |
| `XTDB_AZURE_STORAGE_ACCOUNT` | Name of the Azure Storage Account. |
| `XTDB_AZURE_STORAGE_CONTAINER` | Name of the Azure Storage Container. |
| `XTDB_AZURE_USER_MANAGED_IDENTITY_CLIENT_ID` | Azure Client ID for the User Assigned Managed Identity used for authentication. |
| `XTDB_LOCAL_DISK_CACHE` | Path to the local disk cache for object storage. |
| `XTDB_NODE_ID` | Persistent node id for labelling Prometheus metrics. |
You can also [set the XTDB log level](/ops/troubleshooting#loglevel) using environment variables.
### Using the “private auth” Configuration File
[Section titled “Using the “private auth” Configuration File”](#using-the-private-auth-configuration-file)
For setups requiring private/authenticated Kafka instances, we provide the “private auth” configuration file.
To switch from the default configuration above to the authenticated Kafka configuration, update the `COMMAND` of the docker container as follows:
```bash
CMD ["-f", "azure_config_private_auth.yaml"]
```
In addition to the standard environment variables, the following environment variables are required for private/authenticated Kafka.
| Variable | Description |
| ------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `KAFKA_SASL_MECHANISM` | SASL mechanism to use for Kafka authentication (e.g., `PLAIN`). |
| `KAFKA_SECURITY_PROTOCOL` | Security protocol for Kafka (e.g., `SASL_SSL`). |
| `KAFKA_SASL_JAAS_CONFIG` | JAAS configuration for Kafka SASL authentication, (e.g. `org.apache.kafka.common.security.plain.PlainLoginModule required username="user" password="password";`). |
| `XTDB_AZURE_STORAGE_ACCOUNT_ENDPOINT` | The full endpoint of the storage account which has the storage container. |
Note
We would **strongly** recommend users mount the `KAFKA_SASL_JAAS_CONFIG` env as a secret on the container.
### Using a Custom Node Configuration
[Section titled “Using a Custom Node Configuration”](#using-a-custom-node-configuration)
For advanced usage, XTDB allows the above YAML configuration to be overridden to customize the running node’s system/modules.
In order to override the default configuration:
1. Mount a custom YAML configuration file to the container.
2. Override the `COMMAND` of the docker container to use the custom configuration file, ie:
```bash
CMD ["-f", "/path/to/custom-config.yaml"]
```
## Azure Blob Storage
[Section titled “Azure Blob Storage”](#azure-blob-storage)
[**Azure Blob Storage**](https://azure.microsoft.com/en-gb/products/storage/blobs) can be used as a shared object-store for XTDB’s [remote storage](config/storage#remote) module.
### Infrastructure Requirements
[Section titled “Infrastructure Requirements”](#infrastructure-requirements)
To use Azure Blob Storage as the object store, the following infrastructure is required:
1. An **Azure Storage Account**, containing a **Storage Account Container**.
2. Appropriate **permissions** for the storage account:
```json
{
"permissions": [
{
"actions": [
"Microsoft.Storage/storageAccounts/blobServices/containers/write",
"Microsoft.Storage/storageAccounts/blobServices/containers/delete",
"Microsoft.Storage/storageAccounts/blobServices/containers/read"
],
"notActions": [],
"dataActions": [
"Microsoft.Storage/storageAccounts/blobServices/containers/blobs/read",
"Microsoft.Storage/storageAccounts/blobServices/containers/blobs/write",
"Microsoft.Storage/storageAccounts/blobServices/containers/blobs/delete",
"Microsoft.Storage/storageAccounts/blobServices/containers/blobs/add/action",
"Microsoft.Storage/storageAccounts/blobServices/containers/blobs/move/action"
],
"notDataActions": []
}
]
}
```
### Authentication
[Section titled “Authentication”](#authentication)
By default, XTDB authenticates using the Azure SDK’s `DefaultAzureCredential`, which supports multiple methods including Managed Identity. For more details, refer to the [Azure Documentation](https://learn.microsoft.com/en-us/java/api/com.azure.identity.defaultazurecredential?view=azure-java-stable).
Alternatively, you can authenticate with a **storage-account key** or **connection string** (v2.2+). Declare an `!AzureBlob` [remote](/ops/config#remotes) holding the credential, then reference it from the object store with `remote:`:
```yaml
remotes:
my-azure: !AzureBlob
# supply one of:
storageAccountKey: !Env AZURE_STORAGE_ACCOUNT_KEY
# connectionString: !Env AZURE_STORAGE_CONNECTION_STRING
storage: !Remote
objectStore: !Azure
storageAccount: storage-account
container: xtdb-container
remote: my-azure
```
### Configuration
[Section titled “Configuration”](#configuration-2)
To use the Azure module, include the following in your node configuration:
```yaml
storage: !Remote
objectStore: !Azure
# -- required
# --- At least one of storageAccount or storageAccountEndpoint is required
# The name of the storage account which has the storage container
# (Can be set as an !Env value)
storageAccount: storage-account
# The full endpoint of the storage account which has the storage container
# (Can be set as an !Env value)
# storageAccountEndpoint: https://storage-account.privatelink.blob.core.windows.net
# The name of the blob storage container to be used as the object store
# (Can be set as an !Env value)
container: xtdb-container
# -- optional
# A file path to prefix all of your files with
# - for example, if "foo" is provided, all XTDB files will be located under a "foo" sub-directory
# (Can be set as an !Env value)
# prefix: my-xtdb-node
#
# Azure Client ID of a User Assigned Managed Identity -
# required when using them for authentication to Azure Services ie, inside of an Azure App Container.
# (Can be set as an !Env value)
# userManagedIdentityClientId: user-managed-identity-client-id
## -- required
## A local disk path where XTDB can cache files from the remote storage
diskCache:
path: /var/cache/xtdb/object-store
```
## Protecting XTDB Data
[Section titled “Protecting XTDB Data”](#protecting-xtdb-data)
Azure Blob Storage provides [strong durability guarantees](https://learn.microsoft.com/en-us/azure/storage/common/storage-redundancy#durability-and-availability-parameters) (up to 16 9s for GRS), but does not protect against operator error or access misconfiguration.
To minimize risk:
* Enable [Blob Versioning](https://learn.microsoft.com/en-us/azure/storage/blobs/versioning-overview) --- allows recovery of deleted or overwritten blobs
* Enable [Soft Delete](https://learn.microsoft.com/en-us/azure/storage/blobs/soft-delete-container-overview) --- allows recovery of deleted blobs or containers for a configured retention period
* Use [Geo- or Zone-Redundant Storage](https://learn.microsoft.com/en-us/azure/storage/common/storage-redundancy) for disaster recovery scenarios
* Apply lifecycle and retention policies with care
* Restrict blob/container access using role-based access control (RBAC) and scoped IAM roles
For shared guidance on storage backup strategies, see the [Backup Overview](/ops/backup-and-restore/overview).
## Backing Up XTDB Data
[Section titled “Backing Up XTDB Data”](#backing-up-xtdb-data)
XTDB storage files in Azure Blob Storage are immutable and ideally suited for snapshot-based backup strategies.
To perform a full backup:
* Back up the entire blob container (or prefix) used by XTDB
* Ensure all blobs associated with the latest flushed block are present
* Avoid copying in-progress blobs --- only finalized storage blobs are valid for recovery
You can use [Azure Backup](https://learn.microsoft.com/en-us/azure/backup/backup-overview) for scheduled, versioning-aware backups of storage containers.
## Application Insights Monitoring
[Section titled “Application Insights Monitoring”](#application-insights-monitoring)
XTDB supports reporting metrics to [Azure Application Insights](https://learn.microsoft.com/en-us/azure/azure-monitor/app/app-insights-overview) for performance and health monitoring.
### Configuration
[Section titled “Configuration”](#configuration-3)
To enable Application Insights monitoring, include the following in your node configuration:
```yaml
modules:
- !AzureMonitor
# -- required
connectionString: !Env XTDB_AZURE_APP_INSIGHTS_CONNECTION_STRING
```
# Scenario - Out of Sync Log & Intact Storage
If the transaction log is unexpectedly out of sync --- for example, due to topic deletion, rotation, or truncation --- but the indexed storage still exists, XTDB will refuse to start. This is a safety mechanism designed to prevent divergence between the transaction log and the object store.
You may encounter an error such as:
> “**Database ‘xtdb’ failed to start due to an invalid transaction log state (epoch=0, offset=200) that does not correspond with the latest processed message (epoch=0 and offset=289).**”
or:
> “**Database ‘xtdb’ failed to start due to an invalid transaction log state (the log is empty) that does not correspond with the latest processed message (epoch=0 and offset=289).**”
## What Is Preserved
[Section titled “What Is Preserved”](#what-is-preserved)
If storage remains intact, all previously indexed data is still available:
* Full queryable state up to the last successfully indexed transaction
## What Is Lost
[Section titled “What Is Lost”](#what-is-lost)
Any recently submitted transactions that were not indexed --- whether due to being lost, truncated, or deleted from the log --- are **unrecoverable** unless they were separately backed up.
## Recovery Strategy: Using Epochs
[Section titled “Recovery Strategy: Using Epochs”](#recovery-strategy-using-epochs)
XTDB provides a mechanism called an `epoch` to reset the transaction log tracking and allow recovery.
For full details about epochs, see [Epochs](/ops/config/log#epochs).
### Recovery Steps
[Section titled “Recovery Steps”](#recovery-steps)
1. **Shut down all XTDB nodes** Before making any changes, ensure all cluster nodes are stopped to avoid inconsistencies.
2. **Determine the current epoch value** Refer to the startup error message for the current epoch --- typically `0` for a fresh installation.
3. **Choose a new `epoch` value** Select an integer greater than the previous epoch --- usually `epoch + 1`.
4. **(Optional) Prepare a clean log state** If the log backend is not already empty, you need to create a new topic / directory for the log. Ensure the log backend (e.g., Kafka, local disk) is writable and correctly initialized before restarting.
5. **Update the node configuration** Set the new `epoch` value in your node’s log configuration. See [Epoch Configuration](/ops/config/log#epoch-configuration).
6. **Restart all nodes together** Once all configurations are updated, restart the cluster nodes at the same time. XTDB will skip offset validation and begin writing to the log under the new epoch.
7. **(Optional) Re-submit any lost transactions** If you are aware of any missing transactions, manually reissue them or restore them via your application’s recovery layer.
## Notes & Warnings
[Section titled “Notes & Warnings”](#notes--warnings)
* Beginning a new epoch will make the recovery of unindexed transactions from any previous epoch nearly impossible.
* Therefore, it is recommended to *only* increment the epoch after you are confident that the original log is irrecoverable and you understand the potential consequences.
* Always take a backup of storage before making epoch changes.
* The new epoch marks a clean slate for the log but does **not** delete any existing storage files.
* All nodes must use the same epoch value.
* Epochs only move forwards. A node whose log is at an earlier epoch than its indexed storage will fail to start with the error above, naming both epochs. Choosing an epoch *lower* than the current one is not a way to undo a bump: restore the storage backup that matches the log instead.
# Backup and Restore
This document provides a high-level overview of XTDB’s stateful architecture and outlines what data is stored where, what typical backups include, and how to think about restoring XTDB in different failure scenarios.
## Overview of Stateful Components
[Section titled “Overview of Stateful Components”](#overview-of-stateful-components)
XTDB consists of two primary stateful components:
### Log
[Section titled “Log”](#log)
The log contains the record of all submitted transactions and inter-node messages.
* The log is structured as a totally ordered, append-only sequence of entries.
* Each transaction is recorded immutably and assigned a durable log offset.
* The log guarantees ACID-compliant, serial execution of all writes across the cluster.
From a backup perspective, the log is the source of truth for all changes made to the database. Losing log entries that have not yet been indexed into storage risks permanent data loss.
For more information on the available implementations of the transaction log, see the [Log](/ops/config/log) docs.
### Storage Module
[Section titled “Storage Module”](#storage-module)
The storage module contains the database’s state: tables, indexes, and supporting metadata.
* Storage consists of immutable, append-only files.
* Each file represents a snapshot of the database’s state at a specific point in the transaction log.
From a backup perspective, storage files can be treated as **immutable snapshots** aligned with specific log offsets, making them well-suited to incremental or full backup strategies.
For more information on available storage backends and configuration, see the [Storage Module](/ops/config/storage) docs.
## What Data Is at Risk?
[Section titled “What Data Is at Risk?”](#what-data-is-at-risk)
| Component | Risk if Lost |
| ------------------ | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Log | All transactions on the log since the last indexed offset would be lost. |
| Storage Module | Without a backup or infinite retention on the log, all indexed data would be lost. |
| XTDB compute nodes | Only transient, in-memory cache state would be lost. All critical data is durably recorded in the log and storage module. Compute nodes can be restarted or replaced without risking data loss. |
## Backup Goals
[Section titled “Backup Goals”](#backup-goals)
Backup strategies in XTDB support multiple operational and business objectives:
* **Disaster recovery** --- restoring service after infrastructure or cloud failures
* **Point-in-time recovery of the individual storage components** - reverting storage components to a previous known good state
* **Environment migration** --- moving data between clusters, regions, or cloud providers
The specific backup approach should be chosen based on the criticality of the data, recovery time objectives (RTO), and regulatory requirements.
## What To Back Up?
[Section titled “What To Back Up?”](#what-to-back-up)
For most deployments, backing up the **storage module** is essential. It represents the finalized state of the database and enables full restoration without relying on the log.
Backing up the **log** is optional and may be used in conjunction with other strategies (e.g. application-level replay of transactions).
## Backing Up the Storage Module
[Section titled “Backing Up the Storage Module”](#backing-up-the-storage-module)
XTDB storage is composed of immutable files aligned with flushed log blocks, making it ideally suited for full snapshot-style backups.
### Safeguarding Object Store Data
[Section titled “Safeguarding Object Store Data”](#safeguarding-object-store-data)
While cloud object stores such as **S3**, **Azure Blob Storage**, and **Google Cloud Storage** offer strong durability, they do not protect against:
* Accidental or malicious deletion
* Misconfigured lifecycle policies or IAM roles
* Loss of access due to control-plane issues
To mitigate these risks:
* **Enable versioning** --- to recover deleted or overwritten files
* **Enable soft delete / retention policies** --- to guard against accidental loss
* **Use cross-region replication** --- for geo-resiliency and DR readiness
For provider-specific recommendations, see:
* [Protecting XTDB Data (AWS)](/ops/aws#protecting-data)
* [Protecting XTDB Data (Azure)](/ops/azure#protecting-data)
* [Protecting XTDB Data (GCP)](/ops/google-cloud#protecting-data)
### Taking Full Backups
[Section titled “Taking Full Backups”](#taking-full-backups)
XTDB storage files are written immutably and aligned with flushed blocks from the log. This makes them ideally suited to snapshot-based backup strategies.
To perform a full backup:
* Capture the full object store prefix or container used by XTDB
* Ensure all files associated with the latest indexed block are included
* Avoid partial or in-progress files --- only finalized files are valid for recovery
For platform-specific guidance, refer to:
* [Backing Up XTDB Data (AWS)](/ops/aws#backup)
* [Backing Up XTDB Data (Azure)](/ops/azure#backup)
* [Backing Up XTDB Data (GCP)](/ops/google-cloud#backup)
## Backing Up the Log
[Section titled “Backing Up the Log”](#backing-up-the-log)
While the storage module captures finalized state, the log may contain recent transactions that have not yet been indexed. If this data is lost before being written to storage, it cannot be recovered.
Backing up the log is optional, but may reduce your Recovery Point Objective (RPO) in the event of failure.
### Safeguarding Log Data
[Section titled “Safeguarding Log Data”](#safeguarding-log-data)
For advice on safeguarding the contents of the log, see implementation-specific guidance:
* [Kafka Log Durability](/ops/config/log/kafka#durability)
### Why Back Up the Log?
[Section titled “Why Back Up the Log?”](#why-back-up-the-log)
Backing up the log is not strictly required for all XTDB deployments. In many cases, a full recovery can be achieved using the storage module alone.
This is because XTDB periodically flushes indexed transactions from the log into immutable storage files. As a result, the storage module acts as a form of backup for the log --- capturing the system state at known log offsets.
Flush behavior is controlled by:
* A threshold number of transactions.
* A maximum time interval between flushes (this defaults to 15 minutes)
These settings define your effective **Recovery Point Objective (RPO)** --- that is, how much recent data you could lose in the event of log failure.
However, backing up the log provides additional benefits in environments with stricter recovery requirements:
* **Recover transactions submitted after the last flush** --- reduces data loss compared to storage-only restores
* **Avoid resetting the `epoch`** --- restoring the log preserves continuity, allowing nodes to recover without configuration changes
* **Faster point-in-time recovery** --- restoring log and storage together may reduce bootstrap time and operational complexity
### How to Back Up the Log
[Section titled “How to Back Up the Log”](#how-to-back-up-the-log)
Log protection can be achieved through:
* **Point-in-time backups** --- taken **after** a successful storage flush
* **Log replication** --- continuously replicating the log to another system or region
* **Application-level replay** --- rebuilding state from upstream message queues or events
Caution
When taking point-in-time backups - **always** back up the **storage module first**, then the log. Backing up the log before its associated storage state can result in a mismatch, as the restored log may refer to transactions not yet flushed to storage. In this case, XTDB will require a reset of the `epoch`, effectively discarding the restored log and falling back to the storage backup alone --- with a corresponding loss of recent transactions.
Additionally, ensure the delay between the storage and log backups does **not** exceed the retention period of your log implementation. If log messages are expired before the backup runs, they will be lost and cannot be restored.
For implementation-specific instructions, refer to:
* [Strategies for Kafka Log Backup](/ops/config/log/kafka#backup)
## Failure and Recovery Scenarios
[Section titled “Failure and Recovery Scenarios”](#failure-and-recovery-scenarios)
The following are common failure scenarios and links to detailed guidance for each:
* [**Transaction log is out of sync**](out-of-sync-log)
# Configuration
Changelog (last updated v2.2)
* v2.2: blocks are flushed every 15 minutes
A database too quiet to fill a block still writes one within 15 minutes — see [Indexer](#indexer).
Previously `indexer.flushDuration` defaulted to `PT4H`. That interval bounds how much recent data lives only in the log, how long a starting node spends replaying the tail behind the last block, how stale a reader pointed at another deployment’s storage can be, and — for an [external source](/ops/external-sources/overview) — how much upstream log its server has to retain. Four hours was a loose bound on all four.
No upgrade steps: config that sets `flushDuration` explicitly is honoured unchanged. Expect more, smaller blocks on quiet databases, and correspondingly more compaction work. A database busy enough to reach `rowsPerBlock` is unaffected — it cuts on row count long before the timer fires.
* v2.2: garbage collection is on by default
Superseded object-store files are reclaimed without any configuration — see [Garbage Collector](#garbage-collector).
Previously `garbageCollector.enabled` defaulted to `false`, so storage grew monotonically unless an operator opted in. Collection now runs on each database’s indexing leader at block boundaries, bounded by `blocksToKeep` and `garbageLifetime`.
No upgrade steps: existing config that sets `enabled` explicitly is still honoured, and a node started with GC enabled collects the backlog left by earlier versions.
* v2.2: `remotes` replaces `logClusters`
Named connections to external systems are now configured under [`remotes`](#remotes).
Previously these lived under `logClusters`, which was scoped to transaction-log clusters. `remotes` generalises it to any external connection — Kafka clusters, cloud identities, Postgres databases, etc.
`logClusters` is deprecated but still honoured: entries under both names are merged, so existing config keeps working — rename to `remotes` when convenient.
The pre-existing `!Kafka` can simply be moved under `remotes` with no other changes.
* v2.1: multi-database support
The log and storage configurations were changed as part of 2.1’s multi-db support.
For more details on those changes, see the [Transaction Logs](config/log) and [Object Storage](config/storage) documentation.
XTDB nodes are configured using YAML files.
All config options have default values, it is therefore valid to not specify a config file or not specify any part of the top-level config.
## Log & Storage
[Section titled “Log & Storage”](#log--storage)
The two main pluggable components of XTDB are [transaction logs](config/log) and [object storage](config/storage).
```yaml
## transaction log configuration
log: !Local
path: /path/to/log-file
## object store configuration
storage: !Local
path: /path/to/storage-dir
```
By default XTDB will use an [in-memory transaction log](config/log#in-memory) and an [in-memory object store](config/storage#in-memory).
## Monitoring & Observability
[Section titled “Monitoring & Observability”](#monitoring--observability)
XTDB provides a suite of tools & templates to facilitate [Monitoring & Observability](config/monitoring).
By default [healthz](config/monitoring#healthz-server), [monitoring](config/monitoring#metrics) & [tracing](config/monitoring#tracing) are disabled.
## Authentication
[Section titled “Authentication”](#authentication)
The Postgres wire-compatible server supports [authentication](config/authentication) which can be configured via authentication rules.
By default a [single root user](config/authentication#single-root-user-v22) named `xtdb` accepting any password is configured.
## Caching
[Section titled “Caching”](#caching)
XTDB has two caches for [object store](config/storage) data:
```yaml
# By default configured to use half the JVM's maximum direct memory
memoryCache:
# Maximum size of the cache, in bytes.
# Defaults to being calculated via `maxSizeRatio`
maxSizeBytes: 1073741824
# Maximum size of the cache, as a proportion of the JVM's maximum direct memory.
# Ignored when `maxSizeBytes` is set.
maxSizeRatio: 0.5 # default
# Required when using a remote object store, otherwise unused
# Defaults to being disabled
diskCache:
# Directory in which to store cached files. Required.
path: /path/to/disk-cache
# Maximum size of the cache, in bytes.
# Defaults to being calculated via `maxSizeRatio`
maxSizeBytes: 10737418240
# Maximum size of the cache, as a proportion of the filesystem's total space.
# Ignored when `maxSizeBytes` is set.
maxSizeRatio: 0.75 # default
```
## Remotes
[Section titled “Remotes”](#remotes)
`remotes` is a registry of named connections to the external systems XTDB authenticates against — Postgres instances, Kafka clusters, cloud identities (AWS/Azure/GCP), etc.
You define a connection once here under an alias, then reference it by that alias from the parts of the config that use it — the [transaction log](config/log), [object storage](config/storage), and external sources.
Each entry maps an alias to a connection. The tag (`!Postgres`, `!Kafka`, …) selects the remote type, and the available fields depend on that type:
```yaml
remotes:
my-kafka: !Kafka
bootstrapServers: "localhost:9092"
# ...then referenced by alias, e.g. by a Kafka transaction log:
log: !Kafka
cluster: my-kafka
topic: xtdb_topic
```
For the fields each remote type takes, and how a given component references its alias, see that component’s documentation — e.g. [transaction log](config/log), [object storage](config/storage).
## Troubleshooting configuration
[Section titled “Troubleshooting configuration”](#troubleshooting-configuration)
Config options to help an operator troubleshoot XTDB.
### Read-only Databases
[Section titled “Read-only Databases”](#read-only-databases)
Set all databases in the cluster to be in read-only mode.
By default set to false to have [databases](/about/dbs-in-xtdb) run in their configured modes.
```yaml
## Set to true to have *all* databases run in read-only mode
readOnlyDatabases: true
```
### Skip Databases
[Section titled “Skip Databases”](#skip-databases)
Set the configured databases as dormant (queriable but not accepting transactions).
By default an empty list or the result of splitting `!Env XTDB_SKIP_DBS` by `,`.
```yaml
skipDbs:
- my_db
- my_other_db
```
## Other configuration
[Section titled “Other configuration”](#other-configuration)
### Postgres wire-compatible server
[Section titled “Postgres wire-compatible server”](#postgres-wire-compatible-server)
By default read-write Postgres wire-compatible server is started on localhost:5432.
```yaml
server:
# Host on which to start a read-write Postgres wire-compatible server.
#
# Default is "localhost", which means the server will only accept connections on the loopback interface.
# Set to '*' to accept connections on all interfaces.
host: localhost
# Port on which to start a read-write Postgres wire-compatible server.
#
# Default is 0, to have the server choose an available port.
# (In the XTDB Docker images, this is defaulted to 5432.)
# Set to -1 to not start a read-write server.
port: 0
# Port on which to start a read-only Postgres wire-compatible server.
#
# The server on this port will reject any attempted DML/DDL,
# regardless of whether the user would otherwise have the permission to do so.
#
# Default is -1, to not start a read-only server.
# Set to 0 to have the server choose an available port.
readOnlyPort: -1
```
### Flight SQL Server
[Section titled “Flight SQL Server”](#flight-sql-server)
By default a Flight SQL server is started on localhost:9832.
```yaml
flightSql:
# Host on which to start the Flight SQL server.
#
# Default is "127.0.0.1", which means the server will only accept connections on the loopback interface.
# Set to '*' to accept connections on all interfaces.
host: 127.0.0.1
# Port on which to start the FLight SQL server.
#
# Default is 0, to have the server choose an available port.
# (In the XTDB Docker images, this is defaulted to 9832.)
# Set to -1 to not start a Flight SQL server.
port: 0
```
### Compactor
[Section titled “Compactor”](#compactor)
Defaults to running on roughly half the number of threads the system has processor cores.
```yaml
compactor:
# Number of threads to use for compaction.
# Defaults to !Env XTDB_COMPACTOR_THREADS # or if that's not specified min(availableProcessors / 2, 1).
# Set to 0 to disable the compactor.
threads: 4
```
### Indexer
[Section titled “Indexer”](#indexer)
Responsible for indexing transactions from the [transaction log](config/log).
Please consider reaching out at if you feel the need to change any of these!
```yaml
indexer:
# Set to false to disable indexing on the primary database (xtdb).
#
# Transactions are still accepted onto the log but are never processed,
# so synchronous submits will hang waiting for a result that never arrives.
# Submit with `async=true` to not hang.
enabled: true # default
# Number of operations the in-memory live-index buffers before reorganising them.
# Low-level tuning, most deployments leave this alone.
logLimit: 64 # default
# The maximum size of a page in the in-memory live-index.
# Low-level tuning, most deployments leave this alone.
pageLimit: 1024 # default
# Number of operations the in-memory live-index buffers before flushing to the object store.
# Low-level tuning, most deployments leave this alone.
rowsPerBlock: 102400 # default
# ISO-8601 duration after which the current block is finished even if it
# hasn't reached `rowsPerBlock`
flushDuration: PT15M # default
# Transaction ids to skip during indexing
# Useful to work around a transaction that crashes the indexer.
#
# Applies to *all* databases on the node.
#
# Defaults to the `XTDB_SKIP_TXS` environment variable (a comma-separated list
# of transaction ids, e.g. "12,15,16") if set, otherwise empty.
skipTxs: []
```
### Garbage Collector
[Section titled “Garbage Collector”](#garbage-collector)
Reclaims object-store space by deleting files left behind once compaction has superseded them.
Runs on each database’s indexing leader, at block boundaries.
```yaml
garbageCollector:
# Set to false to retain superseded files indefinitely
enabled: true # default
# Number of recent blocks to retain
blocksToKeep: 10 # default
# ISO-8601 duration for which superseded trie files are retained
garbageLifetime: PT24H # default
```
### Node ID
[Section titled “Node ID”](#node-id)
An identifier for the node. For example, used in [metrics](config/monitoring#metrics) and crash logging.
Defaults to `!Env XTDB_NODE_ID` otherwise is a short random string.
### Default TZ
[Section titled “Default TZ”](#default-tz)
Defaults to UTC.
## Ingest-only nodes (v2.2+)
[Section titled “Ingest-only nodes (v2.2+)”](#ingest-only-nodes-v22)
An ingest-only node runs [external sources](external-sources/overview) and nothing else.
It has no query surface - no Postgres wire-compatible server, no Flight SQL server - making it useful for moving ingestion onto dedicated compute, away from the nodes serving queries.
For each configured database, the node joins that database’s leader election and runs its external source when elected leader.
Started with the [`ingest` CLI command](#cli-toolsflags) — e.g. `docker run xtdb/xtdb ingest -f /config/xtdb.yaml`, or `args: ["ingest", "-f", "/config/xtdb.yaml"]` in Kubernetes — it takes its own top-level config file.
Each entry under `databases:` takes the same config as [`ATTACH DATABASE`](/about/dbs-in-xtdb#attachingdetaching-secondary-databases-v21) — `log`, `storage`, `externalSource`:
```yaml
remotes:
src_kafka: !Kafka
bootstrapServers: "localhost:9092"
# The databases to ingest into, keyed by name.
databases:
kc_orders:
log: !Kafka
cluster: src_kafka
topic: kc-orders-log
storage: !Remote
objectStore: !S3
bucket: my-bucket
prefix: kc-orders
externalSource: !KafkaConnect
remote: src_kafka
topic: orders
indexer: !Docs
table: orders
# Required when any database uses a remote object store
diskCache:
path: /var/cache/xtdb
# Serves /metrics and the liveness/readiness probes
healthz:
port: 8080
```
The config also accepts [`memoryCache`](#caching), [`indexer`](#indexer), [`healthz`](config/monitoring#healthz-server) and [node ID](#node-id), with the same semantics as the regular node config.
`xtdb` is reserved for the primary database and can’t be used as a database name here.
## Additional Concepts
[Section titled “Additional Concepts”](#additional-concepts)
### Using `!Env`
[Section titled “Using !Env”](#using-env)
For certain keys, we allow the use of environment variables - typically, the keys where we allow this are things that may change **location** across environments. Generally, they are either “paths” or “strings”.
When specifying a key, you can use the `!Env` tag to reference an environment variable. As an example:
```yaml
storage: !Local
path: !Env XTDB_STORAGE_PATH
```
Any key that we allow the use of `!Env` will be documented as such.
### CLI tools/flags
[Section titled “CLI tools/flags”](#cli-toolsflags)
Changelog (last updated v2.1)
* v2.1: top-level commands
In v2.1, we changed the CLI to use top-level commands (not dissimilar to Git, for example).
Previously, the playground and compact-only nodes were activated using optional flags - `--playground-port` and `--compact-only` respectively.
`reset-compactor` and `export-snapshot` were also added in v2.1.
You can run various tools by passing arguments - either directly to the CLI or via Docker’s arguments:
* `node` (default, can be omitted)
* `-f `, `--file `: specifies the configuration file to use.
* `playground`
Starts a playground - an in-memory server that will accept any database name, creating it if required.
* `-p `, `--port ` (default 5432): specifies the port to run the playground server on.
* `compactor`
Starts a compactor-only node - useful for giving the compaction process more compute resources.
* `-f `, `--file `: specifies the configuration file to use.
* `ingest` (v2.2+)
Starts an [ingest-only node](#ingest-only-nodes-v22) - runs the configured external sources, with no query surface.
* `-f `, `--file `: specifies the configuration file to use.
* `reset-compactor `
Resets the compaction back to L0, deleting any L1+ files - use this if you’ve encountered a compaction bug and need to reset its state.
1. Spin down all of your XT nodes
2. Using your container orchestration tool (e.g. Kubernetes), run a one-shot task with an overriden command: `["reset-compactor"]`. Optionally, specify `--dry-run` to list all of the files to be removed.
3. When the tool has finished, spin up your nodes again.
You may want to also spin up a compactor-only node to help out with the re-compaction.
At the moment, this can only reset all the way back to L0 - finer-grained reset will be added in a later release.
* `export-snapshot `
* `-f `, `--file `: specifies the configuration file to use.
This exports a snapshot of the object-store into a sibling directory within the object store. e.g. if your storage is at `s3://my-bucket/`, this will export to a directory under `s3://my-bucket/exports/...` - the exact directory will be given in the logs.
You can then start another node against this storage directory - you will need to start a new log, and increase the log epoch in your configuration:
```yaml
log: !Kafka
...
topic: new-topic
epoch: 1
storage: !Remote
objectStore: !S3
bucket: my-bucket
prefix: exports/...
```
* `read-arrow-file `
reads an Arrow file and emits it as EDN
* `read-arrow-stream-file `
reads an Arrow ‘stream IPC format’ file and emits it as EDN
e.g.
* Dockerfile: `CMD ["playground", "--port", "5439"]`
* docker-compose: `command: ["playground", "--port", "5439"]`
* Java uberjar: `java -jar xtdb.jar playground --port 5439`
* Clojure (with `xtdb-core` in your `deps.edn`): `clj -M xtdb.main playground --port 5439`
You can also pass `--help` to any of the commands to get command-specific help.
# Authentication
XTDB provides authentication to control database access and secure connections. Authentication rules determine which users can connect and what credentials they must provide.
## Authentication providers
[Section titled “Authentication providers”](#authentication-providers)
XTDB supports three authentication providers:
* **Single Root User** (`!SingleRootUser`, v2.2+): a single user (`xtdb`) whose password is configured at startup. This is the default.
* **User List** (`!UserList`, v2.2+): a fixed set of users with pre-hashed passwords, configured at startup.
* **OpenID Connect** (`!OpenIdConnect`): integrates with external identity providers like Keycloak, Auth0, AWS Cognito or Azure Entra.
## Single root user (v2.2+)
[Section titled “Single root user (v2.2+)”](#single-root-user-v22)
The `!SingleRootUser` method authenticates a single user named `xtdb` against a password that’s configured at startup.
The password is resolved at config-construction time:
1. The explicit `password` field on the YAML config (or Kotlin `SingleRootUser` value), if present.
2. Otherwise, the `XTDB_PASSWORD` environment variable, if set.
3. Otherwise, no password is configured.
If no password is configured, connections run under `TRUST` — no credentials required. If a password is configured, connections require `PASSWORD` authentication as the `xtdb` user. Any other username is rejected.
### Configuration
[Section titled “Configuration”](#configuration)
Resolve the password from `XTDB_PASSWORD` (the common case for containerised deployments):
```yaml
authn: !SingleRootUser
```
Or pass the password explicitly (discouraged for production — anyone with access to the config can read it):
```yaml
authn: !SingleRootUser
password: !Env XTDB_PASSWORD
```
```yaml
authn: !SingleRootUser
password: hunter2
```
## User list (v2.2+)
[Section titled “User list (v2.2+)”](#user-list-v22)
The `!UserList` method authenticates against a fixed set of users configured at startup. It suits simple deployments that want password authentication for more than one user without running an external identity provider.
The user set is static. It’s read from the configuration when the node starts, and the only way to change it is to edit the configuration and restart — there is no SQL or runtime API to add, alter, or remove users.
### Configuration
[Section titled “Configuration”](#configuration-1)
Each user maps to a pre-hashed password, tagged with the algorithm that produced it:
```yaml
authn: !UserList
users:
alice: !Argon2id "$argon2id$v=19$m=65536,t=3,p=1$c29tZXNhbHRzYWx0$RdescudvJCsgt3ub+b+dWRWJTmaaJObG"
bob: !BCrypt "$2y$12$mc.G6e7uChPgZW2NfY0XQOQ0qN6Q0o3Yv0bFv6kKQXmnq7nqQk0K"
rules:
# local connections are trusted
- remoteAddress: 127.0.0.1
method: TRUST
# everyone else must supply a password
- method: PASSWORD
```
If `rules` is omitted, every connection requires a password.
The configured users appear in the read-only `pg_user` view (with `passwd` redacted to `NULL`), so Postgres tooling that lists users sees them. `usesuper` is `true` only for a user named `xtdb` — the same superuser convention as `!SingleRootUser` — and `false` for everyone else.
### Hash algorithms
[Section titled “Hash algorithms”](#hash-algorithms)
Each password carries its own algorithm tag, so a node can hold a mix and you can move to a new algorithm without re-hashing the existing entries:
* `!Argon2id` — argon2id, the recommended default.
* `!BCrypt` — bcrypt, in standard modular-crypt (`$2…`) form.
### Hashing a password
[Section titled “Hashing a password”](#hashing-a-password)
Pre-hash passwords with the `hash-password` command and paste the output into the config:
```bash
xtdb hash-password [--argon2id | --bcrypt] 'my-password'
```
`--argon2id` is the current default; pass `--bcrypt` to use bcrypt instead. Omit the password argument to read it from stdin, which keeps the plaintext out of your shell history:
```bash
echo 'my-password' | xtdb hash-password
```
## OpenID Connect (OIDC)
[Section titled “OpenID Connect (OIDC)”](#openid-connect-oidc)
The `!OpenIdConnect` authentication method integrates with external identity providers like Keycloak, Auth0, AWS Cognito or Azure Entra.
### Basic Configuration
[Section titled “Basic Configuration”](#basic-configuration)
```yaml
authn: !OpenIdConnect
issuerUrl: https://your-keycloak.example.com/realms/master
clientId: xtdb-client
clientSecret: !Env OIDC_CLIENT_SECRET
rules:
- user: oidc-client
method: CLIENT_CREDENTIALS
- method: PASSWORD
```
For complete OIDC configuration, setup guides, and troubleshooting, see [OpenID Connect Authentication](authentication/oidc).
## Rule configuration
[Section titled “Rule configuration”](#rule-configuration)
`!UserList` and `!OpenIdConnect` control database access through authentication rules that match users and IP addresses to determine the required authentication method. `!SingleRootUser` doesn’t use rules — its method is determined by whether a password is configured.
### Authentication Rules
[Section titled “Authentication Rules”](#authentication-rules)
Authentication rules are evaluated in order until the first match. If no rules match, the connection is rejected.
* **Rule Parameters**
* `user` (optional): Match specific username
* `remoteAddress` (optional): Match IP address or CIDR block (IPv4 or IPv6)
* `method` (required): Authentication method to use
* **Available Methods**
* `TRUST`: No authentication required
* `PASSWORD`: Require username/password validation
* `CLIENT_CREDENTIALS`: OAuth client credentials flow (OIDC only)
* `DEVICE_AUTH`: OAuth device authorization flow (OIDC only)
* **Example Rule**
```yaml
- user: admin
remoteAddress: 127.0.0.1
method: PASSWORD
```
This rule requires the `admin` user to provide a password when connecting from `localhost`.
# OpenID Connect Authentication
XTDB integrates with OpenID Connect identity providers (Keycloak, Auth0, AWS Cognito, Azure Entra) for external authentication. OIDC authentication supports multiple OAuth 2.0 flows for different client types.
## Identity Provider Requirements
[Section titled “Identity Provider Requirements”](#identity-provider-requirements)
* **Required Capabilities**
* OpenID Connect Discovery (/.well-known/openid\_configuration)
* At least one of the following OAuth 2.0 grant types:
* Client Credentials flow (widely supported)
* Resource Owner Password Credentials flow (optional, provider-dependent)
* Device Authorization Grant flow (optional, provider-dependent)
* Token refresh capabilities (for flows that support it)
## Configuration
[Section titled “Configuration”](#configuration)
To use OpenID Connect authentication, include the following in your node configuration:
```yaml
authn: !OpenIdConnect
# -- required
# The OpenID Connect issuer URL for your identity provider.
# This is the base URL from which OIDC discovery will be performed
# (Can be set as an !Env value)
issuerUrl: https://your-keycloak.example.com/realms/master
# The client identifier registered with your identity provider.
# (Can be set as an !Env value)
clientId: xtdb-client
# The client secret for confidential clients.
# Should be stored as an environment variable for security.
# (Can be set as an !Env value)
clientSecret: !Env OIDC_CLIENT_SECRET
# Authentication rules determine which OAuth flow applies to each connection.
# Rules are evaluated in order until the first match.
# See the main Authentication page for complete rule syntax.
rules:
# Client credentials flow for service accounts
# When connecting, specify "oidc-client" as your username with colon-delimited password (client-id:client-secret)
- user: oidc-client
method: CLIENT_CREDENTIALS
# Device authorization flow
# When connecting, specify "oidc-device" as your username
- user: oidc-device
method: DEVICE_AUTH
# Default: password flow for interactive users
- method: PASSWORD
```
## Username Handling
[Section titled “Username Handling”](#username-handling)
The username provided in database connections serves different purposes depending on the authentication method:
* **PASSWORD Method**
The username is used both for rule matching AND for actual OIDC authentication with your identity provider.
* **CLIENT\_CREDENTIALS and DEVICE\_AUTH Methods**
The username is used ONLY for rule matching to determine which authentication method to apply. The actual username value is ignored during authentication.
* **Rule Filtering**
* If using only CLIENT\_CREDENTIALS or only DEVICE\_AUTH, you don’t need user-specific rules - you can use a catch-all rule with just `method: CLIENT_CREDENTIALS` or `method: DEVICE_AUTH`
* User filtering is needed when supporting multiple flows and you want to differentiate by the connection’s username
## Authentication Flows
[Section titled “Authentication Flows”](#authentication-flows)
Note
Not all OIDC providers support all OAuth 2.0 flows. PASSWORD and DEVICE\_AUTH flows require specific provider support and configuration. Check your provider’s documentation for supported grant types.
### CLIENT\_CREDENTIALS Method
[Section titled “CLIENT\_CREDENTIALS Method”](#client_credentials-method)
Uses OAuth Client Credentials flow for service accounts and automated processes.
* **Connection Details**
* **Username**: Must match the `user` value in your CLIENT\_CREDENTIALS rule (e.g., `oidc-client` in the example above)
* **Password**: `client-id:client-secret` (colon-delimited)
* **Client Usage Example**
```bash
## Using the username from your configuration rule
PGPASSWORD="your-client-id:your-client-secret" psql -h localhost -p 5432 -U oidc-client -d xtdb
```
### PASSWORD Method
[Section titled “PASSWORD Method”](#password-method)
Uses OAuth Resource Owner Password Credentials flow for interactive users.
* **Client Usage**
```bash
psql -h localhost -p 5432 -U username -d xtdb
## Enter OIDC password when prompted
```
### DEVICE\_AUTH Method
[Section titled “DEVICE\_AUTH Method”](#device_auth-method)
Uses OAuth Device Authorization flow for applications that cannot securely store secrets.
* **Connection Details**
* **Username**: Must match the `user` value in your DEVICE\_AUTH rule (e.g., `oidc-device` in the example above)
* **Flow Process**
1\. Client requests device code from XTDB
2. User visits verification URL and enters user code
3. XTDB polls identity provider until user completes authentication
4. Access token issued upon successful authentication
* **Client Usage Example**
```bash
## Using the username from your configuration rule
psql -h localhost -p 5432 -U oidc-device -d xtdb
## Follow device authorization flow prompts
```
## Token Management
[Section titled “Token Management”](#token-management)
* **Validation**
Tokens are validated before query and data operations. Connections terminate if validation fails.
* **Refresh**
* PASSWORD/DEVICE\_AUTH: Automatic refresh using refresh tokens
* CLIENT\_CREDENTIALS: New tokens requested using client credentials
## Troubleshooting
[Section titled “Troubleshooting”](#troubleshooting)
* **Authentication Failed**
Verify client ID/secret configuration and issuer URL accessibility.
* **Token Expired**
Check access token lifespan settings in identity provider.
# Authorization
XTDB records which users belong to which roles, managed with standard SQL `GRANT`/`REVOKE` statements (v2.2+).
Role assignment is partly an application concern: an identity provider knows organisational groups, but XTDB knows what they mean for its tables. For deployments whose identity provider can’t carry XTDB’s roles — no IdP-admin access, or role-less consumer OAuth (Google/GitHub) — XTDB holds the role→user mapping itself.
## Granting and revoking roles (v2.2+)
[Section titled “Granting and revoking roles (v2.2+)”](#granting-and-revoking-roles-v22)
```sql
GRANT analyst TO alice;
REVOKE analyst FROM alice;
```
Role and user names are SQL identifiers. For users whose names contain characters outside the plain-identifier set — an OIDC subject, say — use a delimited identifier:
```sql
GRANT analyst TO "google-oauth2|103547991597142817347";
```
Roles don’t need to be created beforehand — granting a role brings it into existence, and both statements are idempotent (re-granting an existing membership, or revoking one that doesn’t exist, is a no-op).
Two restrictions apply:
* Only a [superuser](#superusers) may grant or revoke roles.
* They run against the primary `xtdb` database — they’re rejected on a connection to any other database.
## Inspecting membership
[Section titled “Inspecting membership”](#inspecting-membership)
Membership is surfaced through the standard Postgres catalog views, so `psql`’s `\du` and other Postgres-introspecting tools work:
* `pg_roles`
One row per user and per granted role. Users carry `rolcanlogin = true`; granted roles carry `rolcanlogin = false`.
* `pg_auth_members`
One row per membership, linking a role’s `oid` (`roleid`) to a user’s `oid` (`member`).
```sql
SELECT r.rolname AS role, u.rolname AS member
FROM pg_auth_members m
JOIN pg_roles r ON r.oid = m.roleid
JOIN pg_roles u ON u.oid = m.member;
```
These views reflect the node’s current state.
## Membership history
[Section titled “Membership history”](#membership-history)
Memberships are stored in the `xt.role_membership` table — ordinary bitemporal rows, written only by `GRANT`/`REVOKE` (direct DML on the table is rejected). `REVOKE` closes the membership in system time rather than deleting it, so the history remains queryable for audit:
```sql
-- who was in which role at a past point in time?
SELECT "user", role
FROM xt.role_membership
FOR SYSTEM_TIME AS OF TIMESTAMP '2026-06-01T00:00:00Z';
-- the full grant/revoke history
SELECT "user", role, _system_from, _system_to
FROM xt.role_membership FOR ALL SYSTEM_TIME;
```
A membership granted at `T1` and revoked at `T2` shows in force for any system time in `[T1, T2)`, closed from `T2`, and absent before `T1`.
## Superusers
[Section titled “Superusers”](#superusers)
Granting and revoking roles requires a superuser. The superuser convention is the `xtdb` username:
* `!SingleRootUser`: the root `xtdb` user is the superuser.
* `!UserList`: a configured user named `xtdb` is the superuser.
* `!OpenIdConnect`: no superuser is currently defined, so role membership can’t be managed under OIDC yet.
# Clojure Configuration Cookbook
Changelog (last updated v2.1)
* v2.1: multi-database support
Prior to 2.1, the `:disk-cache` and `:memory-cache` keys were nested under the local/remote storage:
```clojure
{:storage [:local
{;; -- required
:path "/var/lib/xtdb/storage"
;; -- optional
;; :max-cache-bytes 1024
;; :max-cache-entries 536870912
}]}
{:storage [:remote
{;; --required
:object-store [:object-store-implementation {}]
:local-disk-cache "/tmp/local-disk-cache"
;; -- optional
;; :max-cache-entries 1024
;; :max-cache-bytes 536870912
;; :max-disk-cache-percentage 75
;; :max-disk-cache-bytes 107374182400
}]}
```
This document provides examples for the EDN configuration of XTDB components, to be supplied to `xtdb.node/start-node`.
See the [main configuration documentation](/ops/config) for more details.
## Log
[Section titled “Log”](#log)
Main article: [Log](/ops/config/log)
### In-Memory
[Section titled “In-Memory”](#in-memory)
Main article: [in-memory log](/ops/config/log#_in_memory)
This is the default, and can be omitted.
```clojure
{:log [:in-memory
{;; -- optional
;; :instant-src (java.time.InstantSource/system)
}]}
```
### Local disk
[Section titled “Local disk”](#local-disk)
Main article: [local-disk log](/ops/config/log#_local_disk)
```clojure
{:log [:local
{;; -- required
;; accepts `String`, `File` or `Path`
:path "/tmp/log"
;; -- optional
;; accepts `java.time.InstantSource`
;; :instant-src (InstantSource/system)
;; :buffer-size 4096
;; :poll-sleep-duration "PT1S"
}]}
```
### Kafka
[Section titled “Kafka”](#kafka)
Main article: [Kafka](/ops/config/log/kafka)
```clojure
{:log [:kafka
{;; -- required
:bootstrap-servers "localhost:9092"
:topic-name "xtdb-log"
;; -- optional
;; :create-topic? true
;; :poll-duration #xt/duration "PT1S"
;; :properties-file "kafka.properties"
;; :properties-map {}
;; :replication-factor 1
;; :topic-config {}
}]}
```
## Storage
[Section titled “Storage”](#storage)
Main article: [Storage](/ops/config/storage)
### In-Memory
[Section titled “In-Memory”](#in-memory-1)
Main article: [in-memory storage](/ops/config/storage#in-memory)
This is the default, and should be omitted.
### Local disk
[Section titled “Local disk”](#local-disk-1)
Main article: [local-disk storage](/ops/config/storage#local-disk)
```clojure
{:storage [:local
{;; -- required
;; accepts `String`, `File` or `Path`
:path "/var/lib/xtdb/storage"
;; -- optional
;; :max-cache-bytes 536870912
}]}
```
### Remote
[Section titled “Remote”](#remote)
Main article: [remote storage](/ops/config/storage#remote)
```clojure
{:storage [:remote {;; -- required
;; Each object store implementation has its own configuration -
;; see below for some examples.
:object-store [:object-store-implementation {}]}]}
;; -- required for remote storage
;; Local directory to store the working-set cache in.
:disk-cache {;; -- required
;; accepts `String`, `File` or `Path`
:path "/tmp/local-disk-cache"
;; -- optional
;; The maximum proportion of space to use on the filesystem for the diskCache directory
;; (overridden by maxSizeBytes, if set).
:max-size-ratio 0.75
;; The upper limit of bytes that can be stored within the diskCache directory (unset by default).
:max-size-bytes 107374182400}
;; -- optional - in-memory cache created with default config if not supplied
;; configuration for XTDB's in-memory cache
;; if not provided, an in-memory cache will still be created, with the default size
:memory-cache {;; -- optional
;; The maximum proportion of the JVM's direct-memory space to use for the in-memory cache
;; (overridden by `:max-size-bytes`, if set).
:max-size-ratio 0.5
;; unset by default
:max-size-bytes 536870912}
}
```
### S3
[Section titled “S3”](#s3)
Main article: [S3](/ops/aws#storage)
```clojure
{:storage [:remote
{:object-store [:s3
{;; -- required
:bucket "my-bucket"
;; -- optional
;; :prefix "my-xtdb-node"
;; :configurator (reify S3Configurator
;; ...)
}]}]}
```
### Azure Blob Storage
[Section titled “Azure Blob Storage”](#azure-blob-storage)
Main article: [Azure Blob Storage](/ops/azure#storage)
```clojure
{:storage [:remote
{:object-store [:azure
{;; -- required
;; --- At least one of storage-account or storage-account-endpoint is required
:storage-account "storage-account"
;; :storage-account-endpoint "https://storage-account.privatelink.blob.core.windows.net"
:container "xtdb-container"
;; -- optional
;; :prefix "my-xtdb-node"
;; :user-managed-identity-client-id "user-managed-identity-client-id"
}]}]}
```
### Google Cloud Storage
[Section titled “Google Cloud Storage”](#google-cloud-storage)
Main article: [Google Cloud Storage](/ops/google-cloud#storage)
```clojure
{:storage [:remote
{:object-store [:google-cloud
{;; -- required
:project-id "xtdb-project"
:bucket "xtdb-bucket"
;; -- optional
;; :prefix "my-xtdb-node"
}]}]}
```
## Tracing
[Section titled “Tracing”](#tracing)
Main article: [Tracing](/ops/config/monitoring#tracing)
```clojure
{:tracer {;; -- required
:enabled? true
:endpoint "http://localhost:4318/v1/traces"
;; -- optional
;; :service-name "xtdb"
}}
```
# Log
Changelog (last updated v2.2)
* v2.2: earlier epochs rejected at startup
A node whose log is at an *earlier* epoch than its indexed storage now refuses to start, pointing at [Out of Sync Log & Intact Storage](/ops/backup-and-restore/out-of-sync-log). See [Epochs](#epochs).
Previously any epoch difference — in either direction — was treated as the start of a new epoch, logged at INFO, and offset validation was skipped. That is only safe going forwards. Because a message id packs the epoch above the offset, every id on an earlier-epoch log sorts below the storage watermark, so the log replayed as entirely stale and transactions submitted afterwards were acknowledged and then discarded without ever committing or aborting.
To upgrade: nothing to do, unless a node is already running against an earlier epoch than its storage — in which case it will now fail to start, and the recovery is to restore the storage backup that matches the log, or to move forwards to a higher epoch.
* v2.2: source/replica log split
Each database now uses two logs under the hood — a source log (client writes) and a replica log (the indexing leader’s output) — to support [single-writer indexing](/about/dbs-in-xtdb#database-architecture). See the [Kafka log documentation](log/kafka) for configuration details. The in-memory and local-disk log implementations are single-node only and unaffected.
* v2.1: multi-database support
As part of the multi-database support, the Kafka log-clusters were extracted - see the [Kafka log documentation](log/kafka) for more details.
One of the key components of an XTDB node is the log - this is a totally ordered log of all operations that have been applied to the database, generally persistent & shared between nodes.
## Implementations
[Section titled “Implementations”](#implementations)
We offer a number of separate implementations of the log, currently:
* Single-node log implementations, within `xtdb-core`:
* [In memory](#in-memory): transient in-memory log.
* [Local disk](#local-disk): log using the local filesystem.
* [Remote](#remote): multi-node log implementations using a remote service.
## In memory
[Section titled “In memory”](#in-memory)
By default, the log is a transient, in-memory log:
```yaml
## default, no need to explicitly specify
## log: !InMemory
```
If configured as an in-process node, you can also specify an [InstantSource](https://docs.oracle.com/en/java/javase/17/docs/api/java.base/java/time/InstantSource.html) implementation - this is used to override the local machine’s clock when providing a system-time timestamp for each message.
## Local disk
[Section titled “Local disk”](#local-disk)
A single-node persistent log implementation that writes to a local directory.
```yaml
log: !Local
# -- required
# The path to the local directory to store the log in.
# (Can be set as an !Env value)
path: /var/lib/xtdb/log
# -- optional
# The number of entries of the buffer to use when writing to the log.
# bufferSize: 4096
```
If configured as an in-process node, you can also specify an [InstantSource](https://docs.oracle.com/en/java/javase/17/docs/api/java.base/java/time/InstantSource.html) implementation - this is used to override the local machine’s clock when providing a system-time timestamp for each transaction.
## Remote
[Section titled “Remote”](#remote)
A multi-node persistent log implementation that uses a remote service to store the log.
We currently offer the following remote log implementations, available in their own modules:
* [Kafka](log/kafka): a log implementation that uses a Apache Kafka topic to store the log.
## Epochs
[Section titled “Epochs”](#epochs)
An **epoch** is a manually assigned, monotonically increasing integer used to identify the generation of the log in XTDB:
* Epochs allow a cluster to safely reset its log state following partial log loss, corruption, or intentional recovery operations, without requiring full reindexing of storage data.
* If not explicitly configured, nodes assume `epoch = 0`.
### Configuration
[Section titled “Configuration”](#configuration)
To configure an epoch, specify the `epoch` field inside the node’s log configuration:
```yaml
log: !
epoch:
```
Where:
* `` is the chosen log implementation (e.g., `!Kafka`, `!Local`).
* `` is a positive integer greater than the previous epoch.
All nodes within the same cluster **must** use an identical epoch value at startup.
Epochs only move forwards. A node started with an epoch *below* the one its storage has already indexed refuses to start, and points at [Out of Sync Log & Intact Storage](/ops/backup-and-restore/out-of-sync-log) — there is no way to reconcile the two, because everything on the earlier log ranks below what storage has already processed.
#### Bumping an Epoch
[Section titled “Bumping an Epoch”](#bumping-an-epoch)
Caution
Beginning a new epoch will make the recovery of unindexed transactions from any previous epoch nearly impossible. Therefore, it is recommended to only increment the epoch after you are confident that the original log is irrecoverable and you understand the potential consequences.
When applying a new epoch:
* Shut down all XTDB nodes to prevent divergence.
* Update each node’s configuration with the new `epoch` value.
* (Optional) Prepare a clean log backend if required (e.g., create a new Kafka topic or clear the local log directory).
* Restart all nodes simultaneously with the updated configuration.
Once restarted, nodes will begin writing to the new log generation, and prior log history will be disregarded.
# Kafka
Changelog (last updated v2.2)
* v2.2: single-writer support — two topics per database
[Single-writer indexing](/about/dbs-in-xtdb#database-architecture) requires two Kafka topics per database: a **source log** for client writes and a **replica log** for the indexing leader’s resolved output. XTDB uses Kafka’s consumer-group rebalance protocol to elect the leader for each database, and fences split-brain writes to the replica log by term — see [‘Leader election and fencing’](#leader-election-and-fencing) below.
Previously, a database used a single Kafka topic, and every indexer node consumed it independently. With single-writer, only the elected leader consumes the source topic; followers tail the replica topic instead.
Upgrading:
* The replica topic defaults to `${topic}-replica` and auto-creates when `autoCreateTopic` is enabled, so existing deployments need no configuration changes to pick it up.
* If multiple XTDB deployments share a Kafka cluster, give each a distinct `groupId` on its `!Kafka` cluster config — otherwise their consumer groups collide and leadership is assigned across deployment boundaries.
* ACL-restricted topics need `Describe` / `Read` / `Write` on both the source and replica topics.
* v2.2: `logClusters` renamed to `remotes`
The Kafka cluster is now declared under [`remotes`](/ops/config#remotes) rather than `logClusters`.
`logClusters` is deprecated but still honoured, so existing config keeps working — rename to `remotes` when convenient.
* v2.1: multi-database support
As part of multi-database support, `logClusters` were extracted in v2.1.
Prior to that, the configuration in `logClusters` was within the `log`:
```yaml
log: !Kafka
bootstrapServers: "localhost:9092"
topic: "xtdb-log"
# autoCreateTopic: true
# pollDuration: "PT1S"
# propertiesFile: "kafka.properties"
# propertiesMap:
# became
logClusters:
kafkaCluster: !Kafka
bootstrapServers: "localhost:9092"
# pollDuration: "PT1S"
# propertiesFile: "kafka.properties"
# propertiesMap:
log: !Kafka
cluster: kafkaCluster
topic: "xtdb-log"
# autoCreateTopic: true
```
[Apache Kafka](https://kafka.apache.org/) can be used as XTDB’s message log. Each database uses two Kafka topics — a **source log** for client writes and a **replica log** for the indexing leader’s resolved output — plus Kafka’s consumer-group protocol to elect the leader for that database automatically. See [‘Database architecture’](/about/dbs-in-xtdb#database-architecture) for the concepts; this page covers how to set Kafka up to back them.
## Setup
[Section titled “Setup”](#setup)
1. Add a dependency to the `com.xtdb/xtdb-kafka` module in your dependency manager.
2. On your Kafka cluster, XTDB requires **two topics per database** — a source log and a replica log:
* Both can be created manually and provided to the node config, or XTDB can create them automatically.
* If allowing XTDB to create the topics **automatically**, ensure that the connection properties supplied to the XTDB node have the appropriate permissions to create topics — XTDB will create each with the expected configuration values (single partition, `LogAppendTime` timestamps). Auto-created topics are **unreplicated**, so create them yourself for production.
3. Configure the topics and the broker — see [Settings](#settings) for which of these XTDB sets for you and which are yours.
4. XTDB should be configured to use the topics, and the Kafka cluster they’re hosted on. It should also be authorised to perform all of the necessary operations on both.
* For configuring the Kafka module to authenticate with the Kafka cluster, use the `propertiesFile` or `propertiesMap` configuration options to supply the necessary connection properties. See the [example configuration](#auth_example) below.
* If the Kafka cluster is using **ACLs**, the XTDB node needs:
* `Describe` / `Read` / `Write` on **both** the source and replica topics.
## Settings
[Section titled “Settings”](#settings)
Both topics — source and replica — take the same settings.
XTDB applies the topic settings it depends on only when it creates a topic itself (`autoCreateTopic: true`), so a topic you pre-create is entirely yours to configure. The one setting it verifies on a topic that already exists is the partition count; the node refuses to start otherwise.
| Setting | Scope | Set by | Value |
| --------------------------- | ------------------------ | ------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| partition count | topic | XTDB on create, **verified** on an existing topic | Exactly `1`. A single partition is what makes the log strictly ordered and lets leader election assign it to one consumer at a time. |
| `message.timestamp.type` | topic | XTDB on create, **not** verified afterwards | `LogAppendTime`, so a record’s timestamp is when the broker appended it rather than when a producer sent it. Set it yourself on a pre-created topic. |
| replication factor | topic | XTDB creates with `1` | Pre-create the topic with `3` or more for production — auto-create is unreplicated. |
| `min.insync.replicas` | topic | You | `> 1`, to make writes quorum-acknowledged. |
| `retention.ms` | topic | You | Messages need not live on the log permanently. The default of 1 day suits most deployments; 1 week is a reasonable starting point where extra caution against data loss is wanted. |
| `max.message.bytes` | topic | You | The 1MB default is fit for purpose unless your transactions are larger. |
| `cleanup.policy` | topic | You | Leave at the default `delete` — XTDB never reads compacted messages. |
| `offsets.retention.minutes` | **broker, cluster-wide** | You | Governs how long the leader-election consumer group survives with every XTDB node down, after which `termEpoch` has to be raised — see [‘Recreating the consumer group’](#recreating-the-consumer-group-v22). Seven days by default. This is not a per-topic setting, it applies to every consumer group on the cluster, and managed Kafka services often fix it. |
XTDB also sets its own producer and consumer properties — idempotent, `acks=all` writes, `read_committed` reads, `auto.offset.reset=none`, cooperative sticky assignment, and offset commits that keep the leader-election group alive. `propertiesMap` and `propertiesFile` can override these, but they are chosen deliberately and overriding them can break leader election.
## Configuration
[Section titled “Configuration”](#configuration)
To use the Kafka module, include the following in your node configuration:
```yaml
## We first declare the Kafka cluster under `remotes`:
remotes:
# You can define multiple Kafka clusters here, and refer to them by name in the log configuration.
# Here we define a single Kafka cluster named "kafkaCluster".
kafkaCluster: !Kafka
# -- required
# A comma-separated list of host:port pairs to use for establishing the
# initial connection to the Kafka cluster.
# (Can be set as an !Env value)
bootstrapServers: "localhost:9092"
# -- optional
# The maximum time to block waiting for records to be returned by the Kafka consumer.
# pollDuration: "PT1S"
# Path to a Java properties file containing Kafka connection properties,
# supplied directly to the Kafka client.
# (Can be set as an !Env value)
# propertiesFile: "kafka.properties"
# A map of Kafka connection properties, supplied directly to the Kafka client.
# propertiesMap:
# Consumer-group ID used for per-database leader election (v2.2+).
# Defaults to "xtdb" — set a distinct value per deployment when multiple XTDB
# deployments share a Kafka cluster, so their consumer groups don't collide.
# groupId: "xtdb"
## For the database, we then create a log using the Kafka cluster we just defined:
log: !Kafka
# -- required
# The name of the Kafka cluster to use for the source log.
cluster: kafkaCluster
# Name of the Kafka topic to use for the source log.
# (Can be set as an !Env value)
topic: "xtdb-log"
# -- optional
# The name of the Kafka cluster to use for the replica log (v2.2+).
# Defaults to the same cluster as the source log.
# replicaCluster: kafkaCluster
# Name of the Kafka topic to use for the replica log (v2.2+).
# Defaults to "${topic}-replica".
# replicaTopic: "xtdb-log-replica"
# Whether or not to automatically create the topics, if they do not already exist.
# Applies to both the source and replica topics.
# autoCreateTopic: true
# Declares that the consumer group backing leader election has been recreated (v2.2+).
# Raise it — never lower it — when that happens; see 'Recreating the consumer group' below.
# termEpoch: 0
```
### SASL Authenticated Kafka Example
[Section titled “SASL Authenticated Kafka Example”](#sasl-authenticated-kafka-example)
The following piece of node configuration demonstrates the following common use case:
* Cluster is secured with SASL - authentication is required from the module.
* Topic has already been created manually.
* Configuration values are being passed in as environment variables.
```yaml
remotes:
kafkaCluster: !Kafka
bootstrapServers: !Env KAFKA_BOOTSTRAP_SERVERS
propertiesMap:
sasl.mechanism: PLAIN
security.protocol: SASL_SSL
sasl.jaas.config: !Env KAFKA_SASL_JAAS_CONFIG
log: !Kafka
cluster: kafkaCluster
topic: !Env XTDB_LOG_TOPIC
autoCreateTopic: false
```
The `KAFKA_SASL_JAAS_CONFIG` environment variable will likely contain a string similar to the following, and should be passed in as a secret value:
```plaintext
org.apache.kafka.common.security.plain.PlainLoginModule required username="username" password="password";
```
## Leader election and fencing
[Section titled “Leader election and fencing”](#leader-election-and-fencing)
The [‘Database architecture’](/about/dbs-in-xtdb#database-architecture) page describes XTDB’s single-writer indexing model in terms of properties — exactly one leader per database, automatic failover, followers as hot standbys. This section describes how the Kafka module actually enforces those properties.
### Leader election via consumer groups
[Section titled “Leader election via consumer groups”](#leader-election-via-consumer-groups)
Every XTDB node running the Kafka log subscribes to each database’s source topic via a shared Kafka consumer group (`groupId`, defaulting to `"xtdb"`). Kafka’s rebalance protocol then assigns each topic’s single partition to exactly one consumer across the group — that consumer is the leader for that database. When a leader node stops (crash, network partition, long GC pause) or a new node joins the group, Kafka triggers a rebalance and the assignment moves.
Because all databases on a node share one consumer group via a single underlying consumer, Kafka’s `CooperativeStickyAssignor` distributes leaderships evenly across the cluster — e.g. with three nodes serving three databases, each node ends up leader for one database and follower for the other two.
### Fencing by term
[Section titled “Fencing by term”](#fencing-by-term)
Each leader stamps every record it writes to the replica log with a **term** — the generation number Kafka assigns its consumer-group membership, which strictly increases each time the assignment moves. A leader applies and acknowledges a write only once it has read that write *back* from the replica log at its own term, with no higher-term record ahead of it.
If a rebalance has meanwhile moved leadership on, the incoming leader writes at a higher term. The outgoing leader reads that higher-term record back, recognises it has been superseded, and resigns — its own unconfirmed writes are never acknowledged. Followers apply the highest term they have seen and discard lower-term records. So at most one leader’s writes are ever confirmed for a given database, even across an unclean handover — without relying on Kafka transactions.
### Recreating the consumer group (v2.2+)
[Section titled “Recreating the consumer group (v2.2+)”](#recreating-the-consumer-group-v22)
A term is not that generation number alone: it pairs it with a `termEpoch`, which orders one incarnation of the consumer group against the next. The generation orders elections *within* one incarnation; the epoch is what survives the group being recreated.
`generationId` restarts at 1 whenever the group is recreated, below the terms already on the replica log. The broker deletes a consumer group once it has no members left and its committed offsets have expired, so how long a group survives with every XTDB node down is governed by the broker’s `offsets.retention.minutes` — seven days by default. This turns on *members*, not traffic: a cluster that is up with no writes flowing keeps its group indefinitely, however long it idles.
`offsets.retention.minutes` is a broker setting rather than a topic one, so raising it for longer planned outages affects every consumer group on the cluster — and managed Kafka services often fix it. Raise `termEpoch` on the log config whenever the group is recreated anyway — an outage past the retention period, a `groupId` change, or a group you delete deliberately:
```yaml
log: !Kafka
cluster: kafkaCluster
topic: "xtdb-log"
termEpoch: 1
```
A node whose term is already fenced refuses to lead rather than indexing into a log every reader ignores, and its error names the current epoch:
```plaintext
leader term 0.1 is already fenced by 0.9 on the replica log — the leader-election
counter has regressed (a recreated Kafka consumer group, or a restarted local log),
so bump the log's termEpoch above 0
```
Raise `termEpoch`, never lower it: a lower value puts the new leader back below the terms on the log.
### Sharing a Kafka cluster across deployments
[Section titled “Sharing a Kafka cluster across deployments”](#sharing-a-kafka-cluster-across-deployments)
Leader election runs through a Kafka consumer group (`groupId`, defaulting to `"xtdb"`). If you run multiple XTDB deployments against the same Kafka cluster (e.g. staging + prod, or multiple tenants), give each a distinct `groupId` — otherwise they join the same group and Kafka assigns their topics’ partitions across both deployments’ nodes.
```yaml
remotes:
kafkaCluster: !Kafka
bootstrapServers: "localhost:9092"
groupId: "prod"
```
## Kafka Log Durability
[Section titled “Kafka Log Durability”](#kafka-log-durability)
Kafka-backed logs offer strong durability, but require tuning and backup strategies to align with your recovery objectives.
### Recommended Kafka Settings
[Section titled “Recommended Kafka Settings”](#recommended-kafka-settings)
The replication factor, `min.insync.replicas` and `retention.ms` are the three that bear on data loss, and all three are yours rather than XTDB’s — see [Settings](#settings). Size `retention.ms` and `retention.bytes` so that unindexed messages survive long enough to be backed up or flushed.
See [Apache Kafka documentation](https://kafka.apache.org/documentation/) for details.
Managed services like [Confluent Cloud](https://www.confluent.io/confluent-cloud/) may offer higher guarantees and simplified observability.
### Strategies for Kafka Log Backup
[Section titled “Strategies for Kafka Log Backup”](#strategies-for-kafka-log-backup)
There are three main ways to safeguard your XTDB Kafka log:
#### Point-in-Time Backups
[Section titled “Point-in-Time Backups”](#point-in-time-backups)
Caution
Always back up the storage module **before** backing up the log. Restoring a log without its corresponding flushed storage state may result in inconsistency and force an epoch reset.
* Take backups **after** a successful XTDB storage flush.
* Capture **only committed** Kafka messages (exclude in-flight transactions).
* Use Kafka tooling or snapshotting scripts.
#### Continuous Replication
[Section titled “Continuous Replication”](#continuous-replication)
Use Kafka-native tools to replicate log data between clusters:
* [MirrorMaker](https://kafka.apache.org/documentation/#basic_ops_mirror_maker)
* [Confluent Replicator](https://docs.confluent.io/platform/current/multi-dc-deployments/replicator/index.html)
This allows for:
* Geo-redundancy
* Low-RPO disaster recovery
* Hot-standby clusters
Note: Replication **does not** replace backups --- it only increases availability.
#### Application-Level Transaction Replay
[Section titled “Application-Level Transaction Replay”](#application-level-transaction-replay)
XTDB can rebuild its state from upstream sources (event logs, message queues) used to submit transactions.
Advantages:
* Independent recovery source
* Replay can be filtered, transformed, or validated
* Fills gaps between backup and failure
# Monitoring & Observability
XTDB offers a suite of tools & templates to facilitate monitoring and observability. These include a **Healthz Server** for health checks, **Metrics** for performance insights, integrations with third-party monitoring systems and **Grafana** dashboards for visualizing the health and performance of XTDB nodes.
## Healthz Server
[Section titled “Healthz Server”](#healthz-server)
The Healthz Server is a lightweight HTTP server that provides health indicators and metrics, making it useful for monitoring in containerized and orchestrated environments. It runs on a node that has a `healthz` block in its configuration.
### Configuration
[Section titled “Configuration”](#configuration)
```yaml
healthz:
# Port to run the Healthz Server on.
# Default: 0, i.e. an available port chosen at startup (can be set as an !Env value).
port: 8080
```
Anything that needs to reach the Healthz Server at a known address — a container health check, a Kubernetes probe, a Prometheus scrape target — needs the port set explicitly. The XTDB container images and Helm charts set it to 8080.
### Health Routes
[Section titled “Health Routes”](#health-routes)
The following routes are exposed by the Healthz Server and can be used to monitor the node’s status:
* `/healthz/started`: Indicates whether the node has completed startup and has caught up on indexing.
* Recommended for [**startup probes**](https://kubernetes.io/docs/concepts/configuration/liveness-readiness-startup-probes/#startup-probe).
* We recommend configuring a generous initial timeout, as it waits for indexing to stabilize.
* `/healthz/alive`: Confirms the application is running without critical errors.
* Suitable for [**liveness probes**](https://kubernetes.io/docs/concepts/configuration/liveness-readiness-startup-probes/#liveness-probe).
* `/healthz/ready`: Signals that the node is ready to process requests.
* Suitable for [**readiness probes**](https://kubernetes.io/docs/concepts/configuration/liveness-readiness-startup-probes/#readiness-probe).
## Metrics
[Section titled “Metrics”](#metrics)
XTDB provides various metrics for monitoring the health and performance of its nodes. These metrics are available via Prometheus and can also be integrated with cloud-based observability services.
### Prometheus Metrics
[Section titled “Prometheus Metrics”](#prometheus-metrics)
By default, XTDB nodes expose metrics in the [Prometheus](https://prometheus.io/) format. These can be accessed at the following endpoint on the **Healthz Server**:
```plaintext
:/metrics
```
Metrics that relate to a specific database are tagged with `db=` (v2.2+), so dashboards can slice per database on nodes serving more than one.
### Cloud Integrations
[Section titled “Cloud Integrations”](#cloud-integrations)
XTDB nodes can be configured to report metrics to the following cloud-based monitoring services:
* [Azure Application Insights](../azure#monitoring)
* [AWS CloudWatch](../aws#monitoring)
## Grafana Dashboards
[Section titled “Grafana Dashboards”](#grafana-dashboards)
XTDB provides [pre-built Grafana dashboards](https://github.com/xtdb/xtdb/tree/main/monitoring/public-dashboards) for monitoring the health and performance of XTDB clusters and individual nodes.
For more information on how to set these up on Grafana, see the [“Monitoring XTDB with Grafana”](../guides/monitoring-with-grafana) guide.
## Tracing
[Section titled “Tracing”](#tracing)
XTDB supports distributed tracing using OpenTelemetry, providing introspection into query execution and performance.
Traces are sent via the OTLP (OpenTelemetry Protocol) HTTP endpoint to your tracing backend (e.g., Grafana Tempo, Jaeger, etc).
Tracing is disabled by default.
### Configuration
[Section titled “Configuration”](#configuration-1)
```yaml
tracer:
# -- required
# Enable OpenTelemetry tracing.
enabled: true
# OTLP HTTP endpoint for sending traces.
# (Can be set as an !Env value)
endpoint: "http://localhost:4318/v1/traces"
# -- optional
# Service name identifier for traces.
# (Can be set as an !Env value)
# serviceName: "xtdb"
# Enable tracing for queries. Default: true
# queryTracing: true
# Enable tracing for transactions. Default: true
# transactionTracing: true
```
For more information on viewing and analyzing traces with Grafana, see the [“Monitoring XTDB with Grafana”](../guides/monitoring-with-grafana#distributed-tracing-with-tempo) guide.
# Storage
Changelog (last updated v2.1)
* v2.1: multi-database support
As part of the multi-database support, the `memoryCache` and `diskCache` keys were extracted from the local/remote storage.
Prior to that, the keys related to the `memoryCache` and `diskCache` were nested under the local/remote storage:
```yaml
storage: !Local
path: /var/lib/xtdb/storage
# maxCacheEntries: 1024
# maxCacheBytes: 536870912
# became
storage: !Local
path: /var/lib/xtdb/storage
memoryCache:
# maxSizeRatio: 0.5
# maxSizeBytes: 536870912
```
```yaml
storage: !Remote
objectStore:
localDiskCache: /var/lib/xtdb/remote-cache
# maxCacheEntries: 1024
# maxCacheBytes: 536870912
# maxDiskCachePercentage: 75
# maxDiskCacheBytes: 107374182400
# became
storage: !Remote
objectStore:
diskCache:
path: /var/lib/xtdb/remote-cache
# maxSizeRatio: 0.75
# maxSizeBytes: 107374182400
memoryCache:
# maxSizeRatio: 0.5
# maxSizeBytes: 536870912
```
One of the key components of an XTDB node is the storage module - used to store the data and indexes that make up the database.
We offer the following implementations of the storage module:
* [In memory](#in-memory): transient in-memory storage.
* [Local disk](#local-disk): storage persisted to the local filesystem.
* [Remote](#remote): storage persisted remotely.
## In memory
[Section titled “In memory”](#in-memory)
By default, the storage module is configured to use transient, in-memory storage.
```yaml
## default, no need to explicitly specify
## storage: !InMemory
```
## Local disk
[Section titled “Local disk”](#local-disk)
A persistent storage implementation that writes to a local directory, also maintaining an in-memory cache of the working set.
```yaml
storage: !Local
# -- required
# The path to the local directory to persist the data to.
# (Can be set as an !Env value)
path: /var/lib/xtdb/storage
### -- optional
## configuration for XTDB's in-memory cache
## if not provided, an in-memory cache will still be created, with the default size
memoryCache:
# The maximum proportion of the JVM's direct-memory space to use for the in-memory cache (overridden by maxSizeBytes, if set).
# maxSizeRatio: 0.5
# The maximum number of bytes to store in the in-memory cache (unset by default).
# maxSizeBytes: 536870912
```
## Remote
[Section titled “Remote”](#remote)
A persistent storage implementation that:
* Persists data remotely to a provided, cloud based object store.
* Maintains an local-disk cache and in-memory cache of the working set.
```yaml
storage: !Remote
# -- required
# Configuration of the Object Store to use for remote storage
# Each of these is configured separately - see below for more information.
objectStore:
### -- required
## Local directory to store the working-set cache in.
diskCache:
## -- required
# (Can be set as an !Env value)
path: /var/lib/xtdb/remote-cache
## -- optional
# The maximum proportion of space to use on the filesystem for the diskCache directory (overridden by maxSizeBytes, if set).
# maxSizeRatio: 0.75
# The upper limit of bytes that can be stored within the diskCache directory (unset by default).
# maxSizeBytes: 107374182400
### -- optional
## configuration for XTDB's in-memory cache
## if not provided, an in-memory cache will still be created, with the default size
memoryCache:
# The maximum proportion of the JVM's direct-memory space to use for the in-memory cache (overridden by maxSizeBytes, if set).
# maxSizeRatio: 0.5
# The maximum number of bytes to store in the in-memory cache (unset by default).
# maxSizeBytes: 536870912
```
Each Object Store implementation is configured separately - see the individual cloud platform documentation for more information:
* [AWS](../aws#storage)
* [Azure](../azure#storage)
* [Google Cloud](../google-cloud#storage)
# Kafka Connect External Source
## Prerequisites
[Section titled “Prerequisites”](#prerequisites)
A Kafka topic carrying the records you want to sync to XTDB.
Caution
Records on partitions other than partition 0 are not consumed, so the topic should have a single partition.
## Configuration
[Section titled “Configuration”](#configuration)
Configured by [attaching a secondary database](/about/dbs-in-xtdb#attachingdetaching-secondary-databases-v21) with the additional `externalSource` options. It consumes a topic via a [`!Kafka` remote](#remote), applies a [Connect config](#connect-config) to each record, and writes through an [indexer](#indexers):
```sql
ATTACH DATABASE my_db WITH $$
externalSource: !KafkaConnect
# The alias of the !Kafka remote holding the cluster connection details.
remote: my_kafka_remote
# The Kafka topic to consume records from.
topic: my_upstream_topic
# Kafka Connect converter and transform options.
# key.converter and value.converter are required.
connectConfig:
key.converter: org.apache.kafka.connect.storage.StringConverter
value.converter: org.apache.kafka.connect.json.JsonConverter
value.converter.schemas.enable: "false"
transforms: unwrap
transforms.unwrap.type: org.apache.kafka.connect.transforms.ExtractField$Value
transforms.unwrap.field: payload
# The indexer used to index records.
indexer: !Docs
table: my_table
$$
```
### Remote
[Section titled “Remote”](#remote)
Kafka cluster connection details are stored in a `!Kafka` [remote](/ops/config#remotes). See the [Kafka](/ops/config/log/kafka) documentation for the available options.
```yaml
remotes:
my_kafka_remote: !Kafka
bootstrapServers: "localhost:9092"
```
### Connect config
[Section titled “Connect config”](#connect-config)
`connectConfig` is a map of [Kafka Connect](https://kafka.apache.org/documentation/#connect) options applied to each record before it is indexed. XTDB accepts the keys below; any other key is rejected.
```yaml
connectConfig:
# Required: the fully-qualified converter class for record keys and values.
key.converter:
value.converter:
# Options passed to a converter, with the key.converter./value.converter. prefix stripped.
value.converter.